RL ⇨ Tabular Learning Algorithms
My implementation of chapers 2-8 in Richard Sutton & Andrew Barto's book An Introduction to Reinforcement Learning.
GitHub RepoA k-armed Bandit Problem
Action-value Methods
The 10-armed Testbed
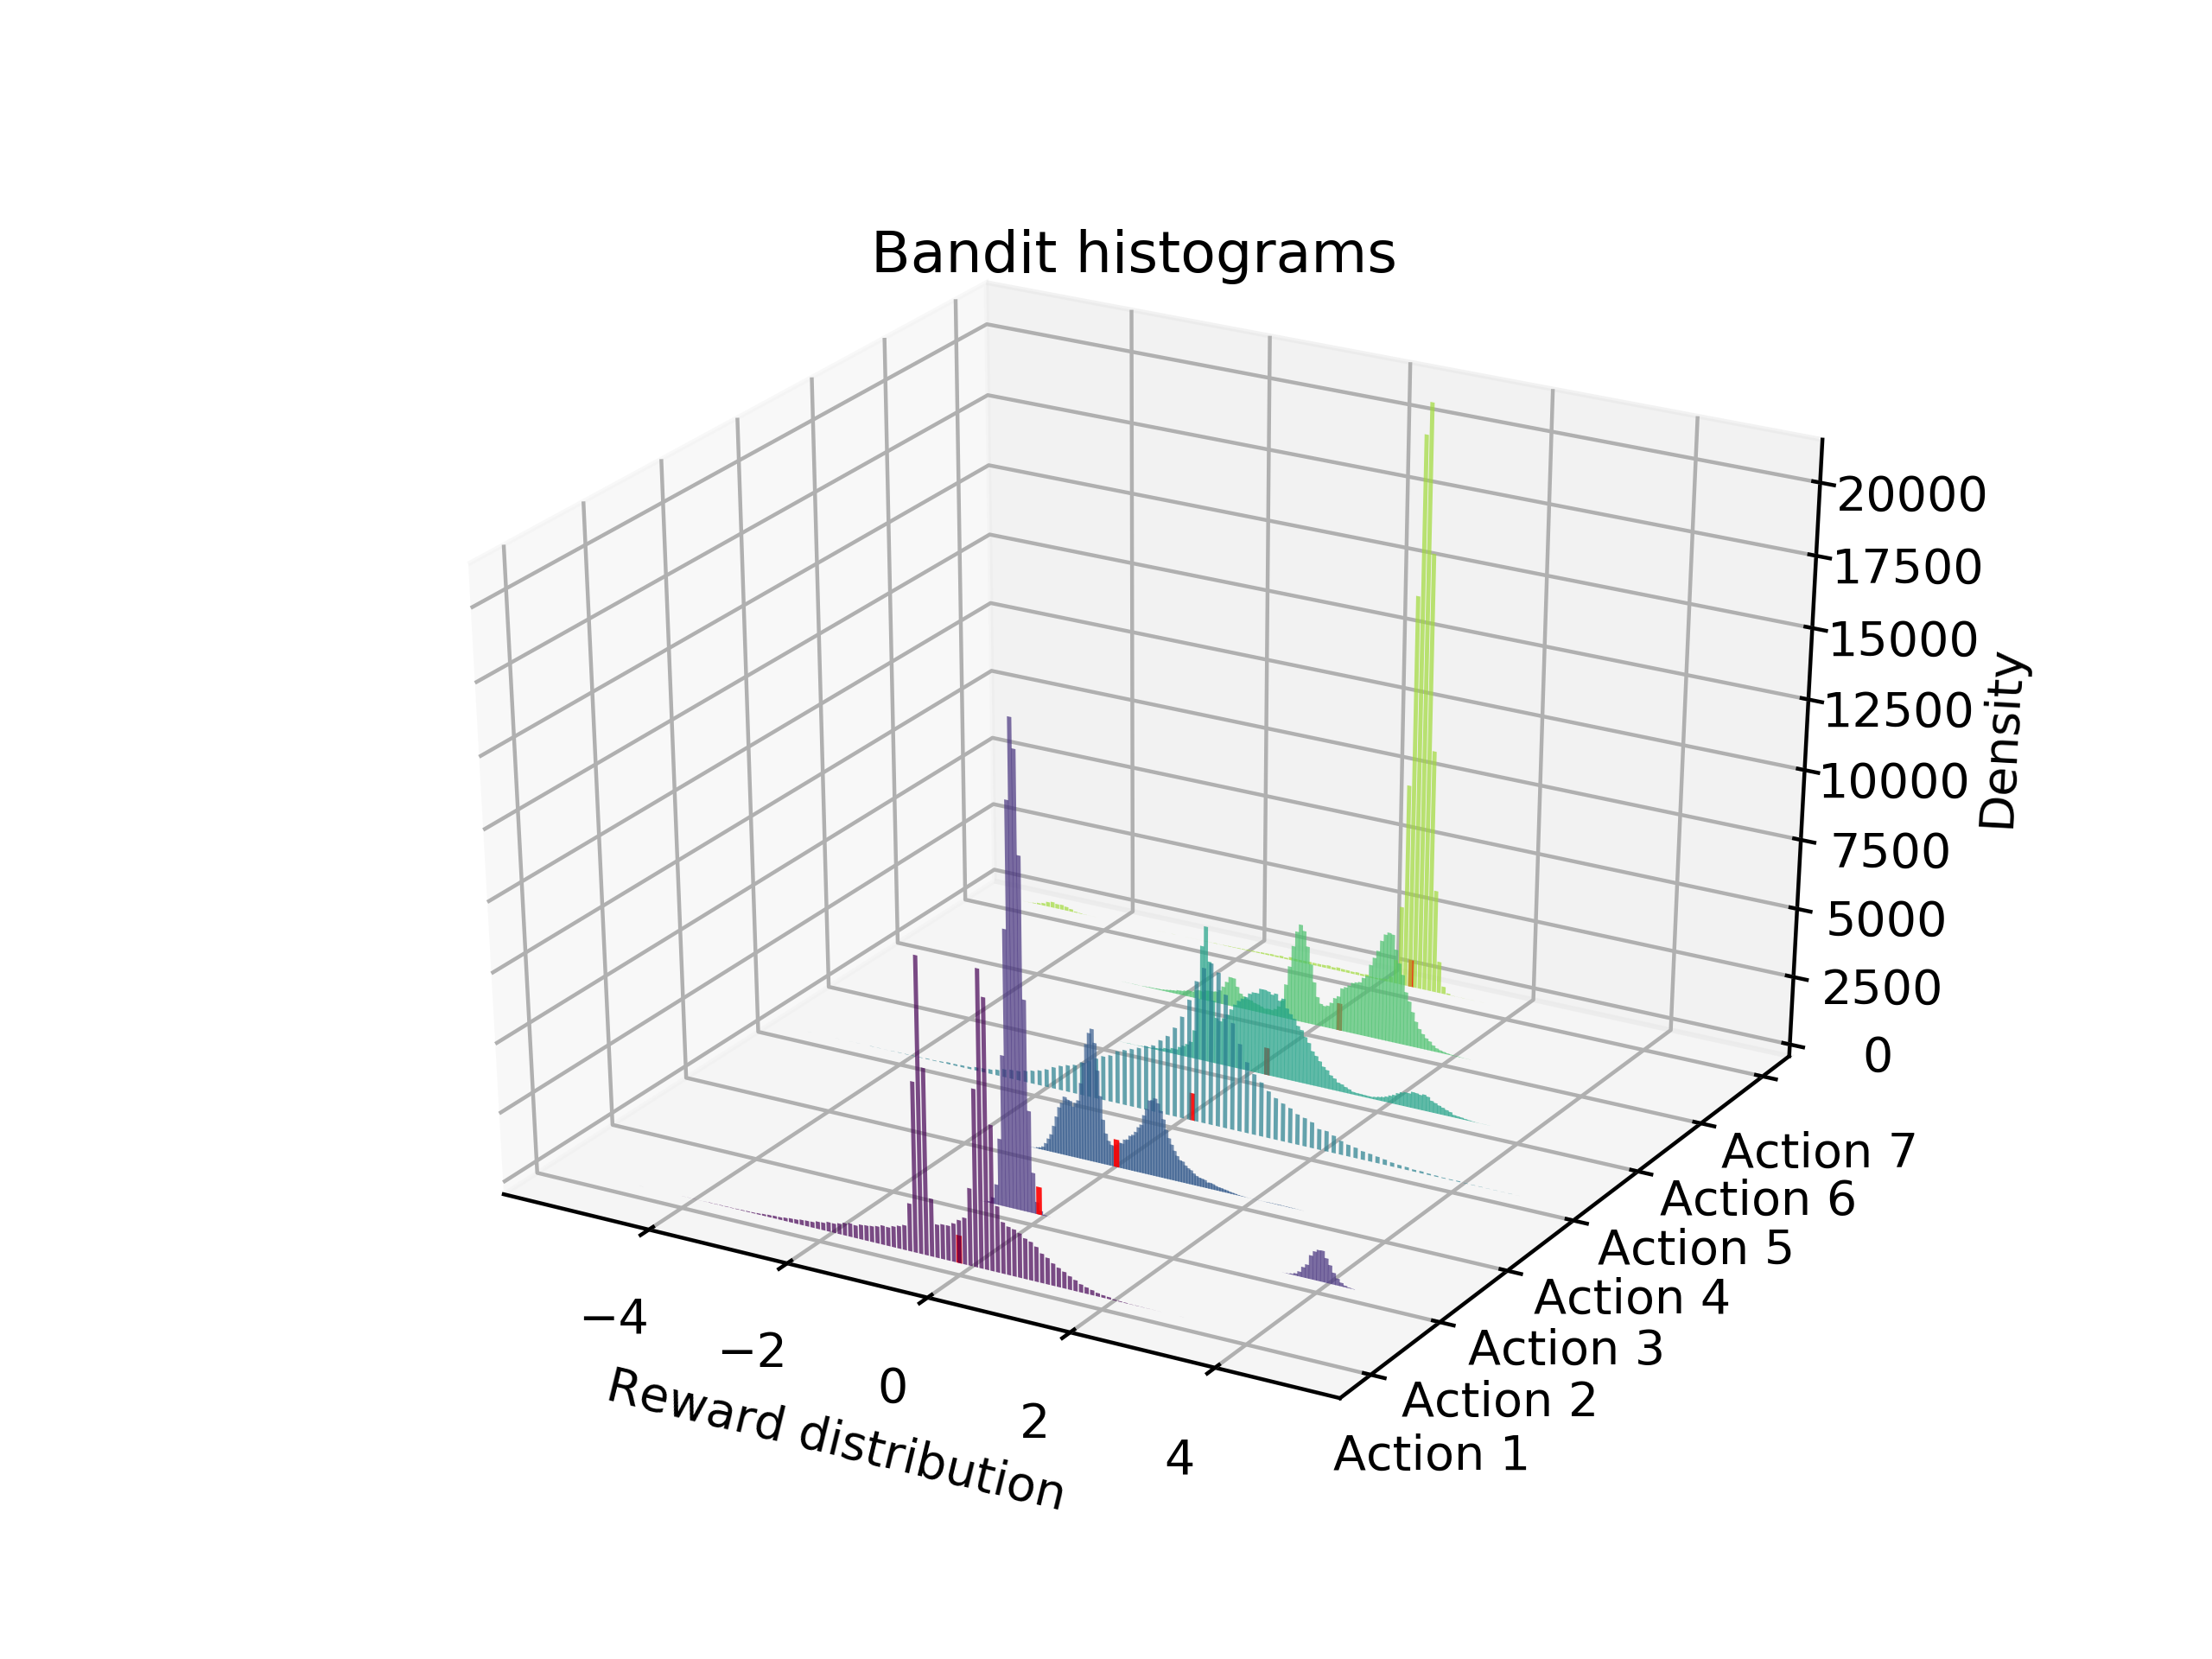
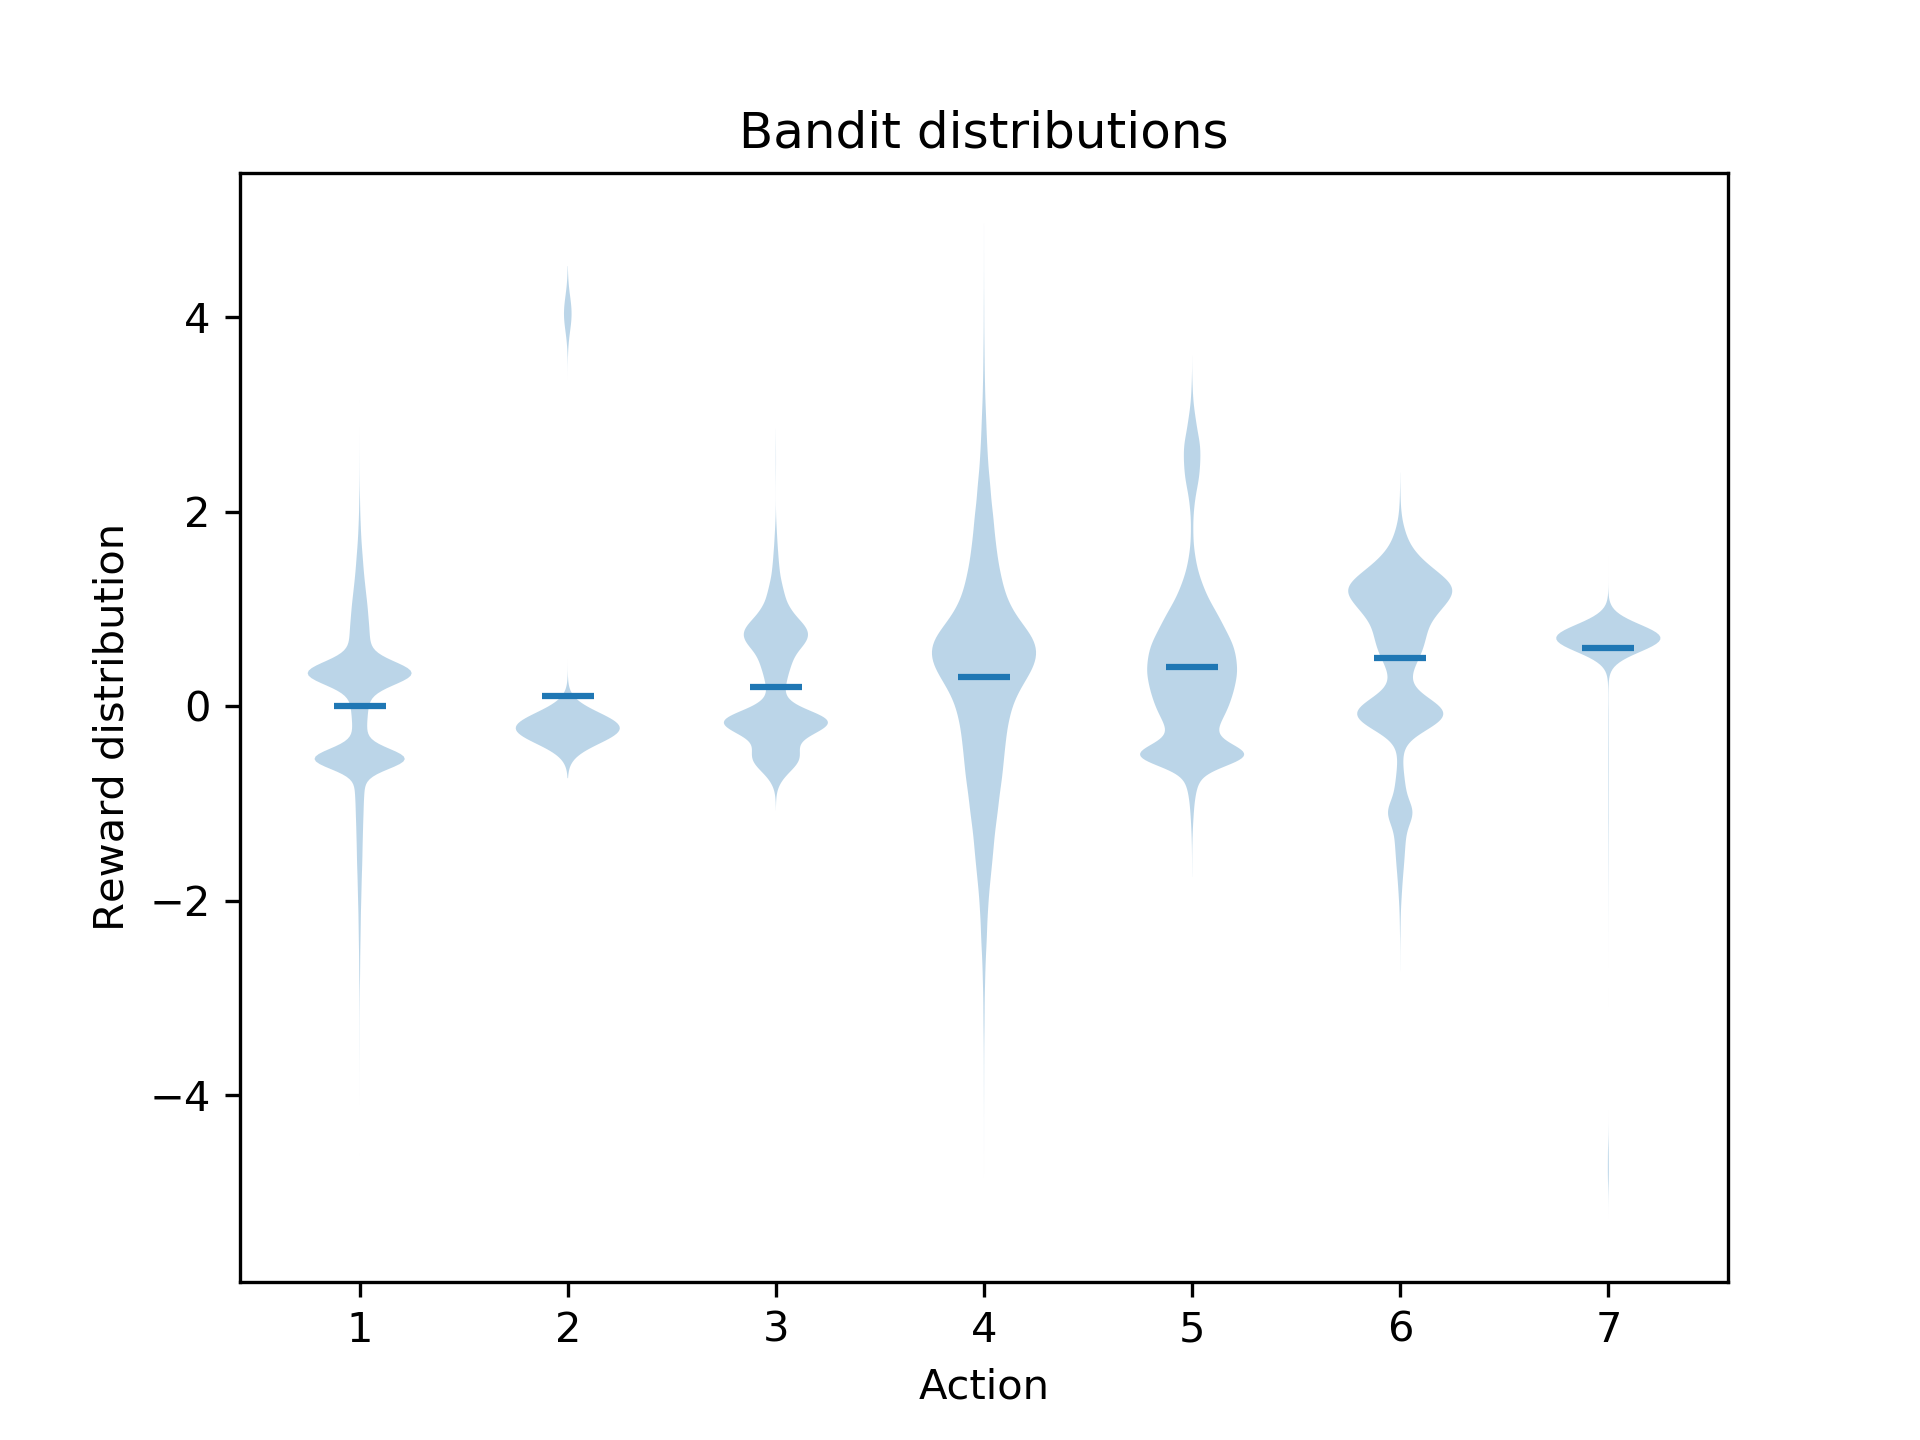
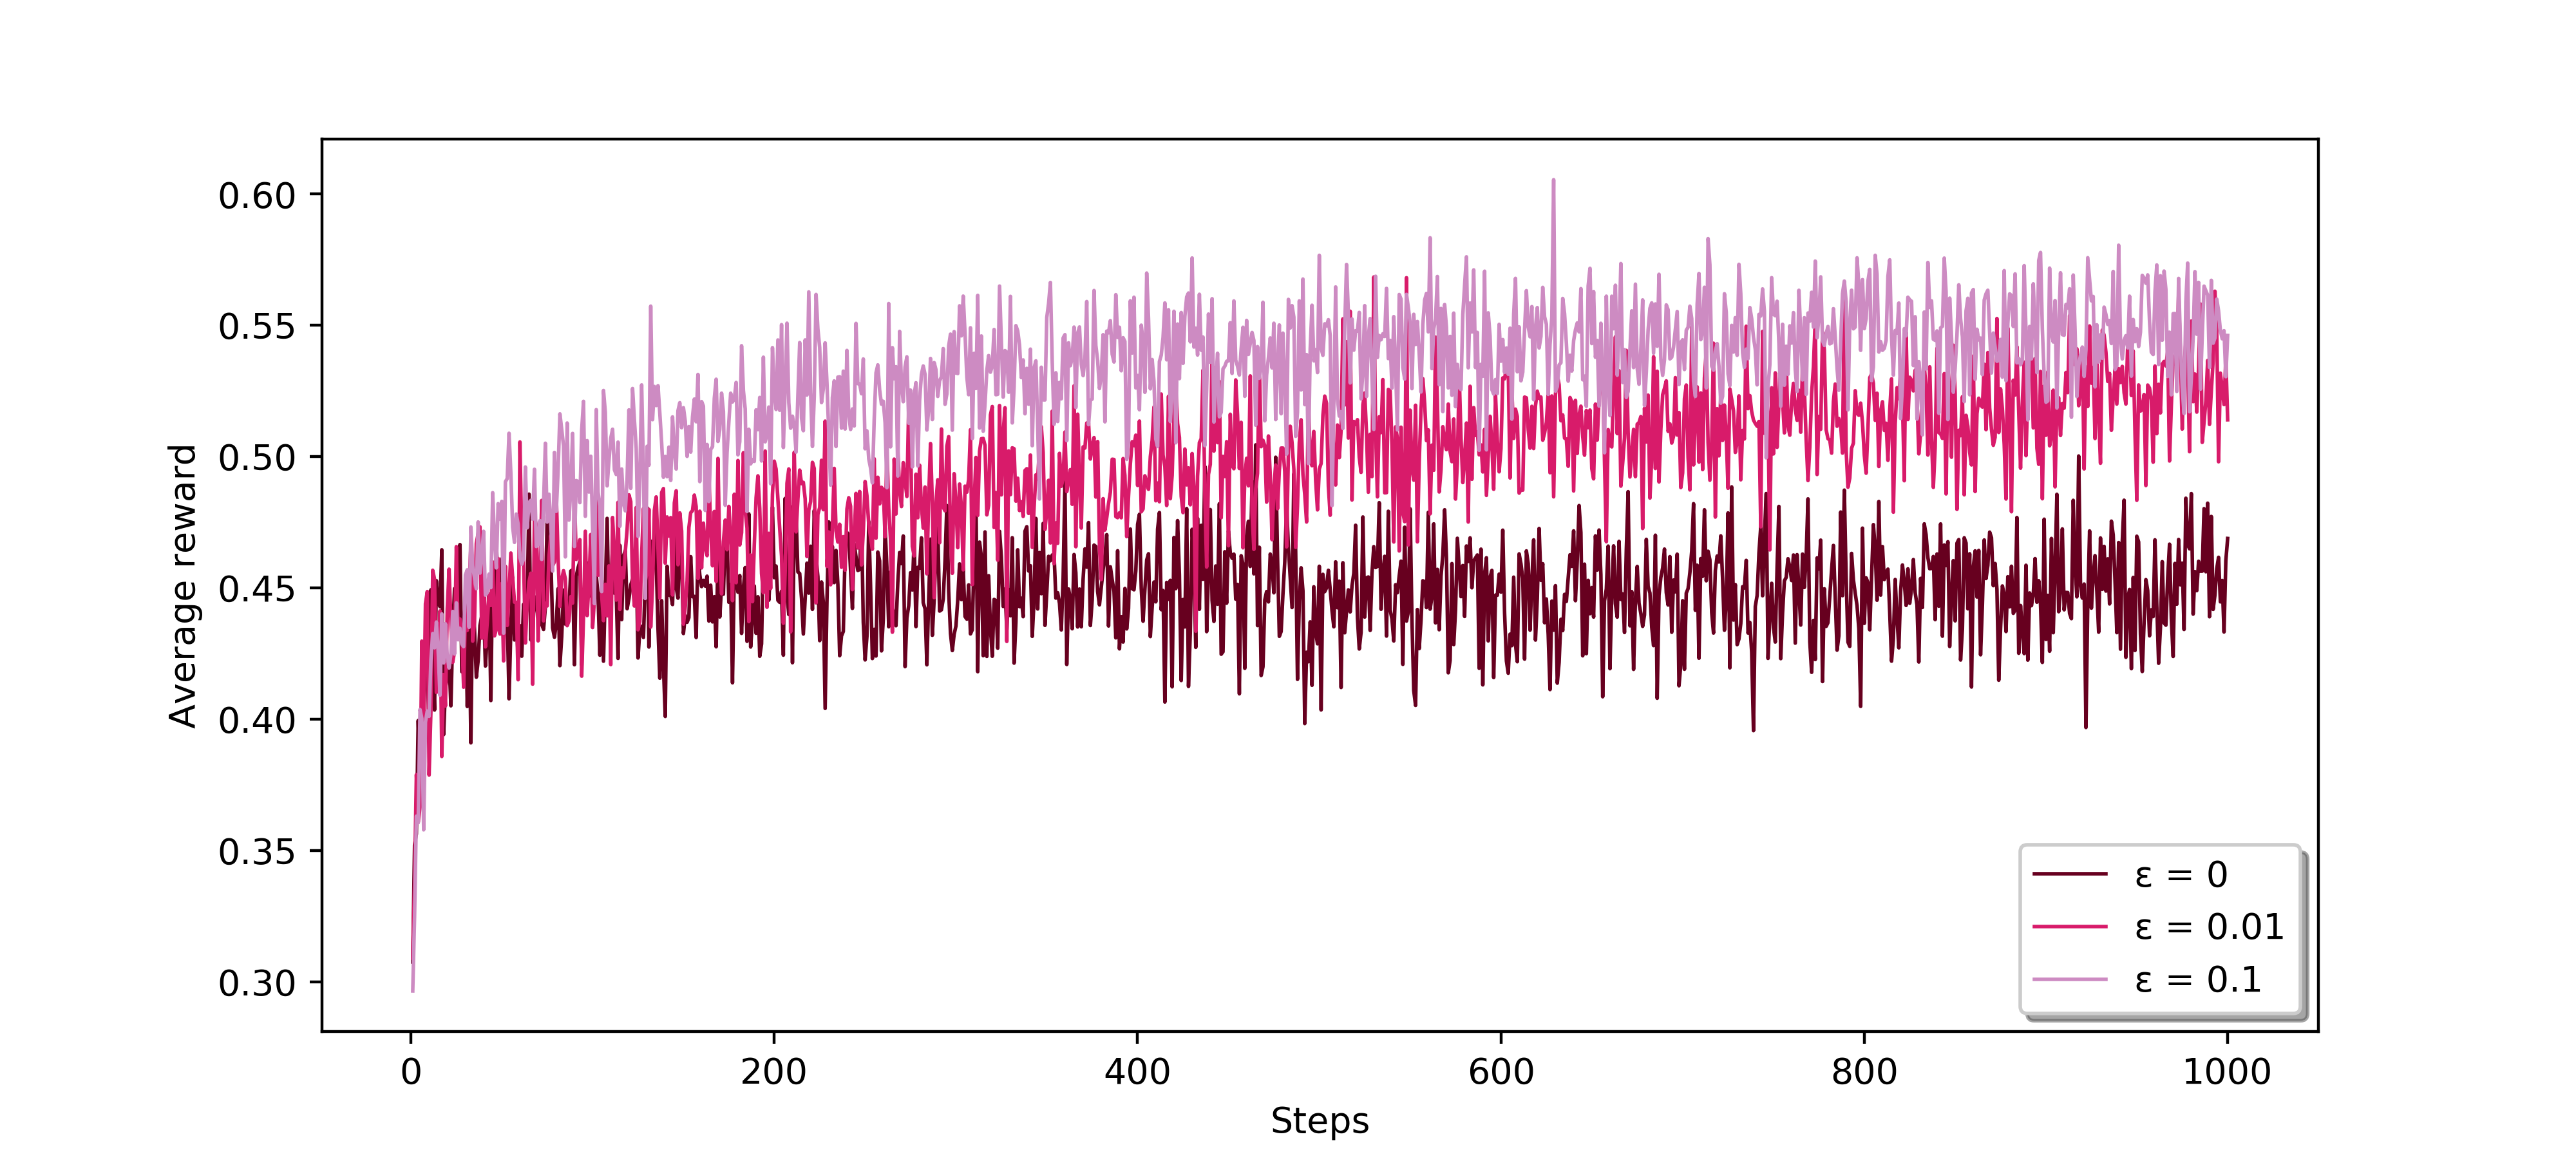
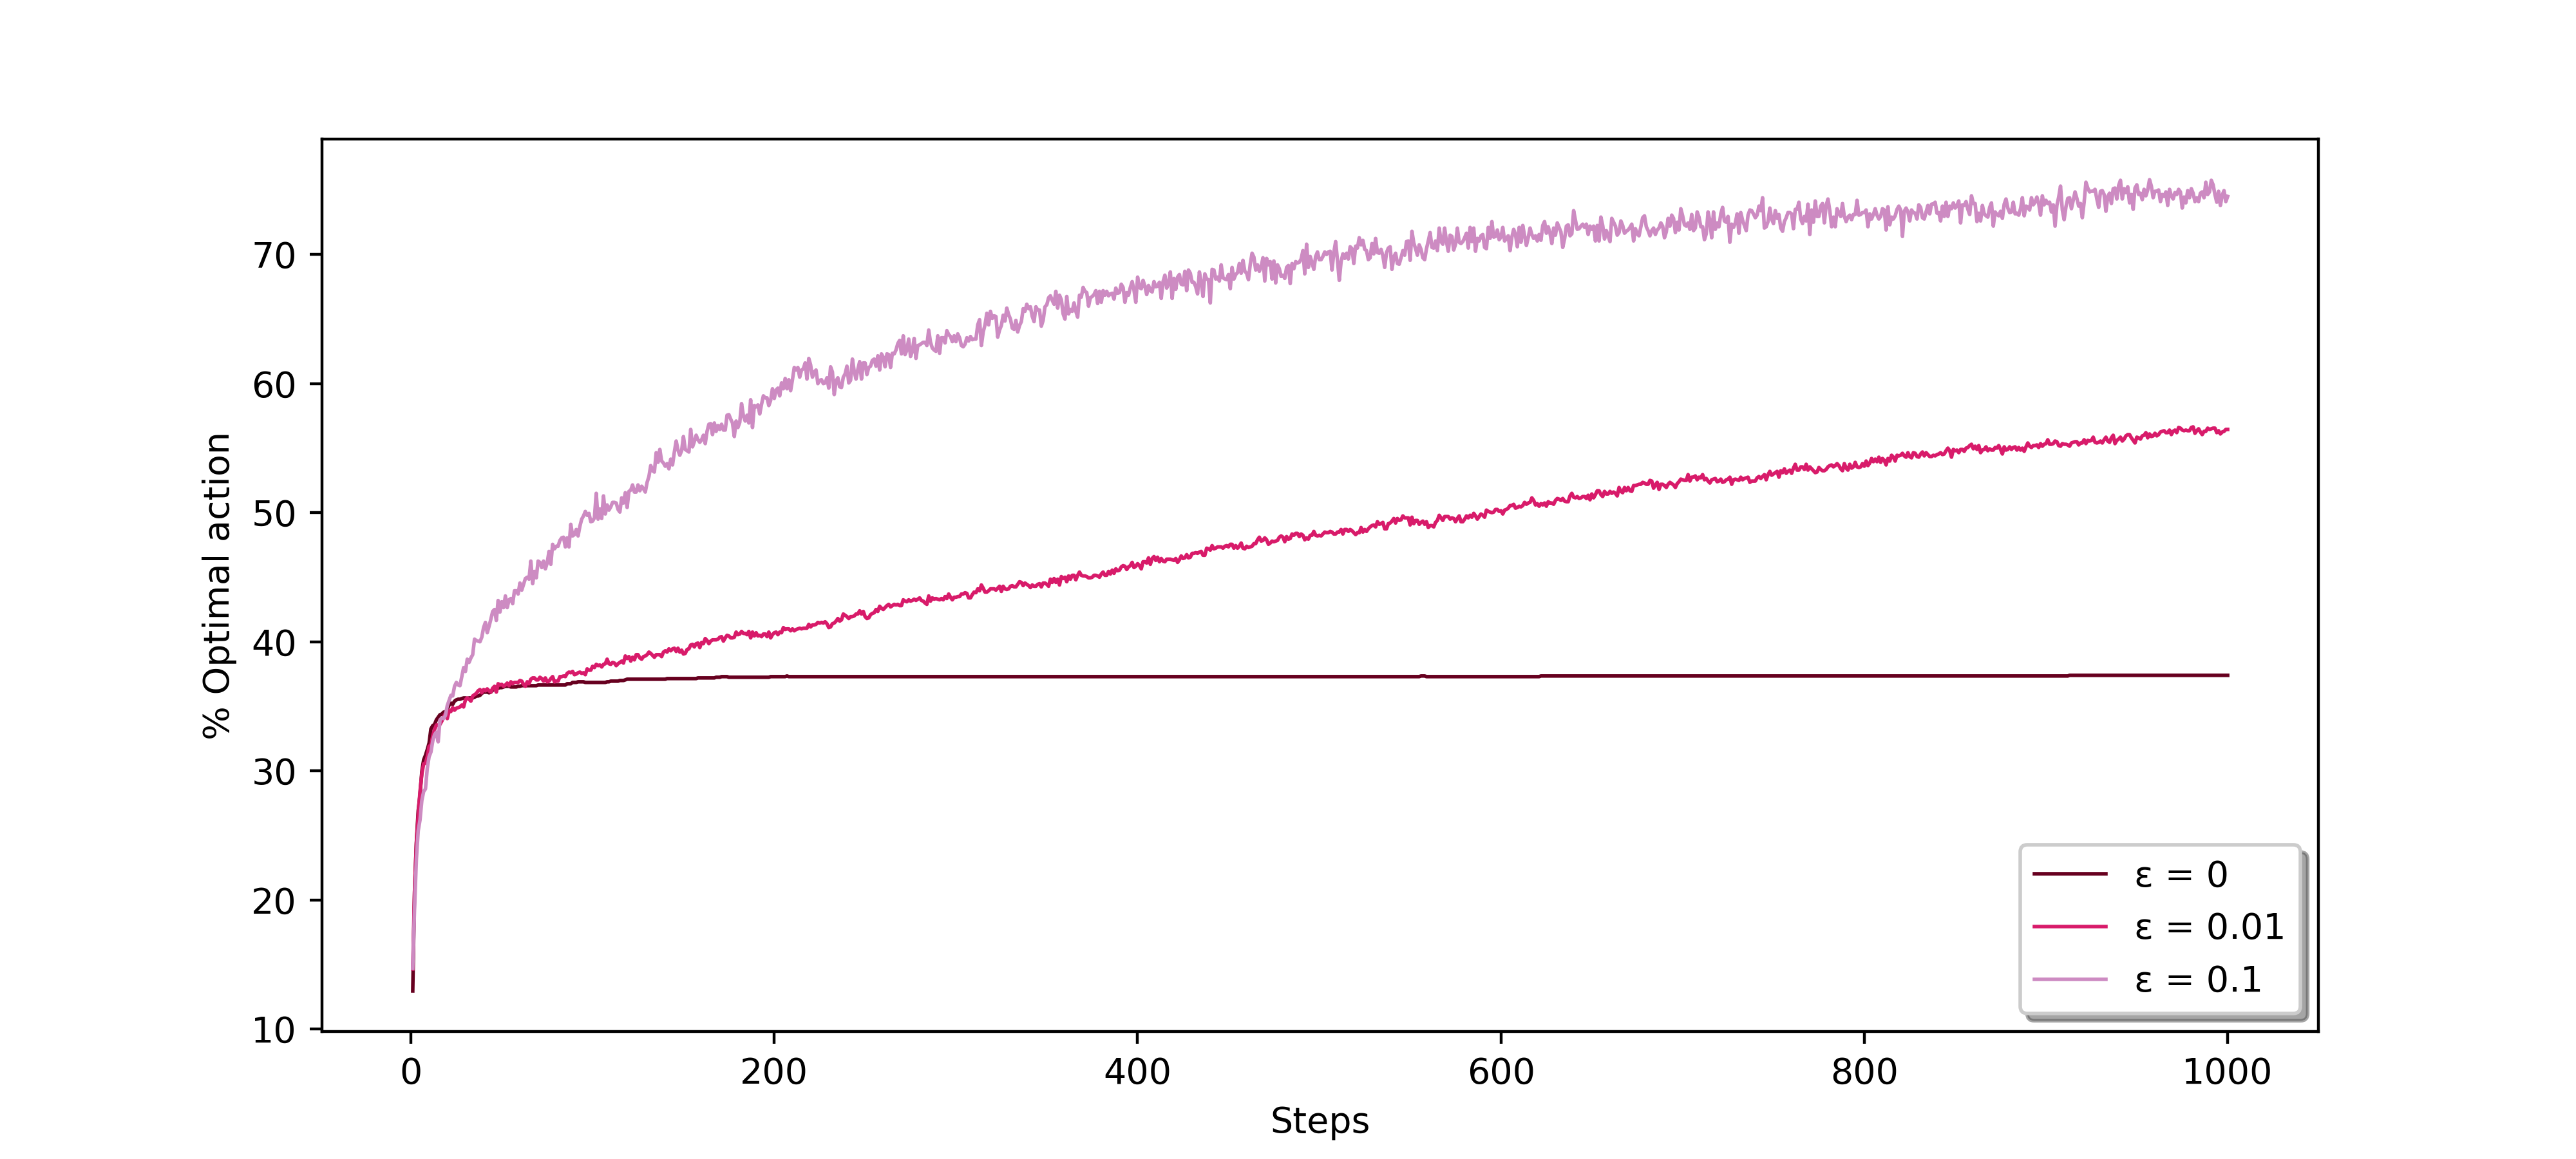
ε-greedy action-value methods on the 10-armed testbed.
Incremental Implementation
Tracking a Nonstationary Problem
Optimistic Initial Values
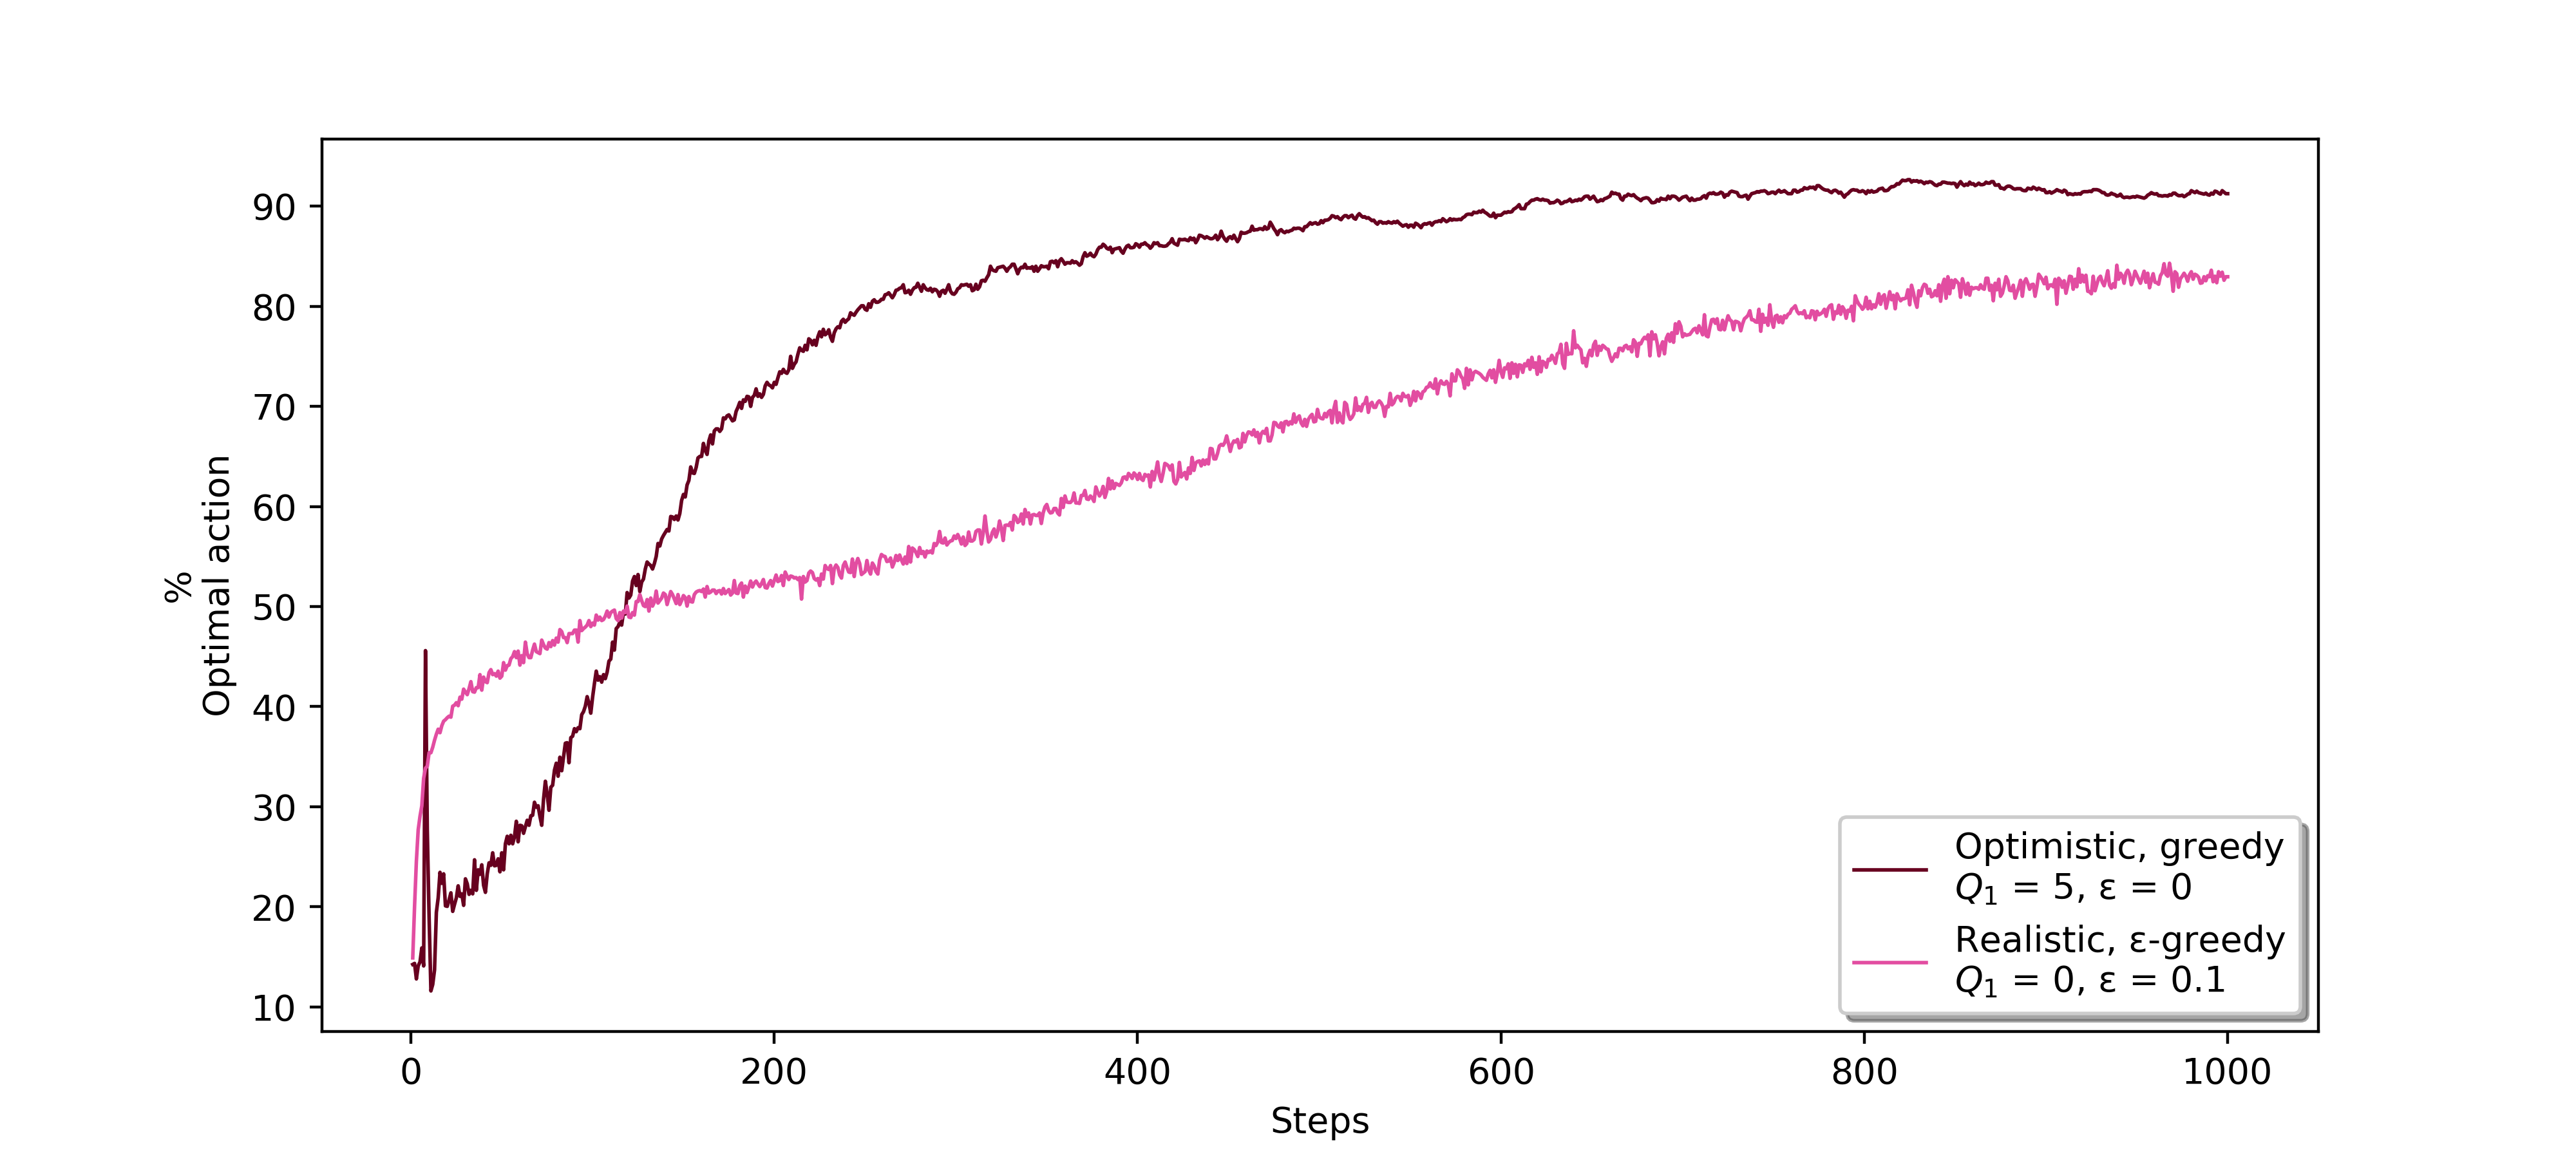
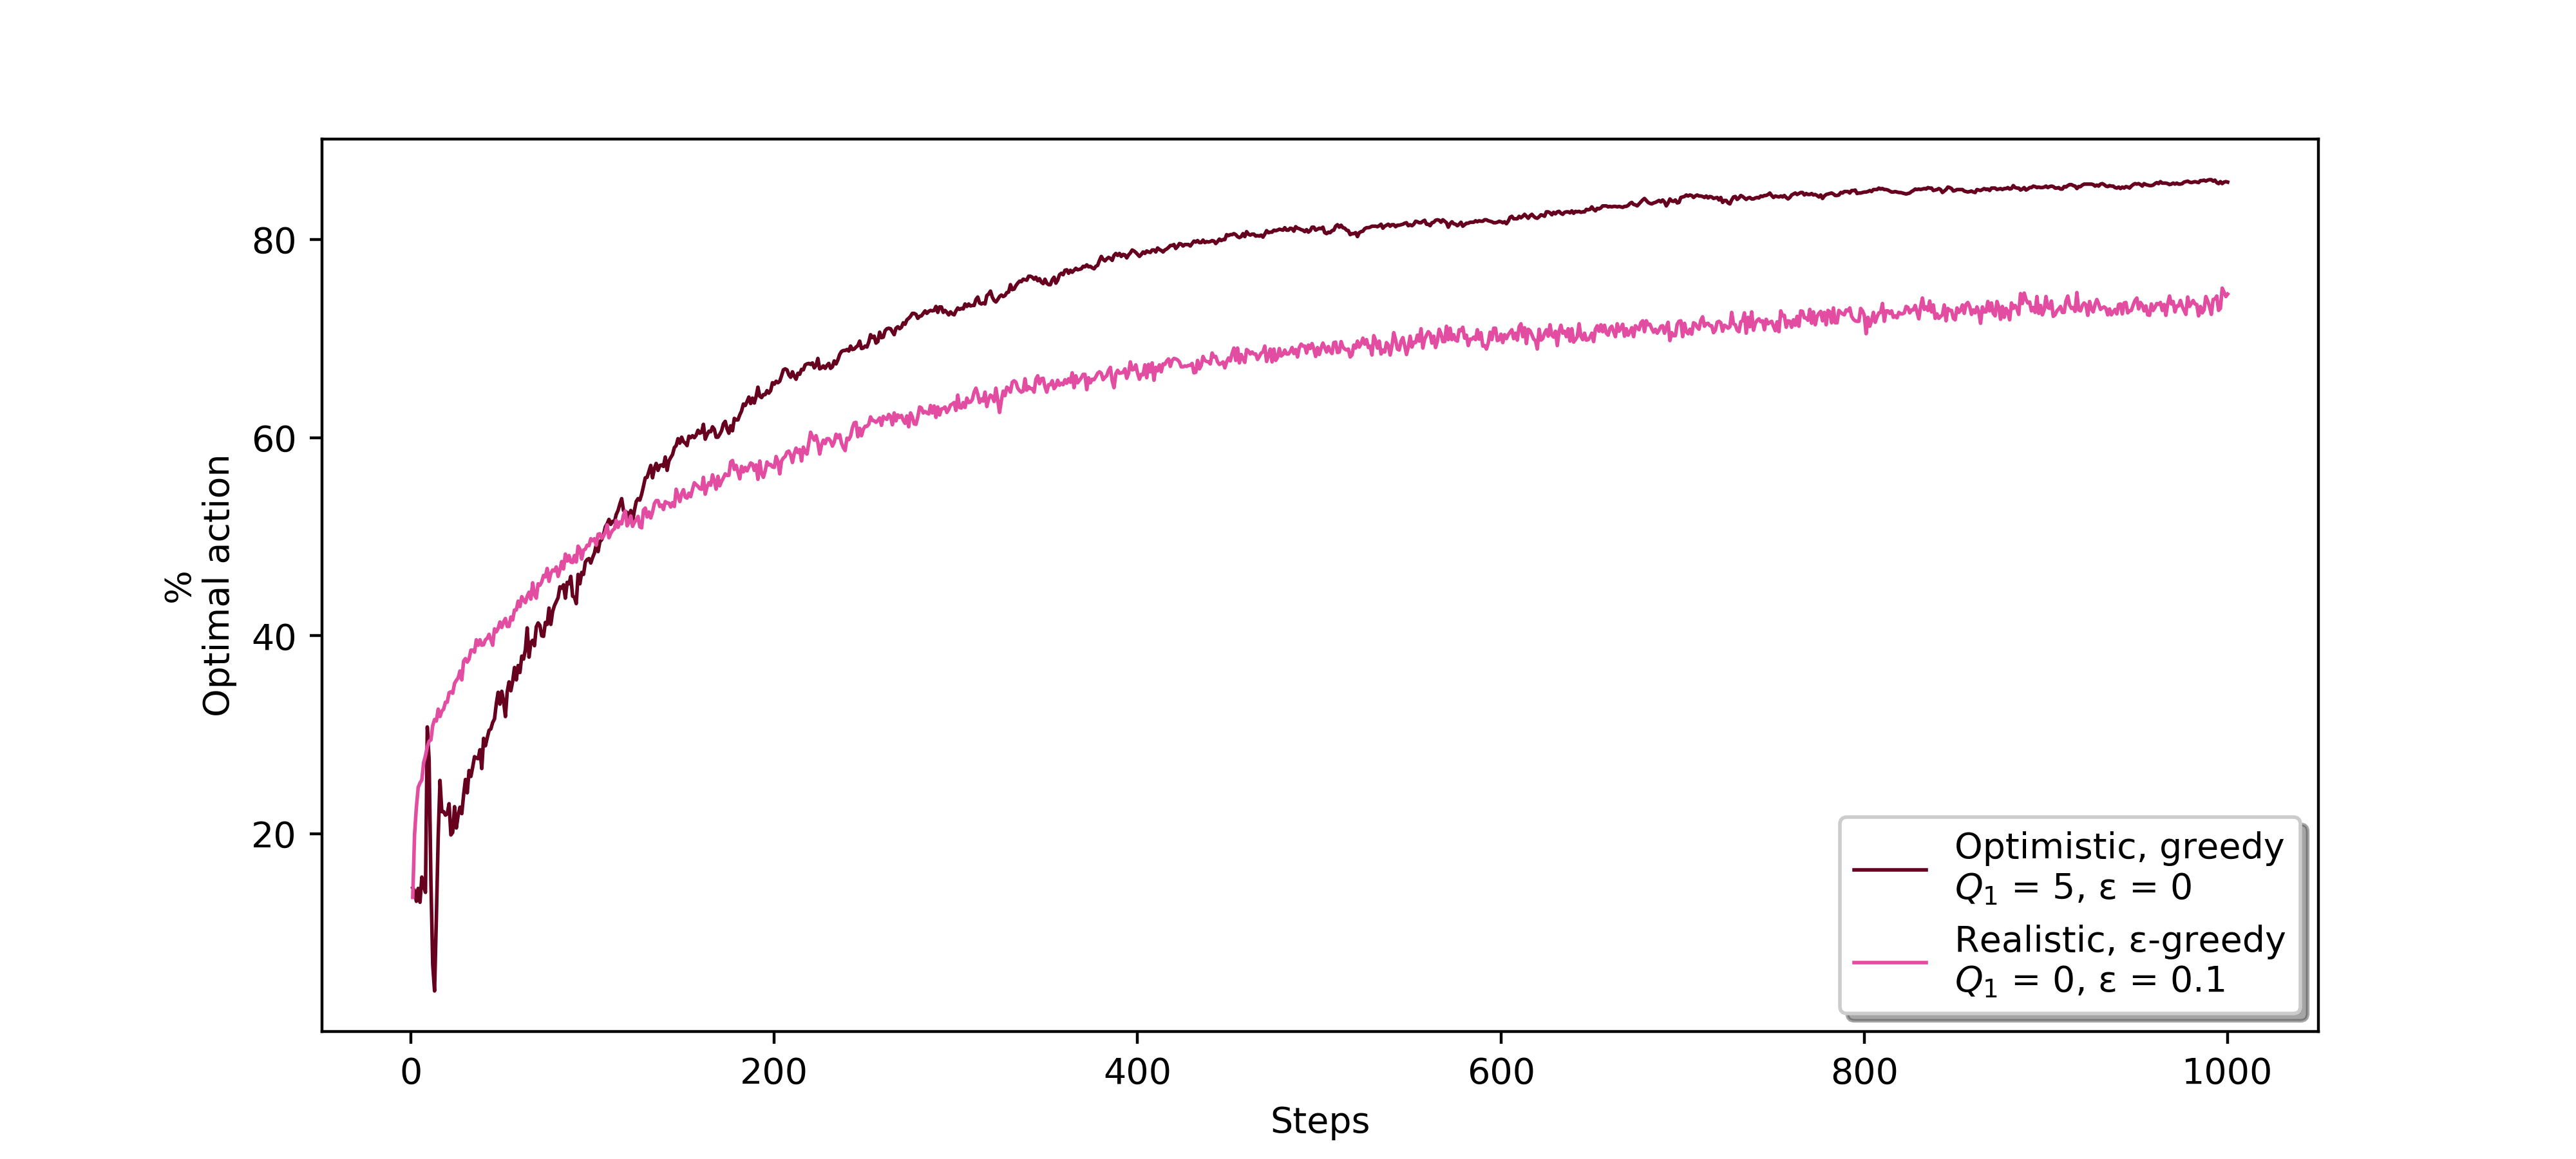
Optimistic initial action-value estimates on the 10-armed testbed, and on my distributions on the right. Step-size: α = 0.1.
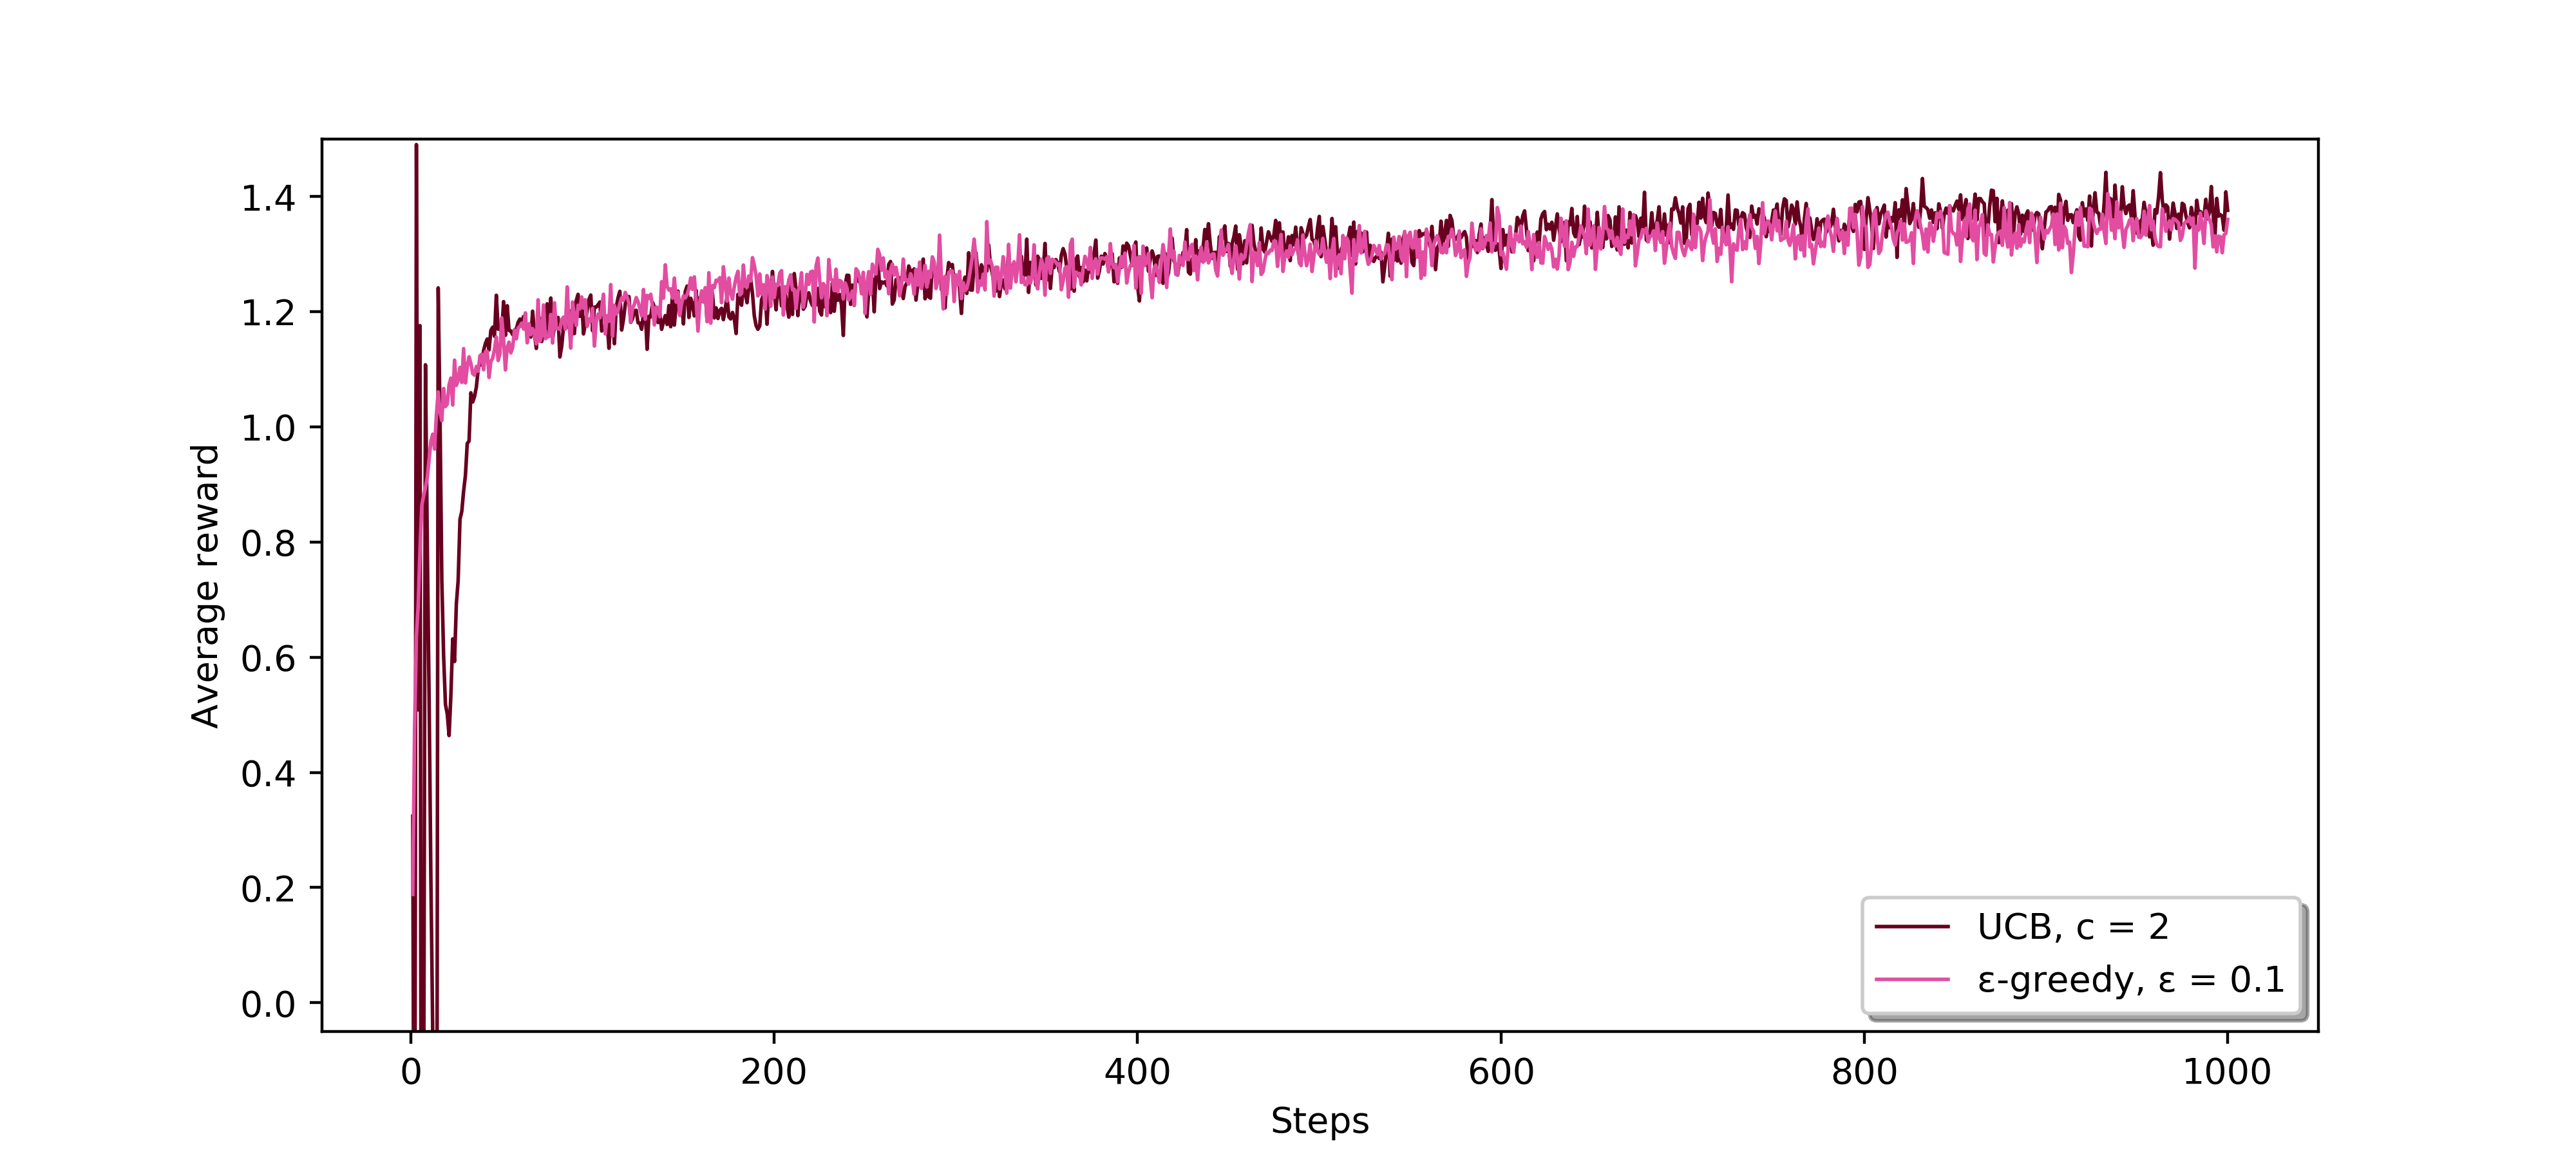
Upper-Confidence-Bound Action Selection
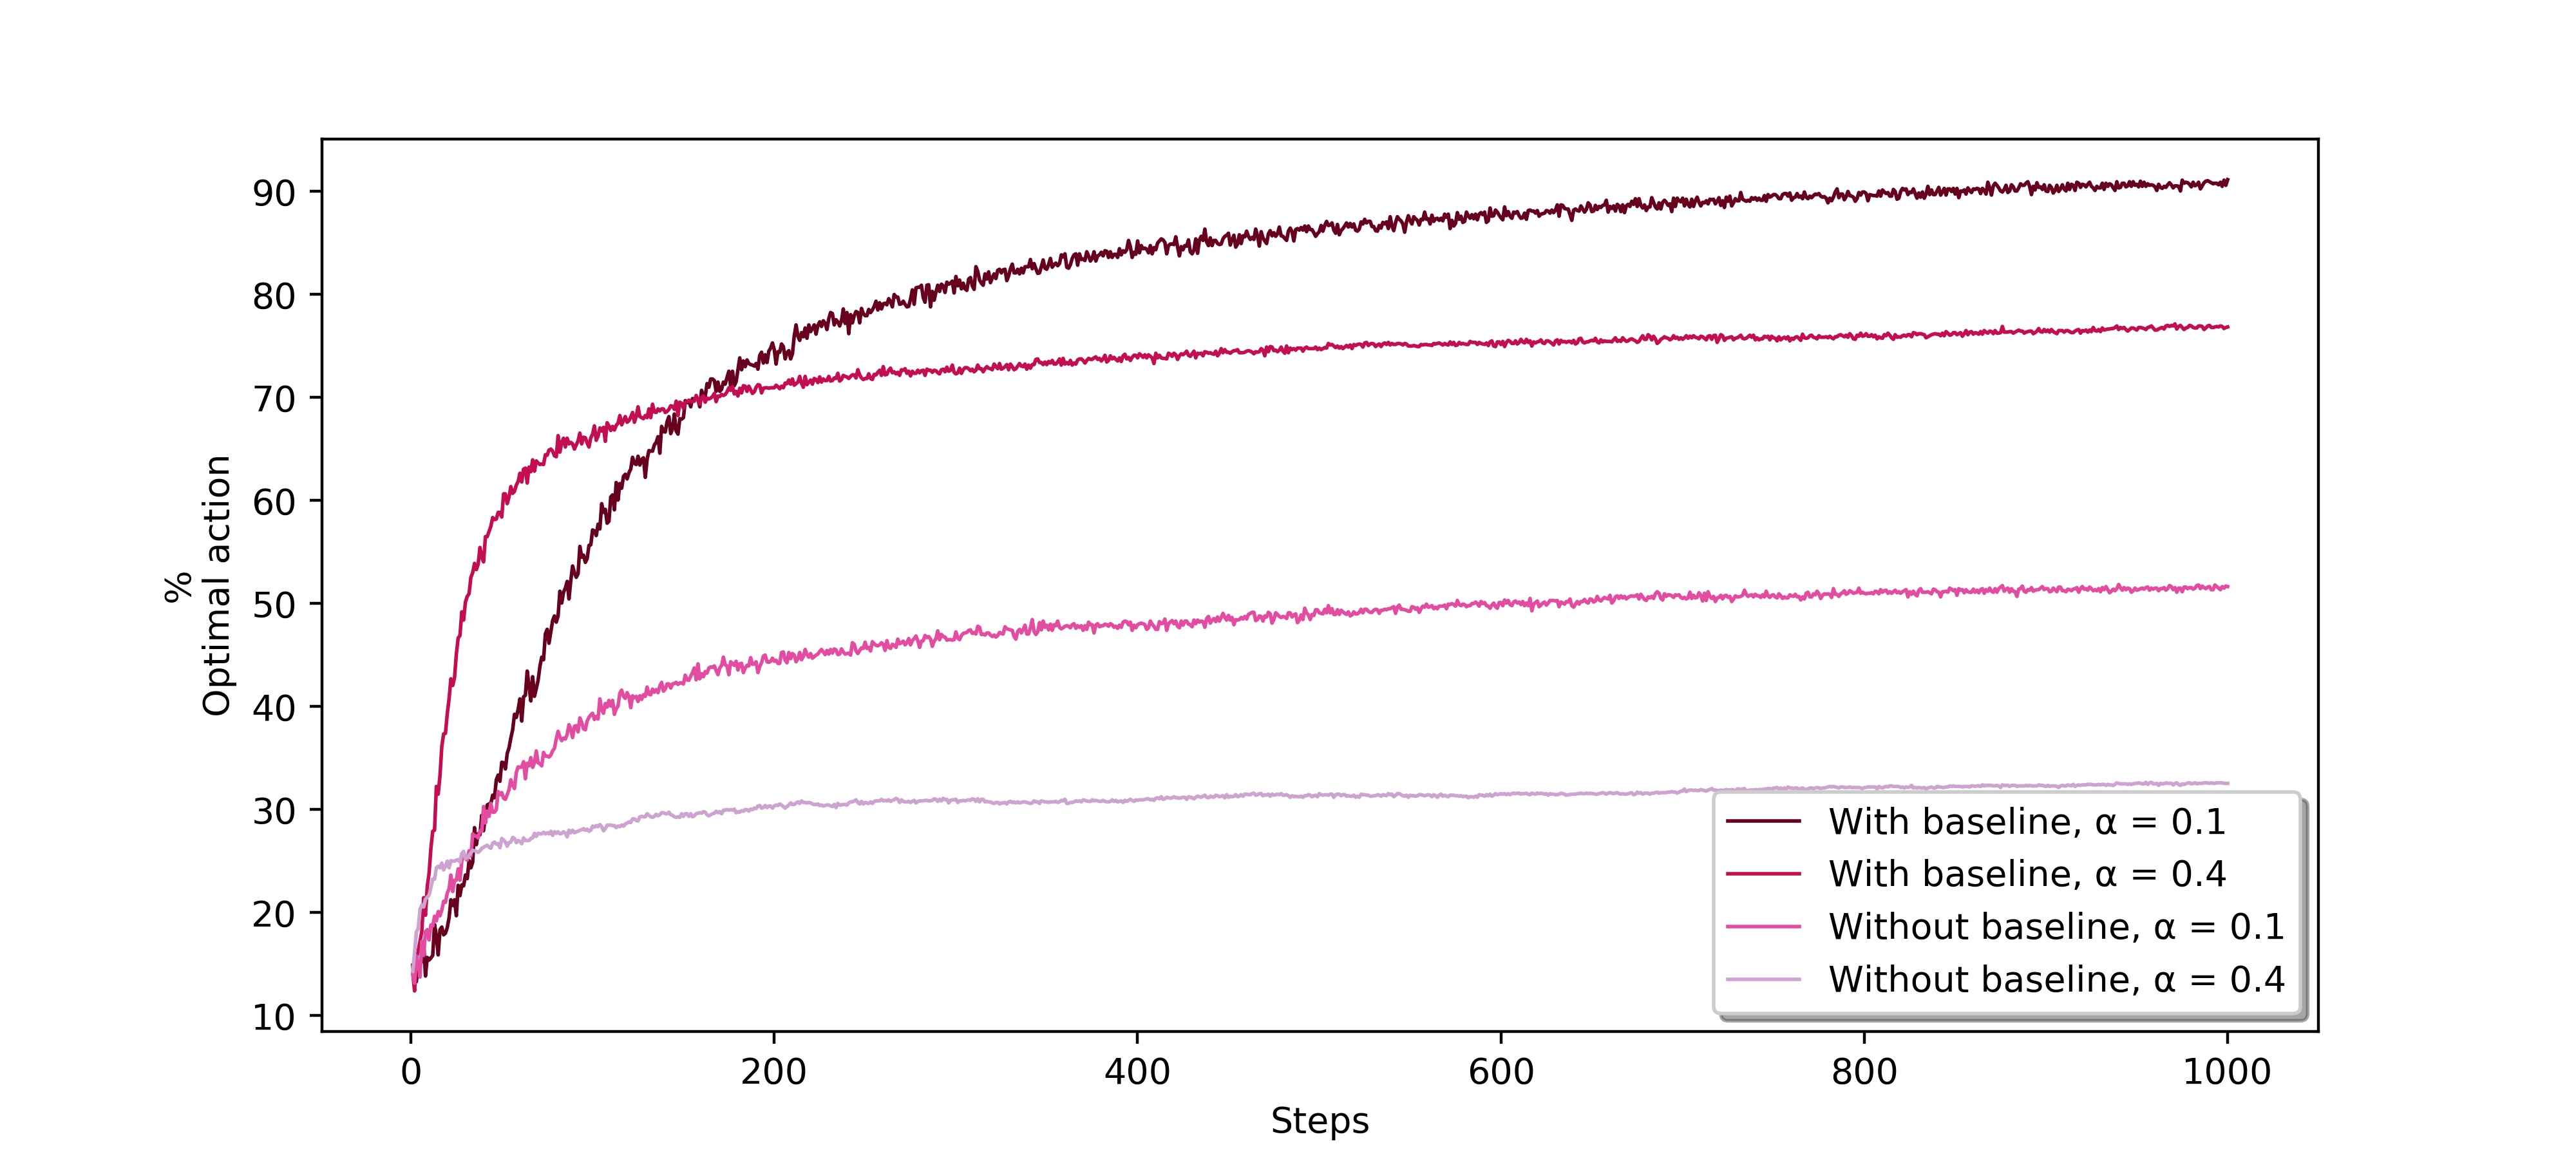
Gradient Bandit Algorithms
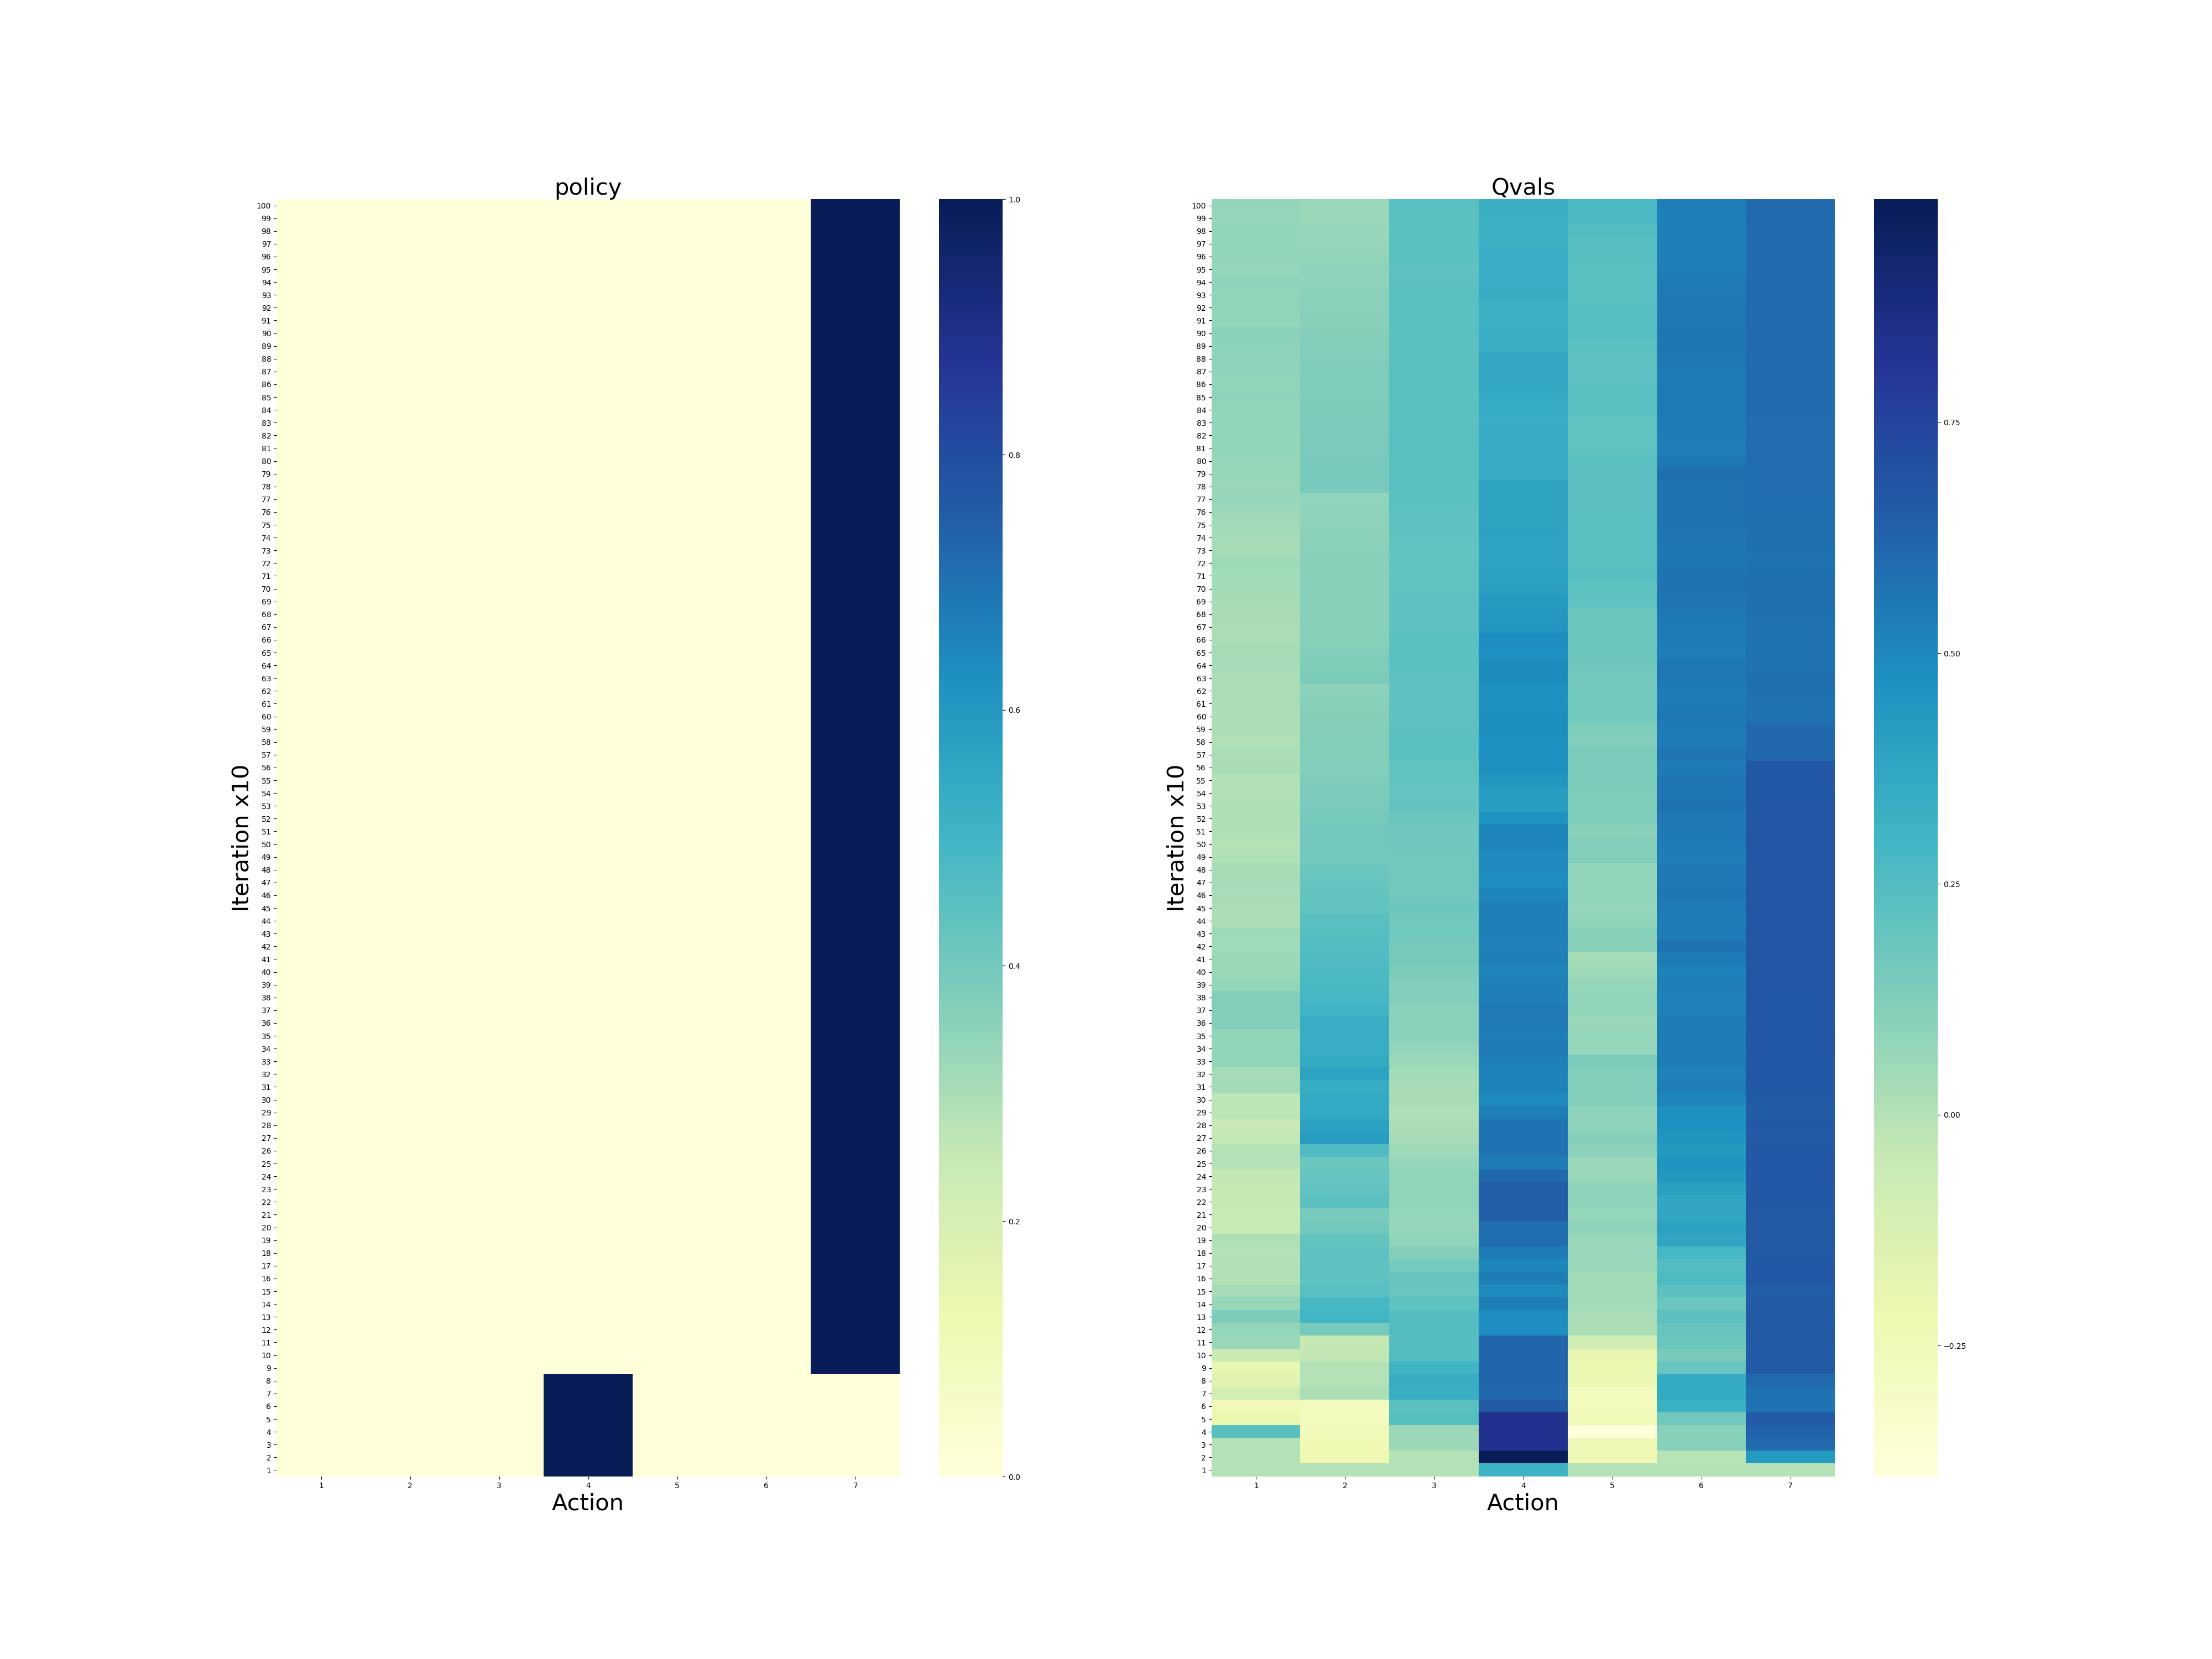
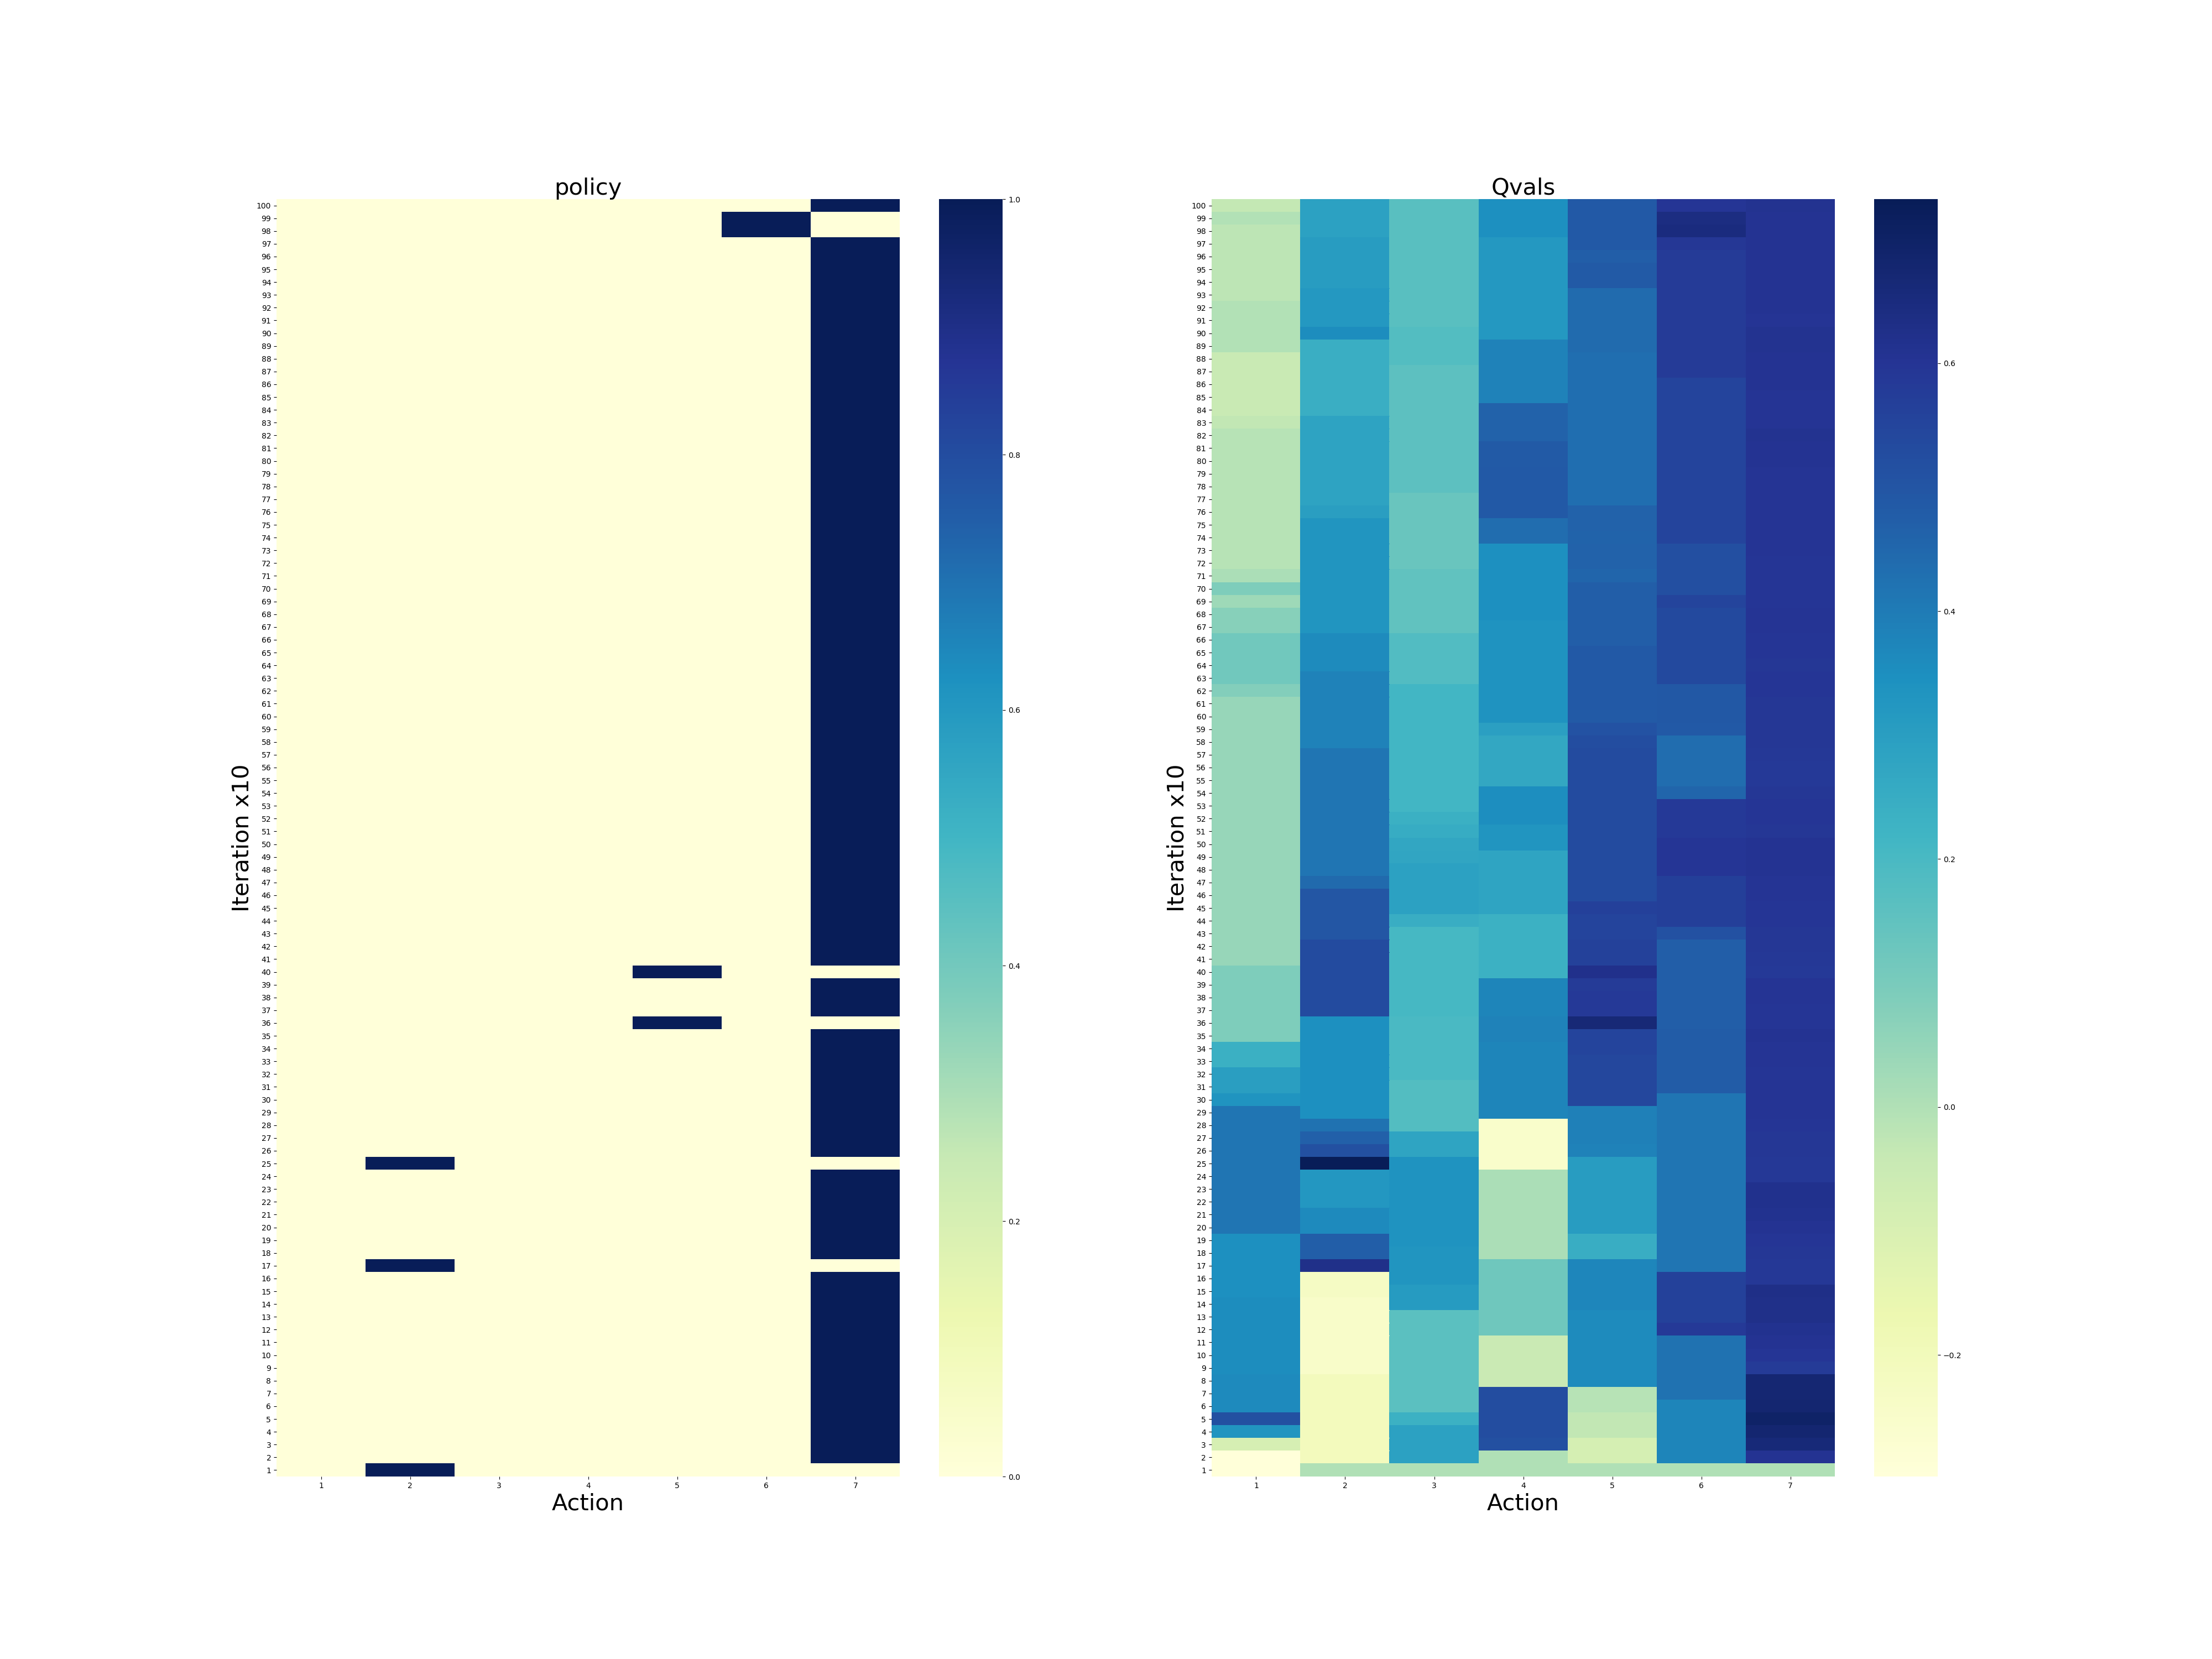
Associative Search (ContextualBandits)
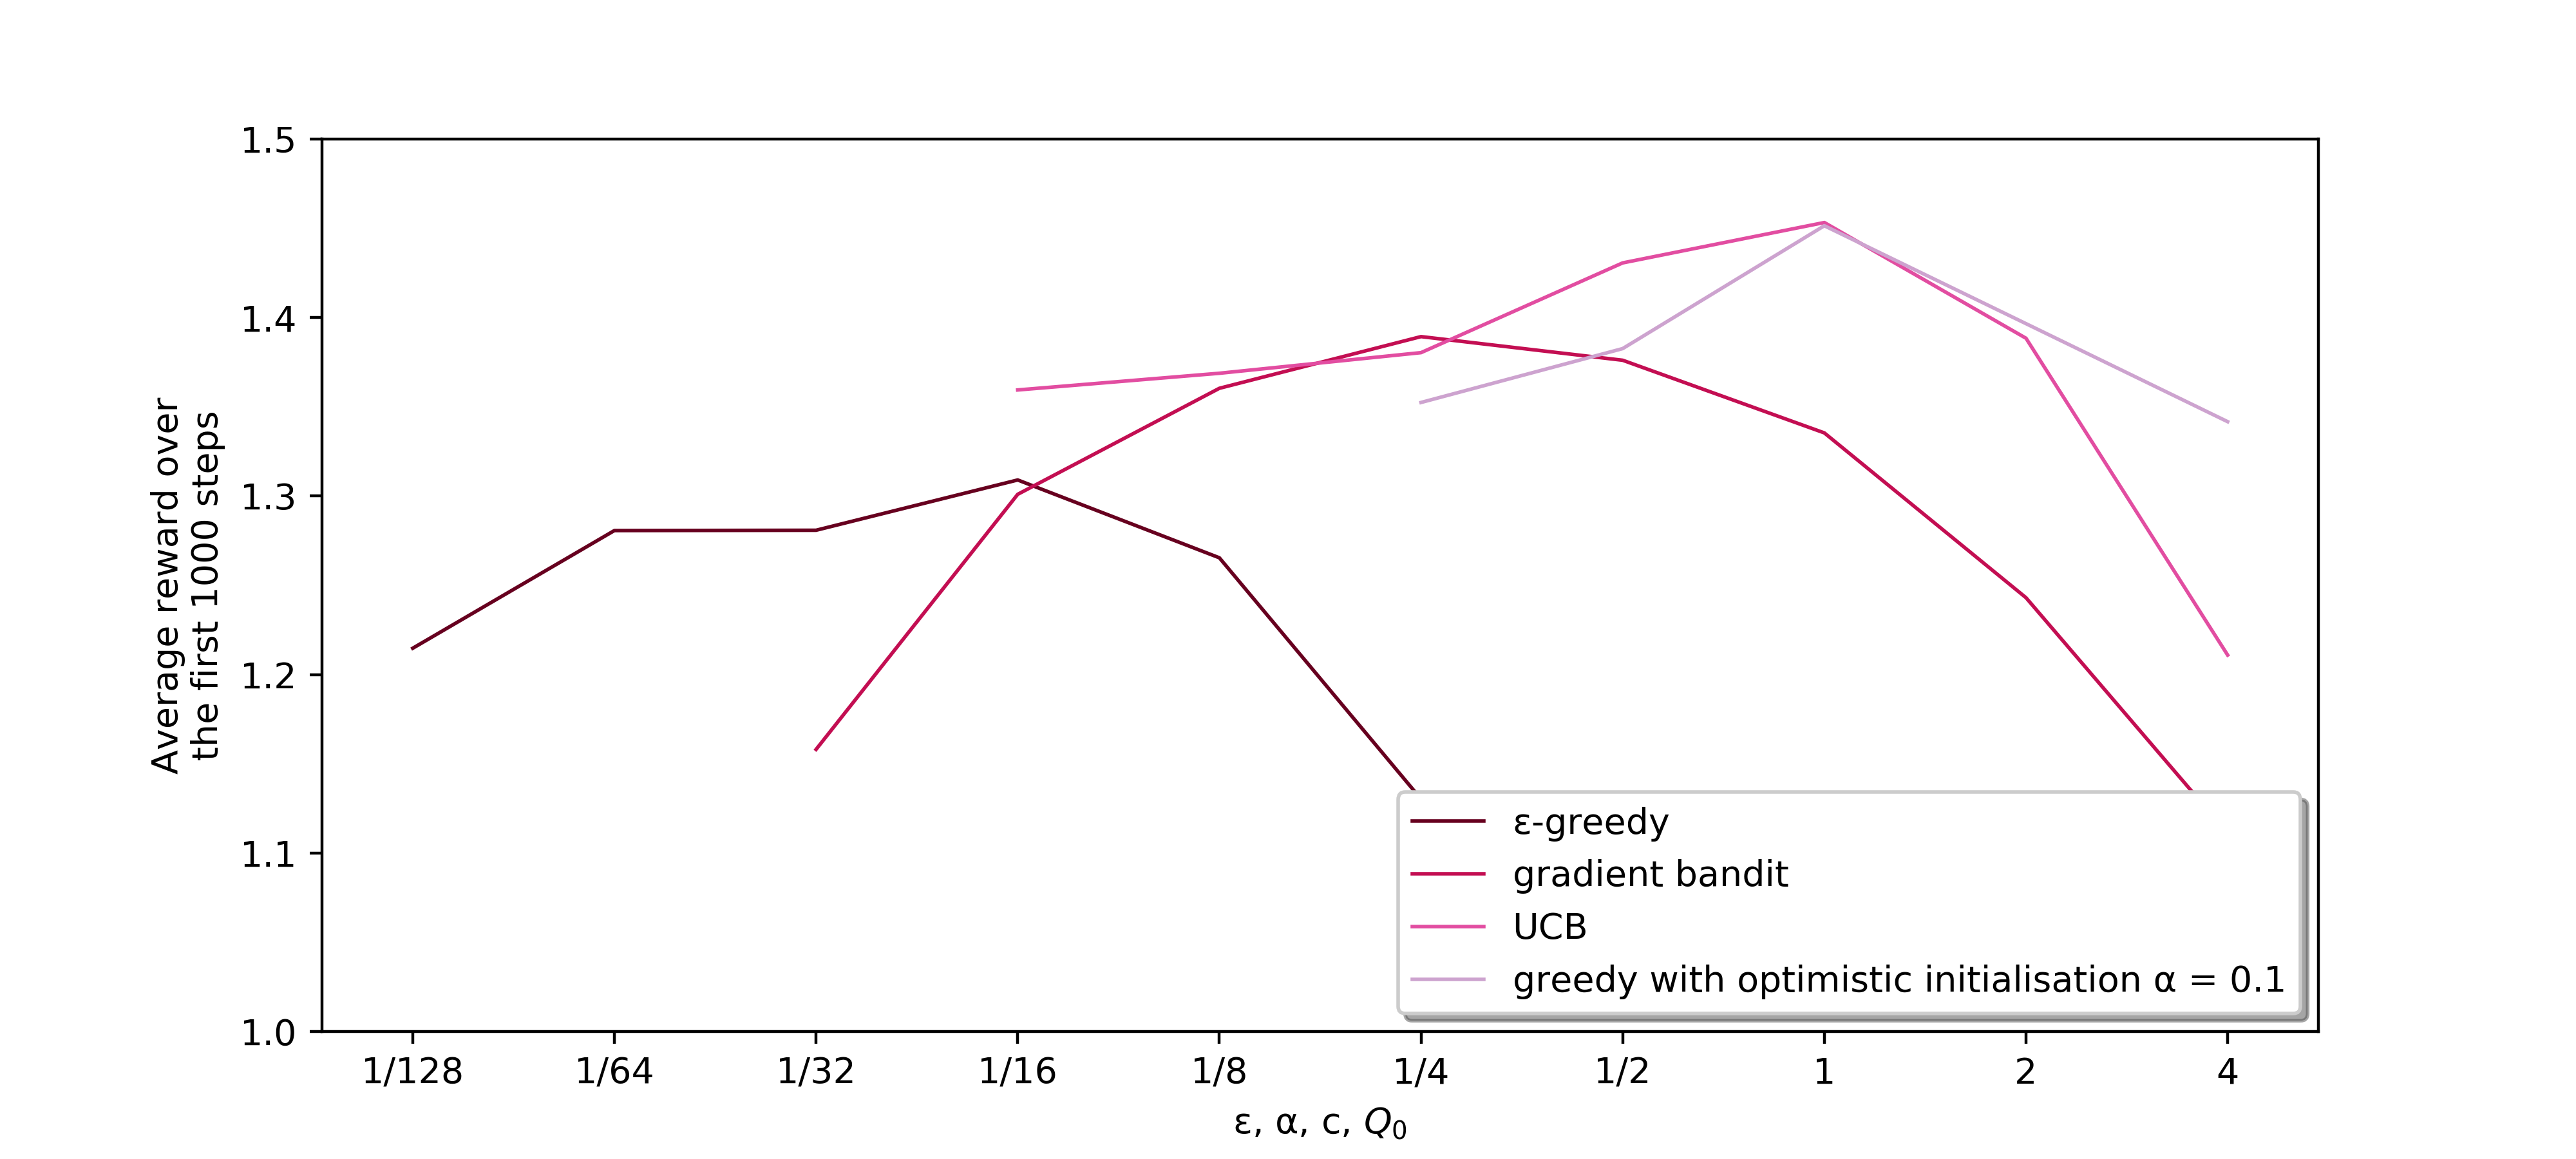
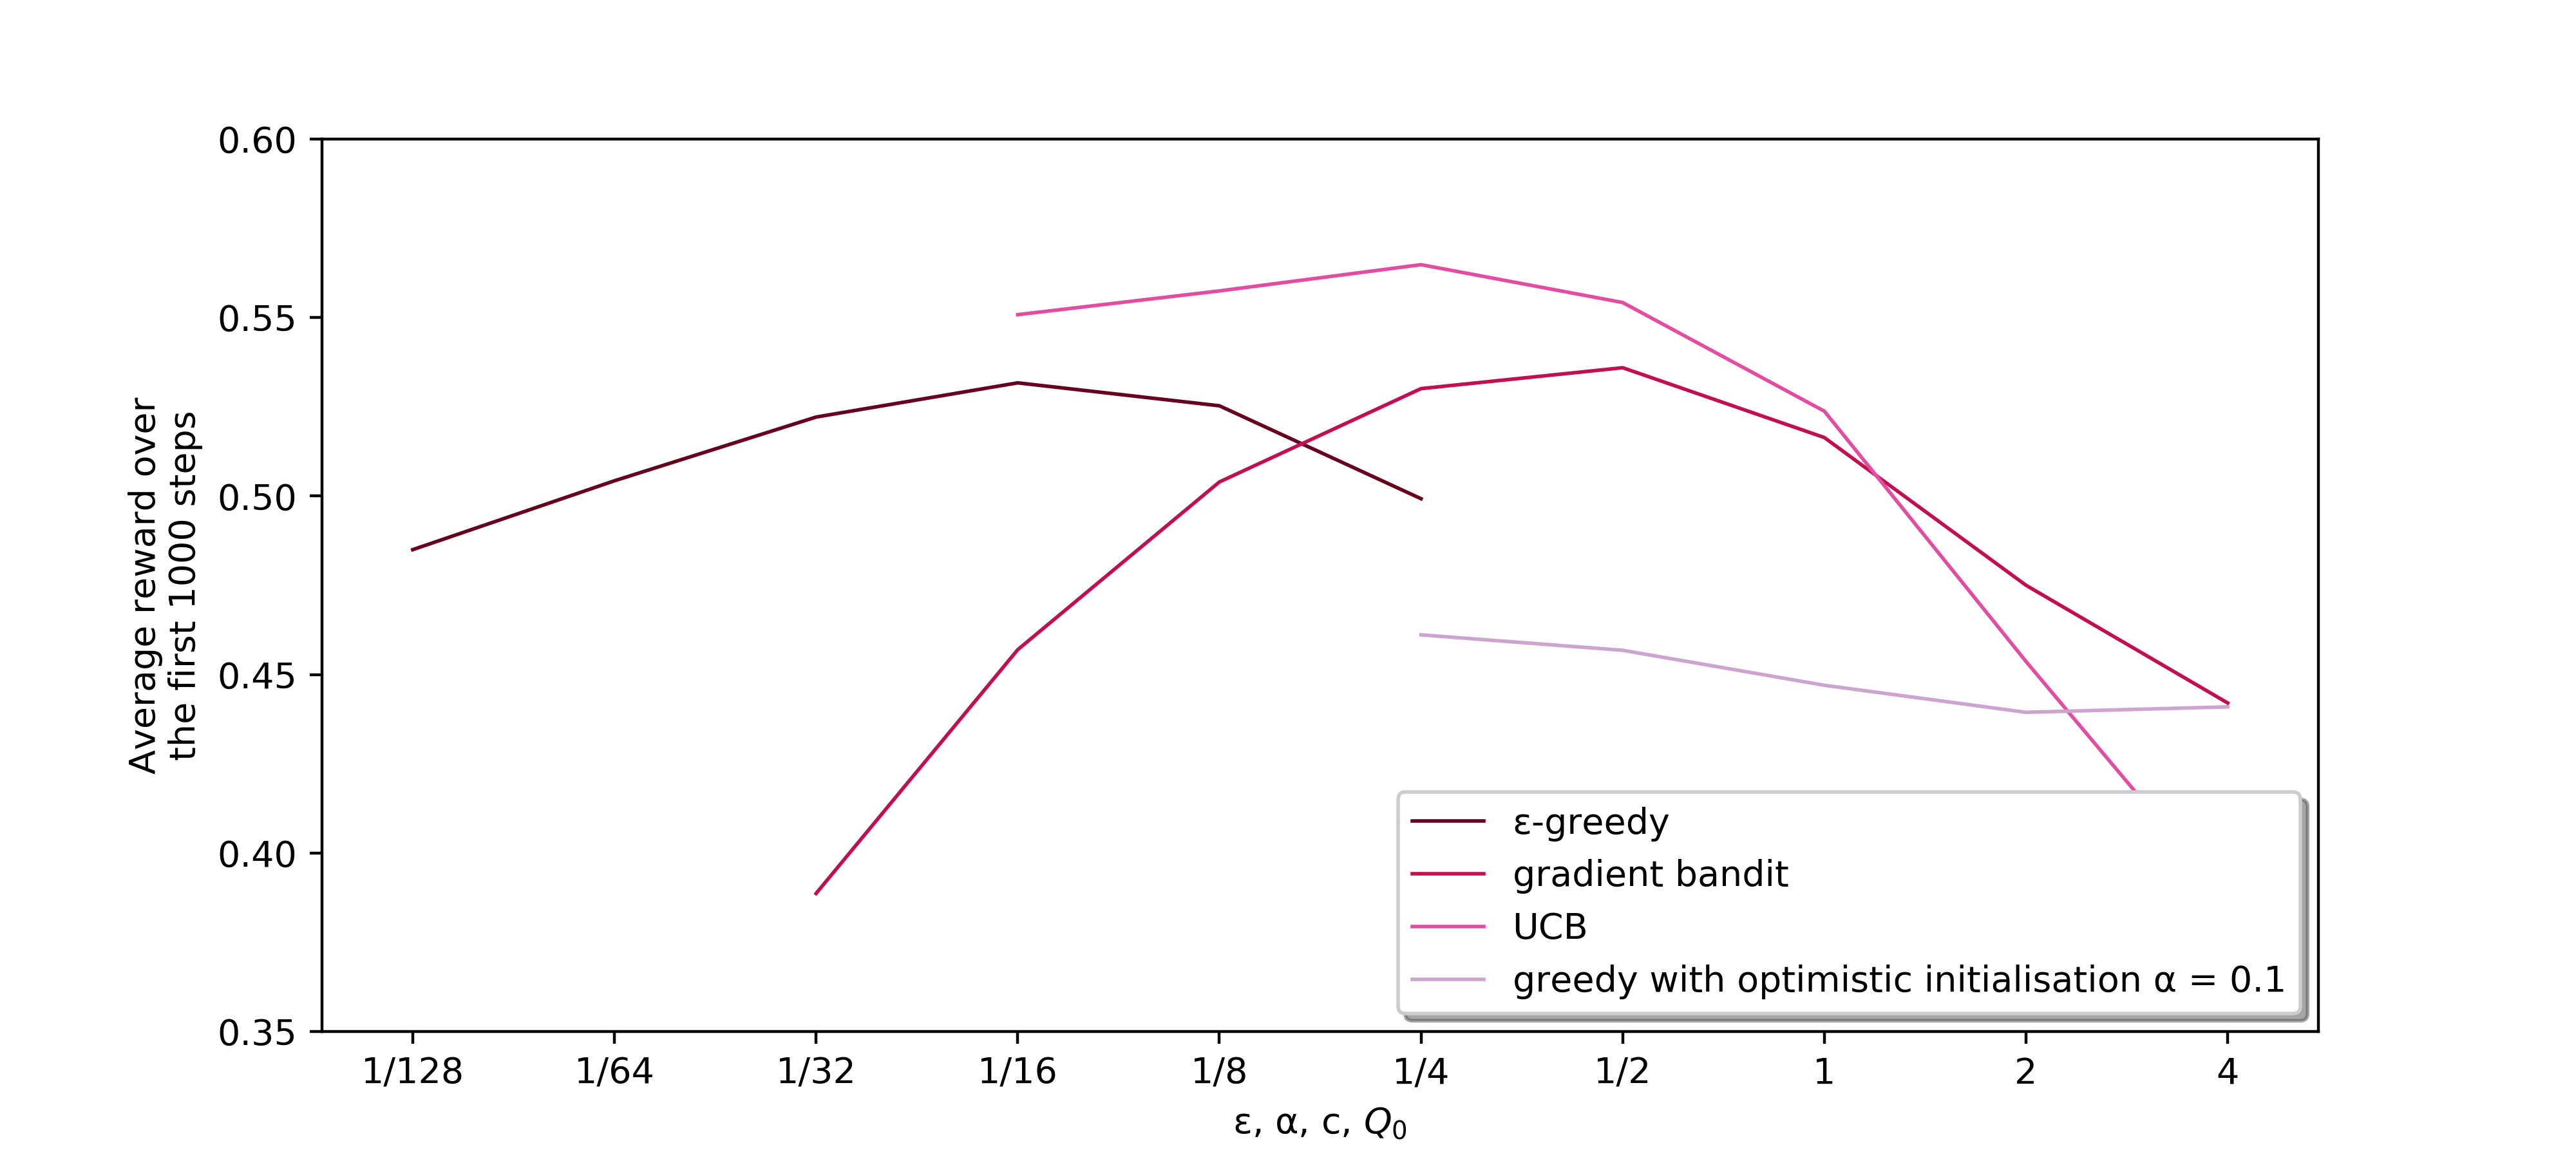
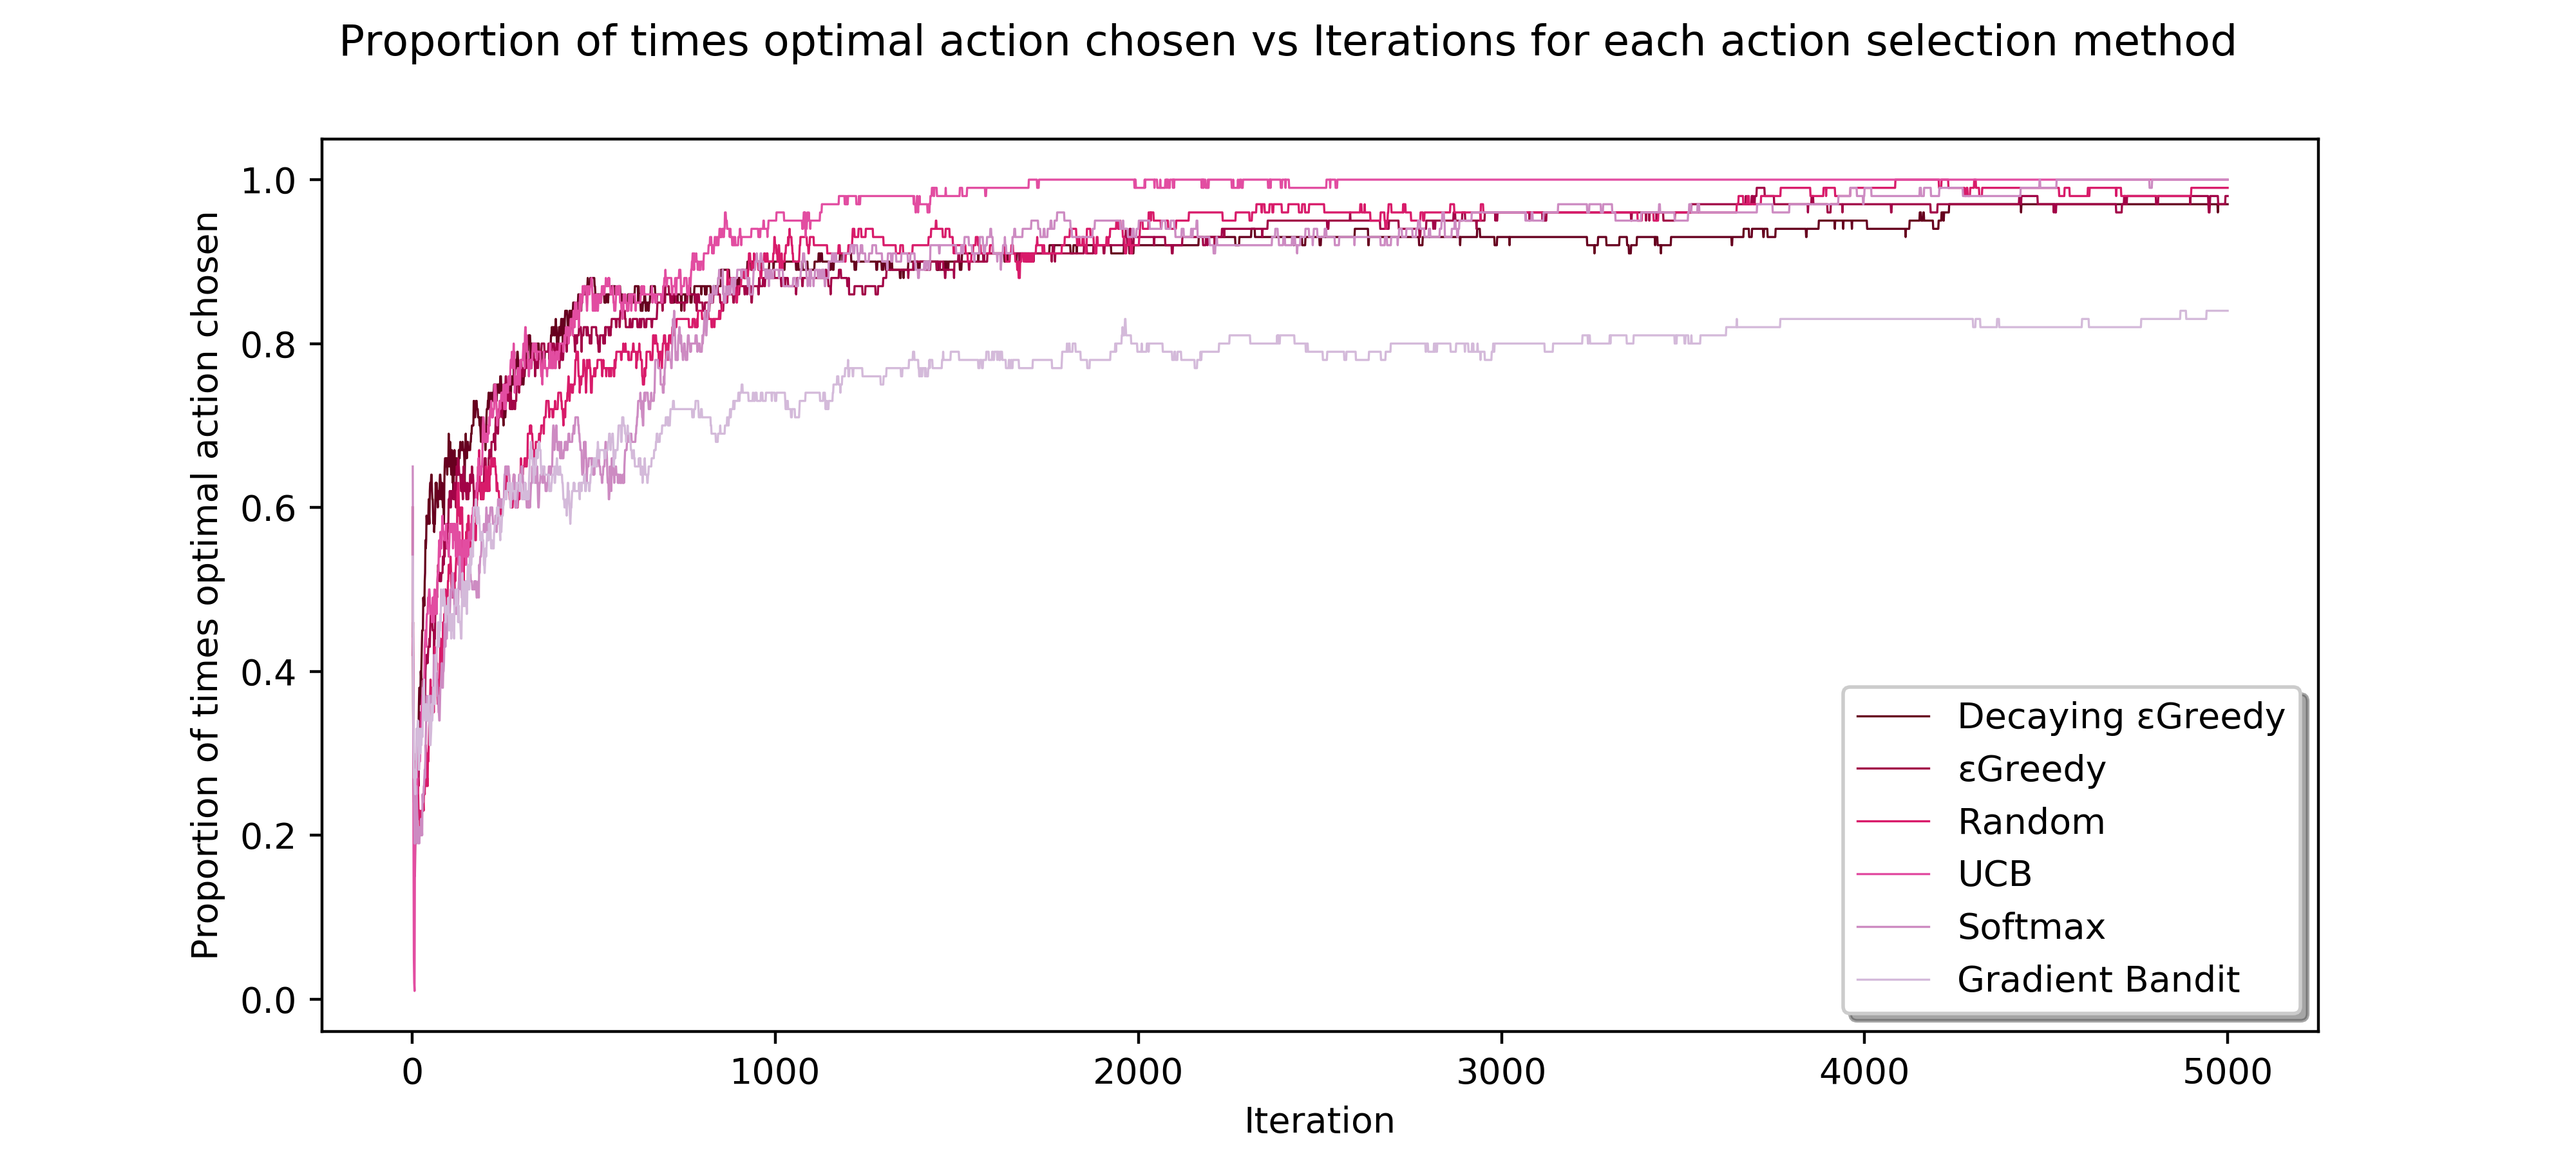
Parameter sweep of bandit algorithms, on the 10-armed testbed and my pdfs on the left.
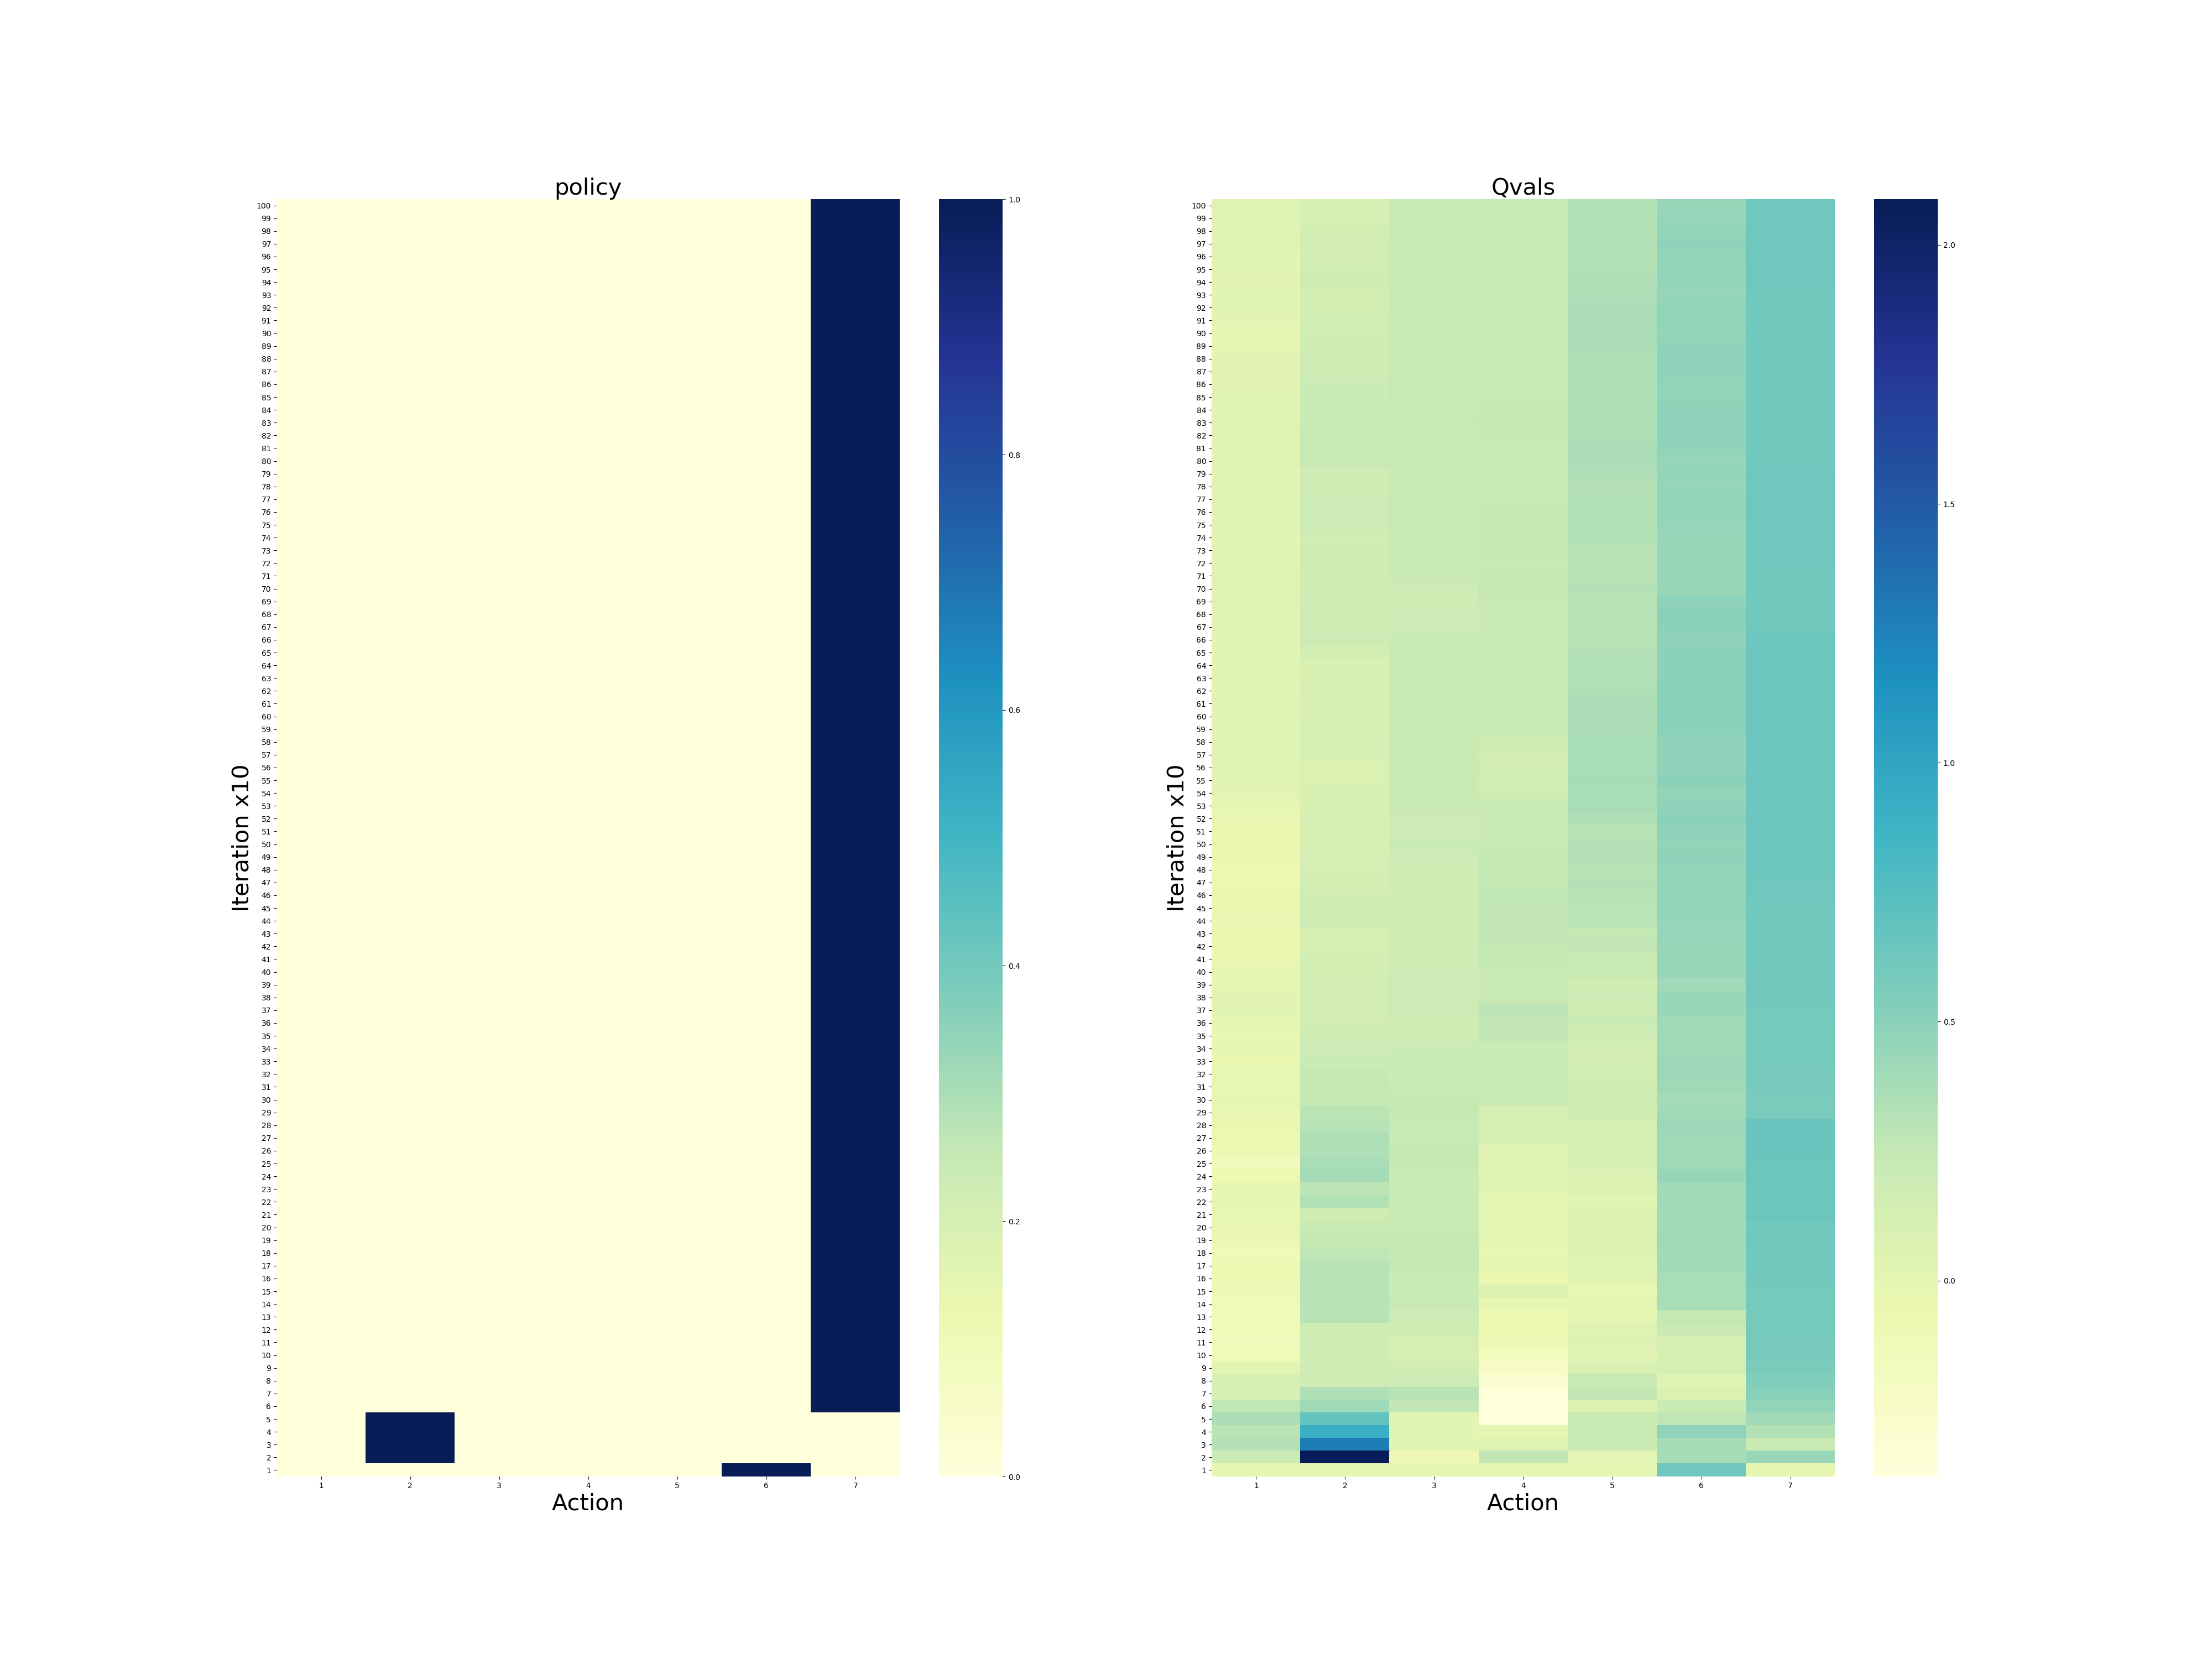
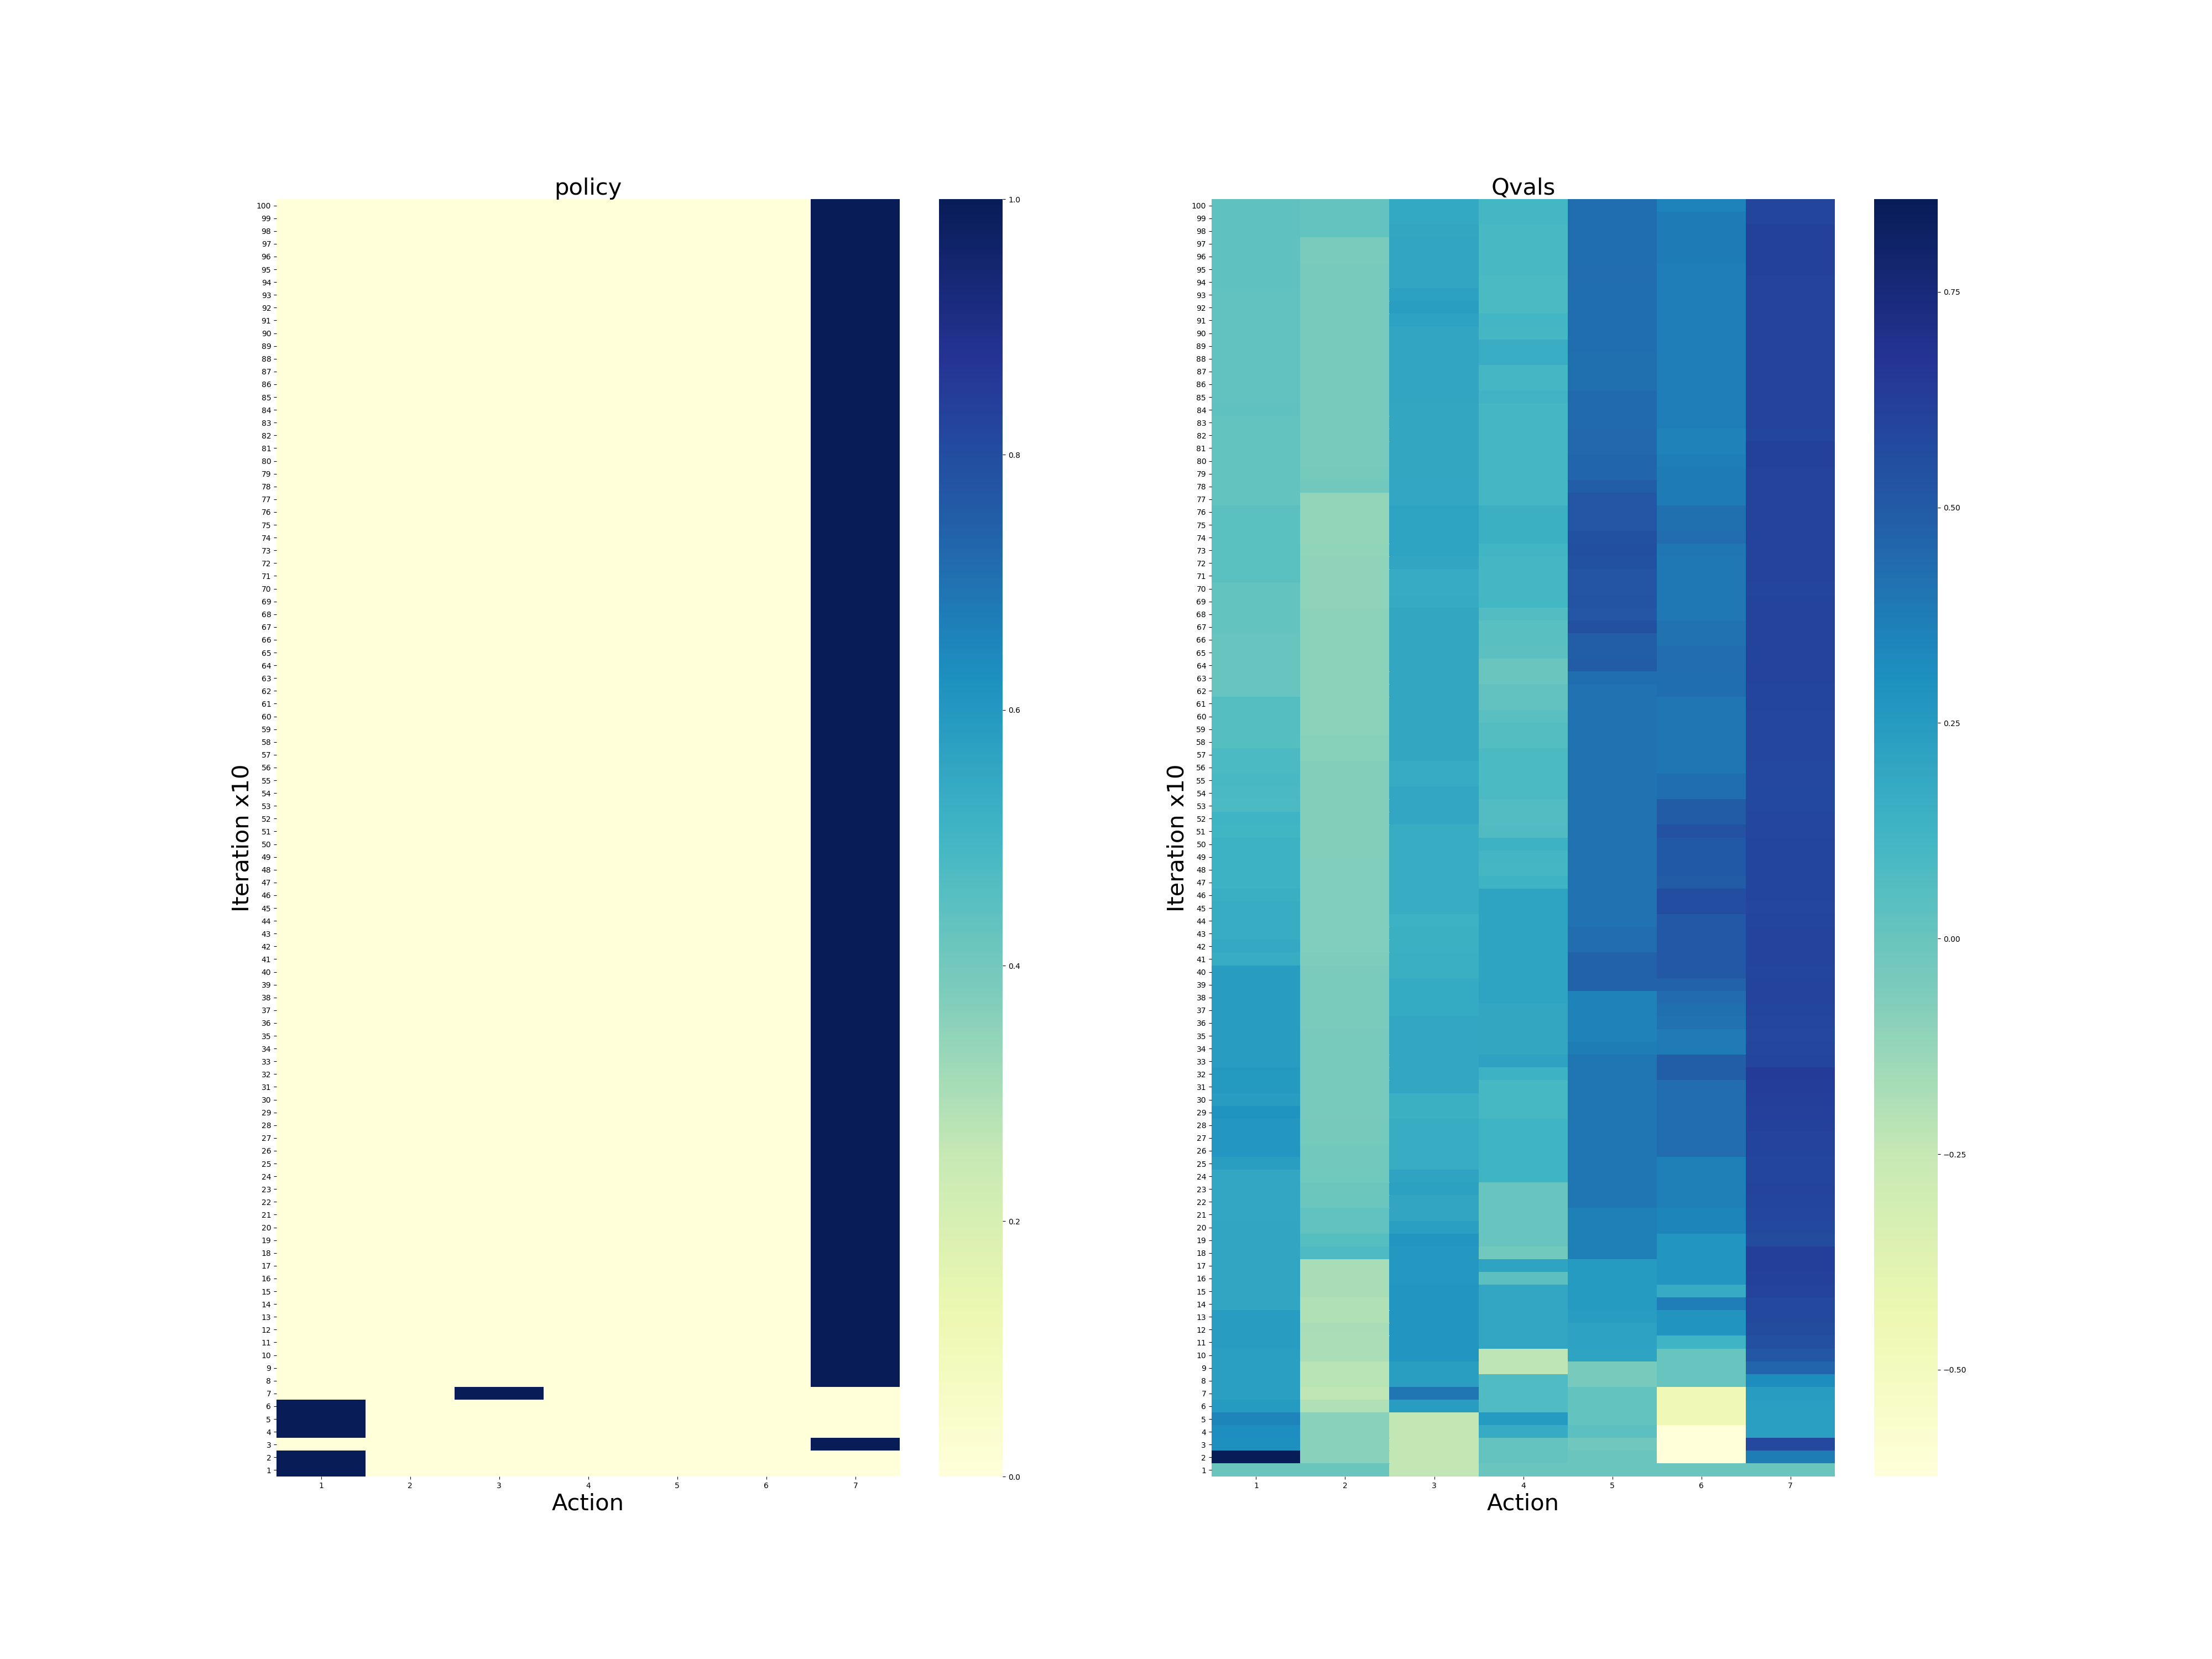
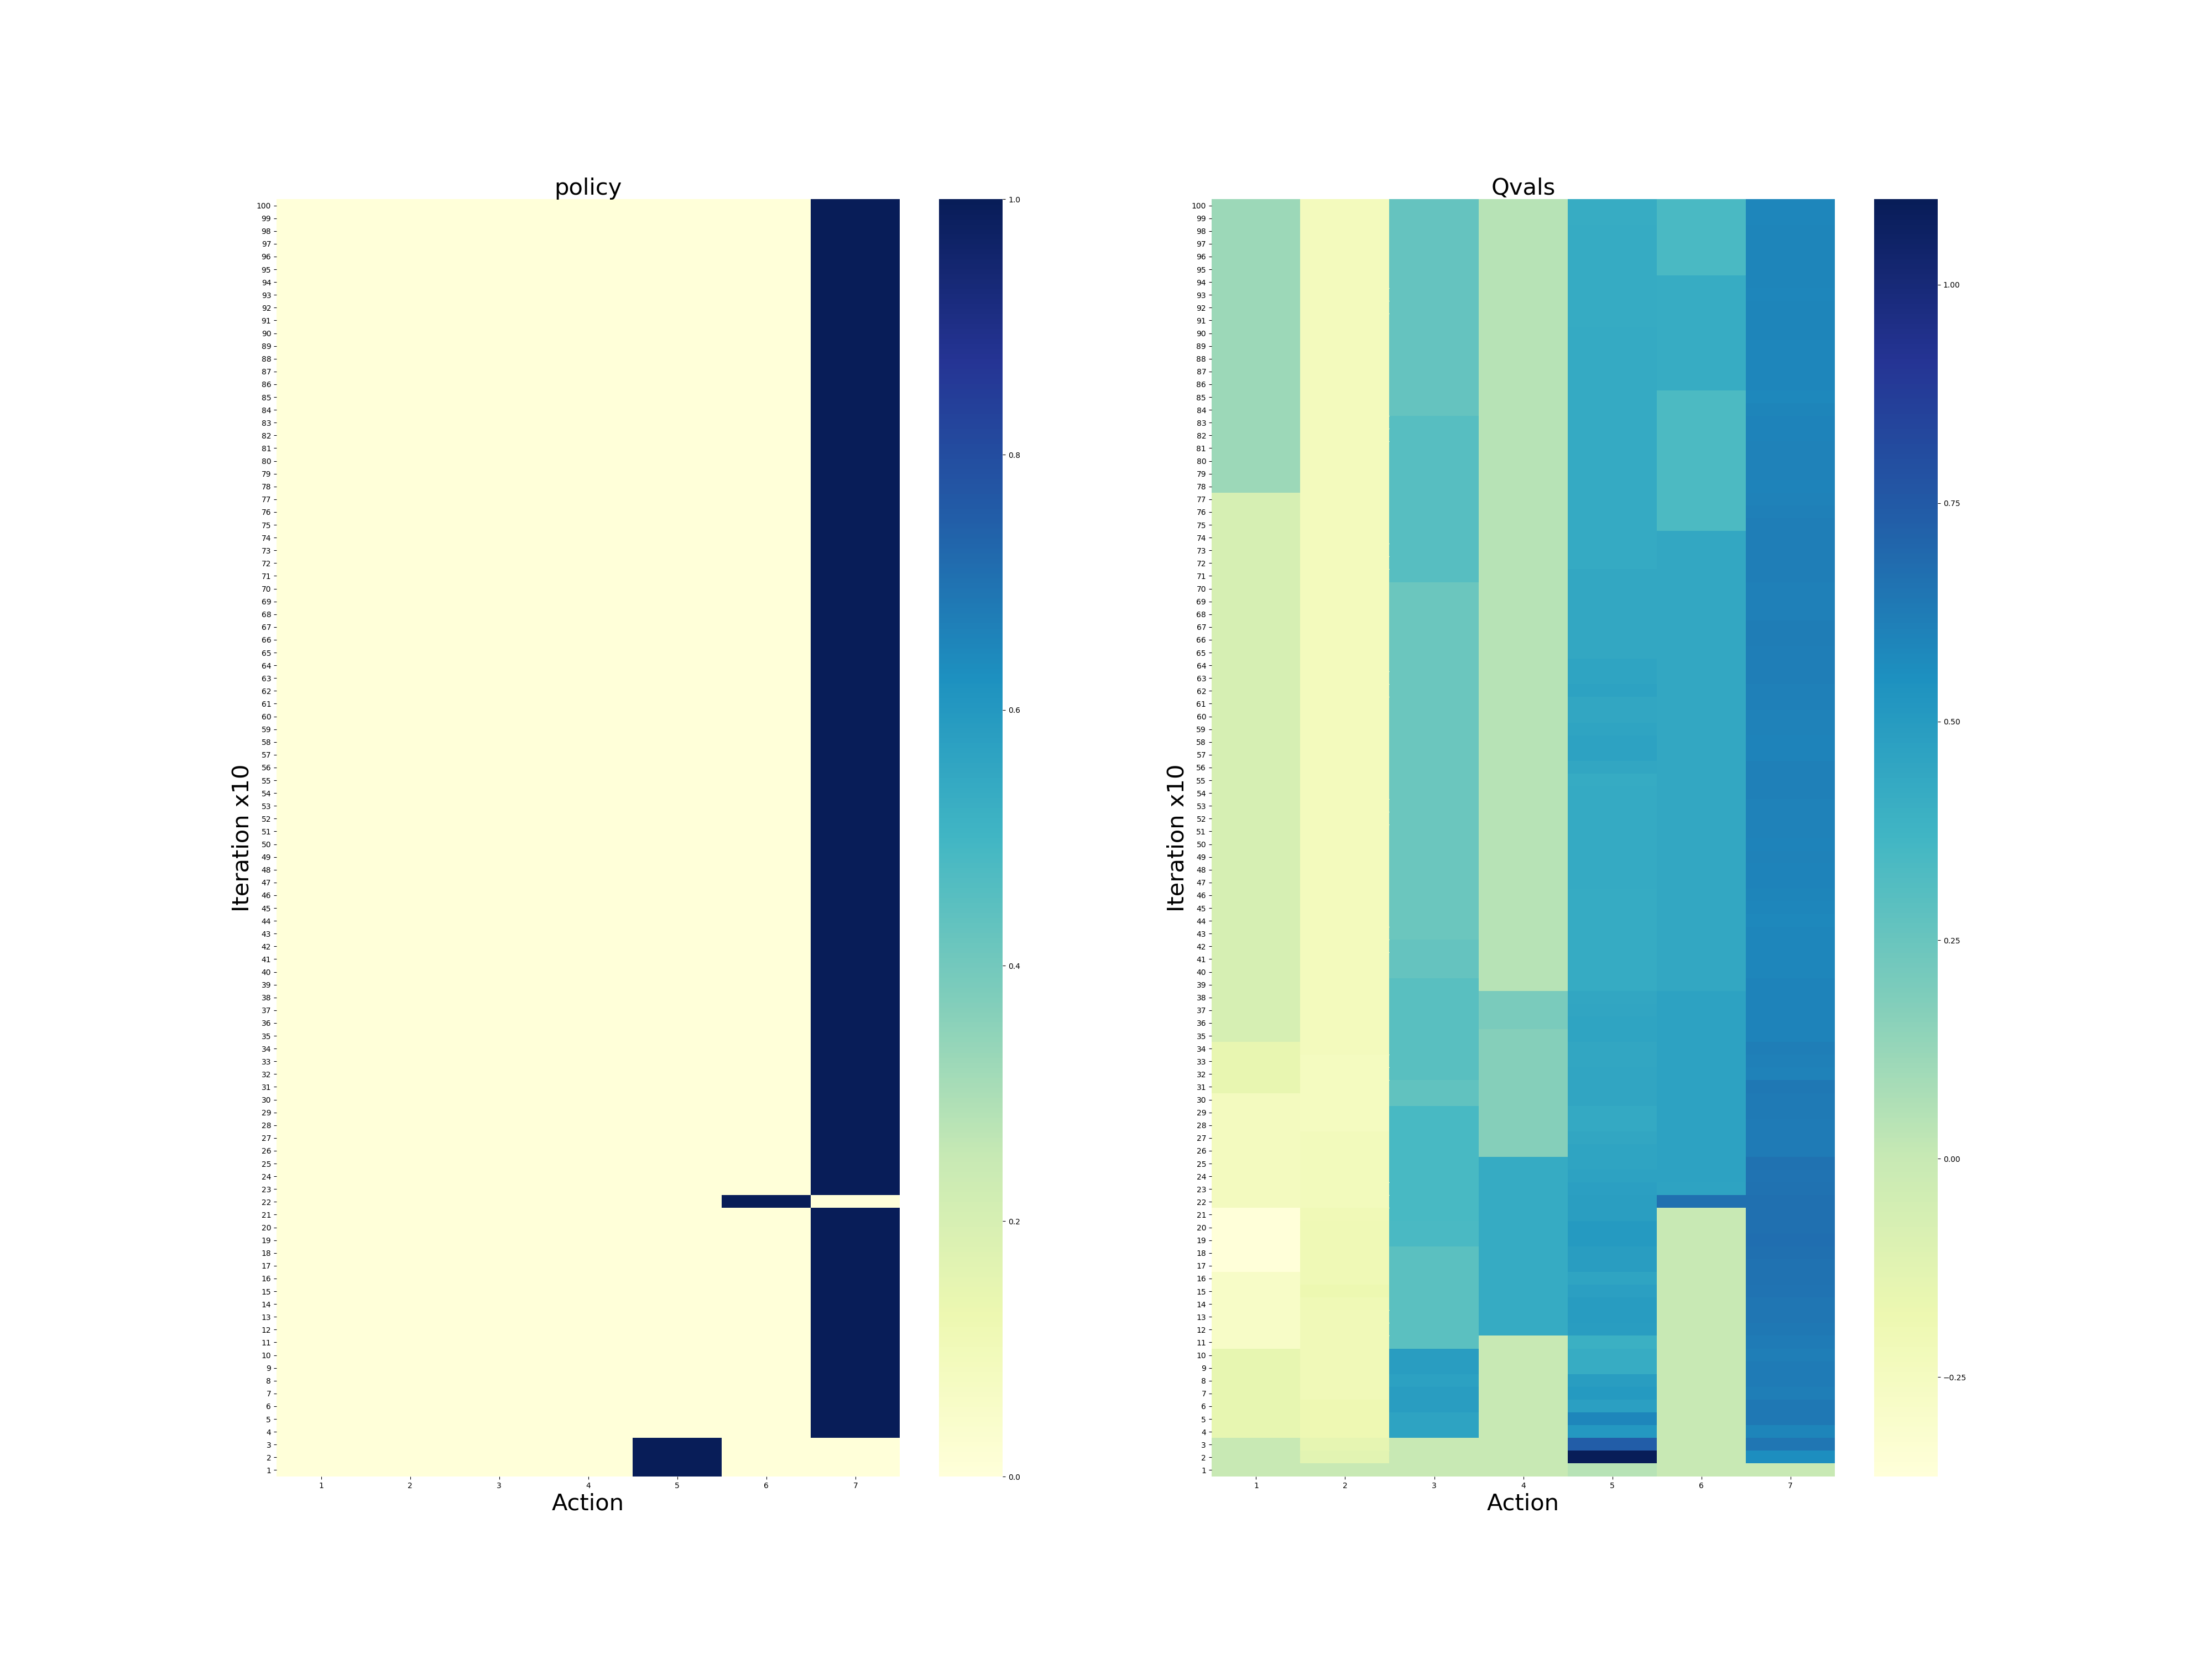
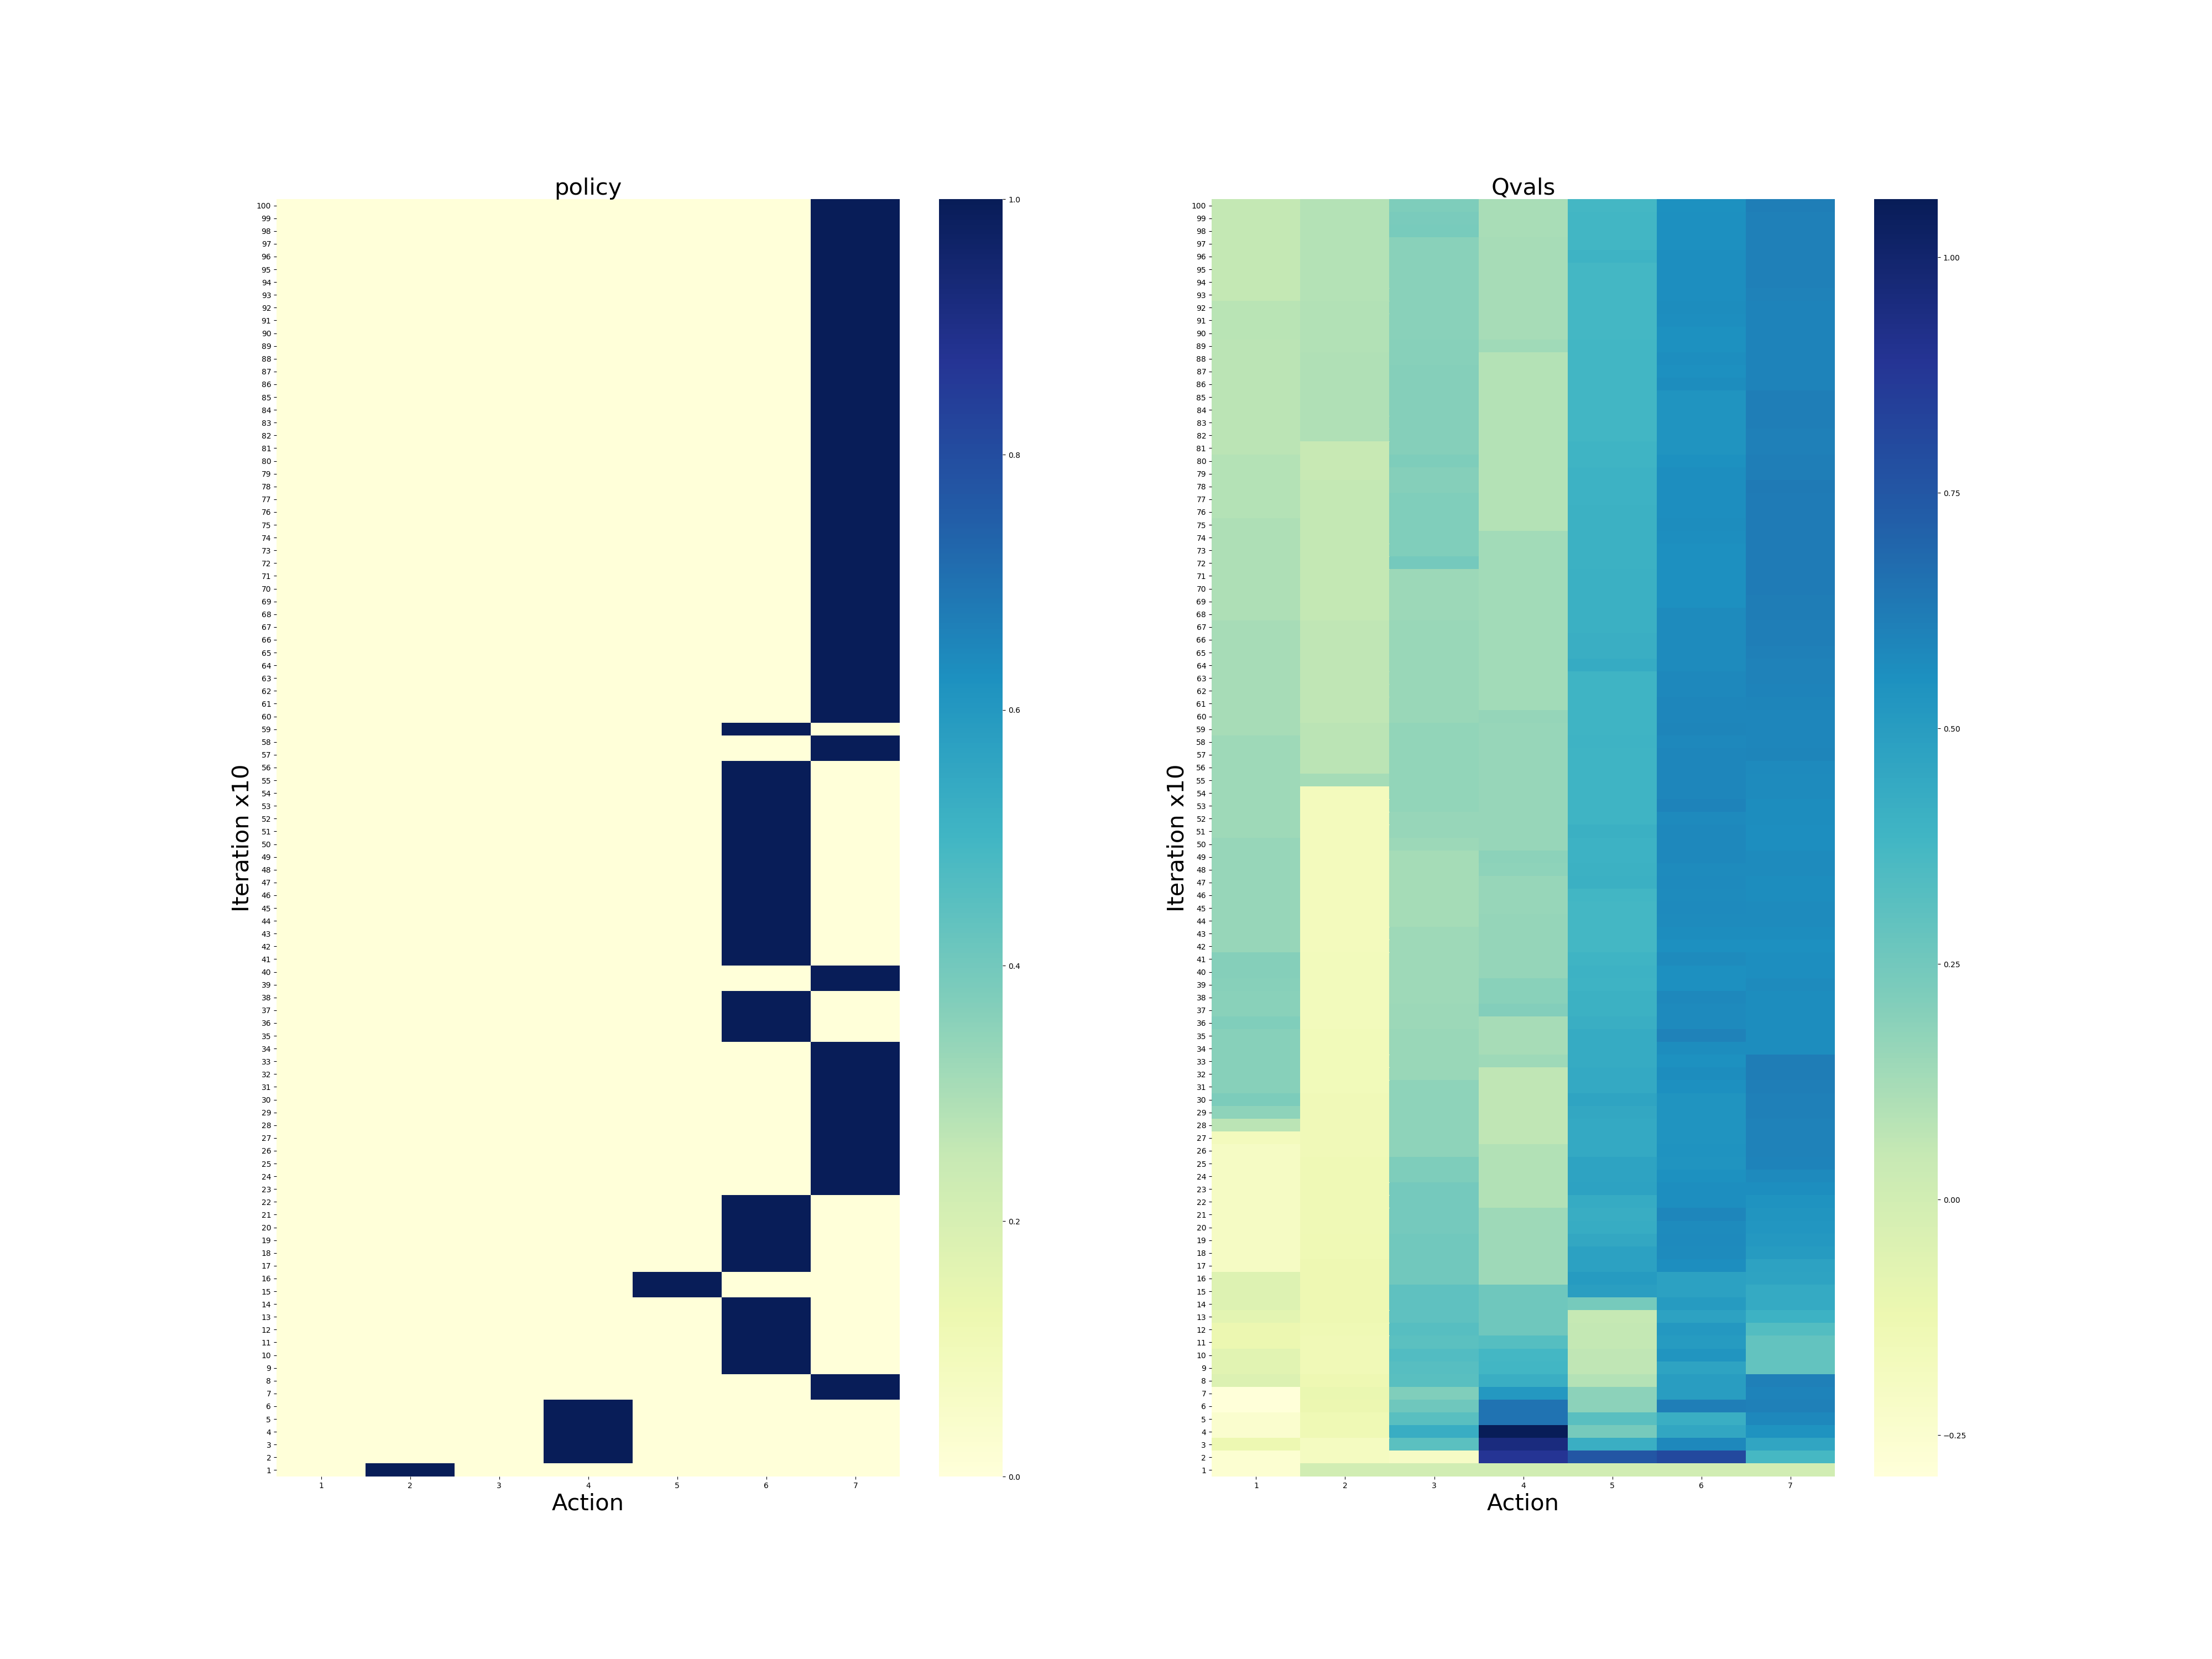
The Agent–Environment Interface
Goals and Rewards
Returns and Episodes
Unified Notation for Episodic and Continuing Tasks
Policies and Value Functions
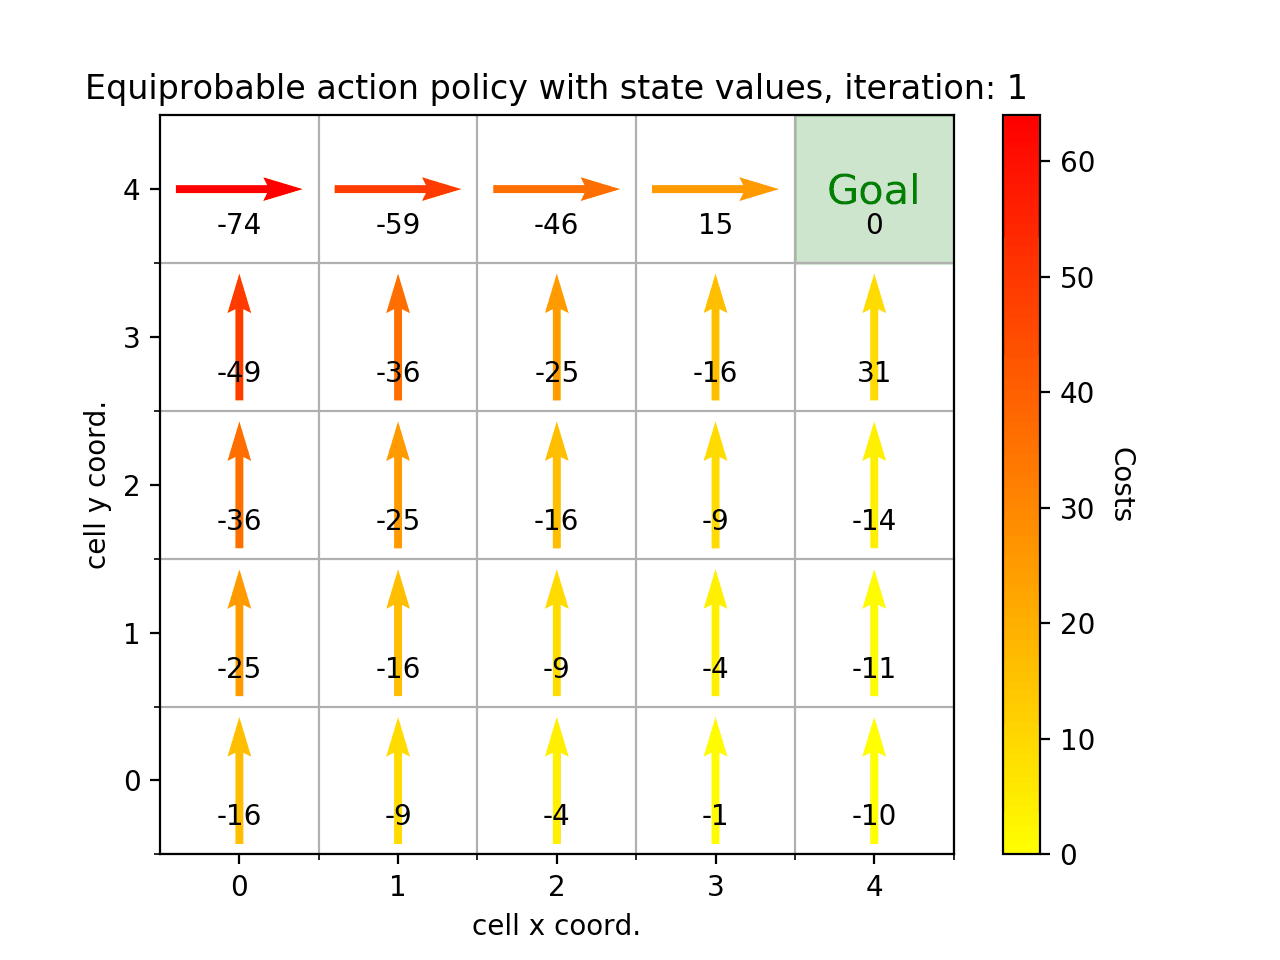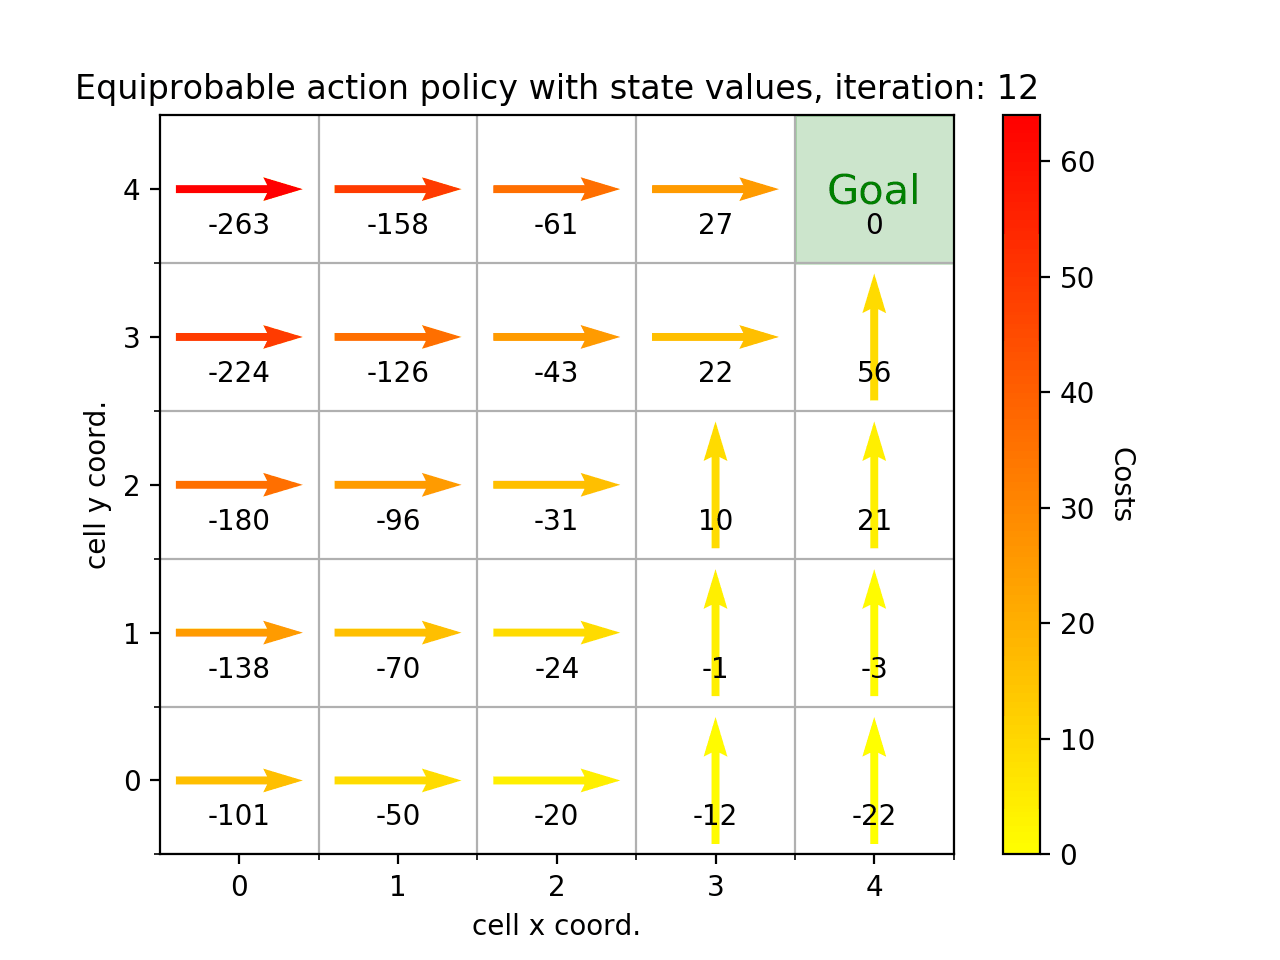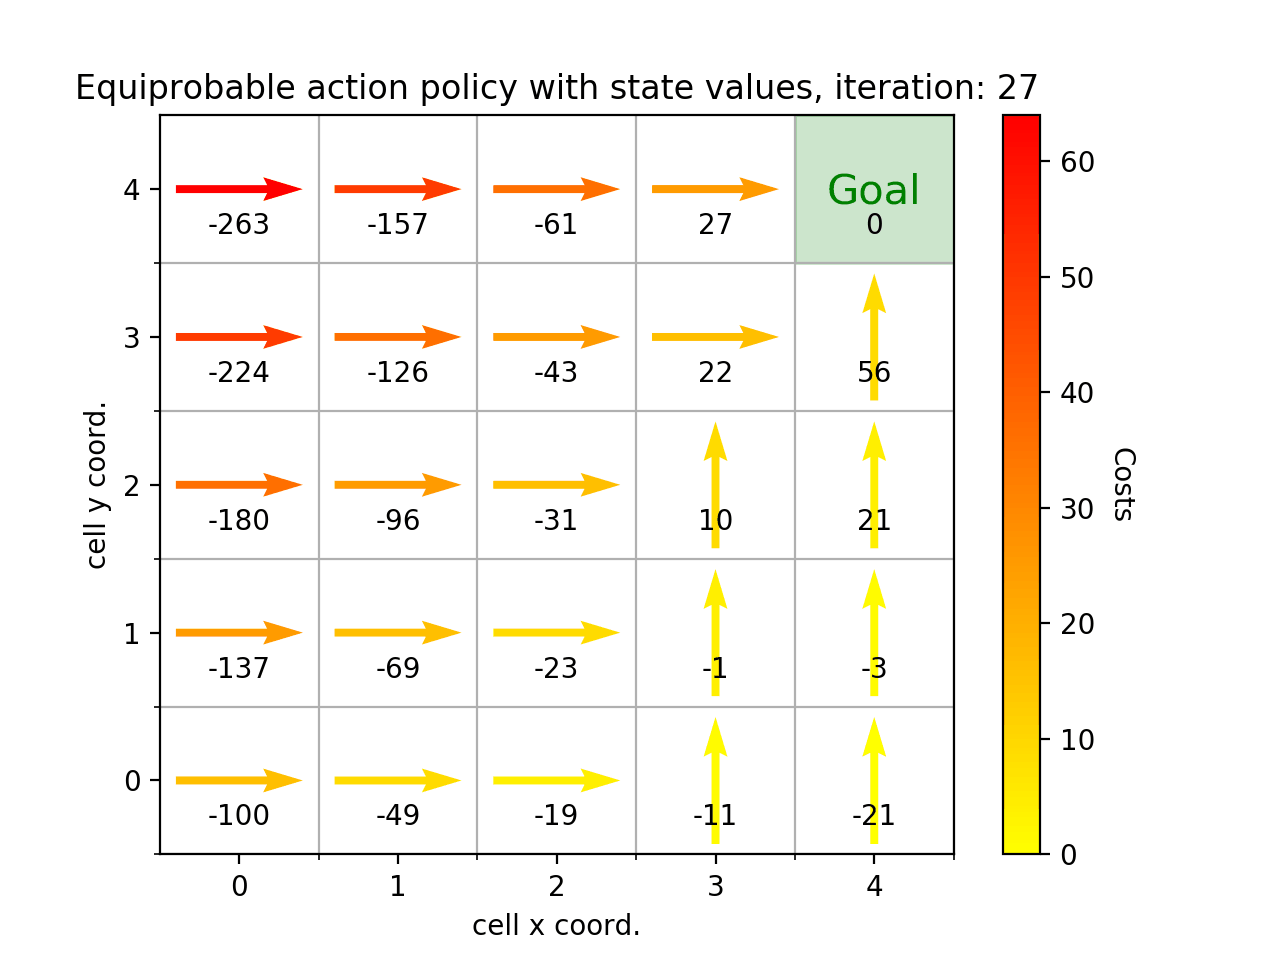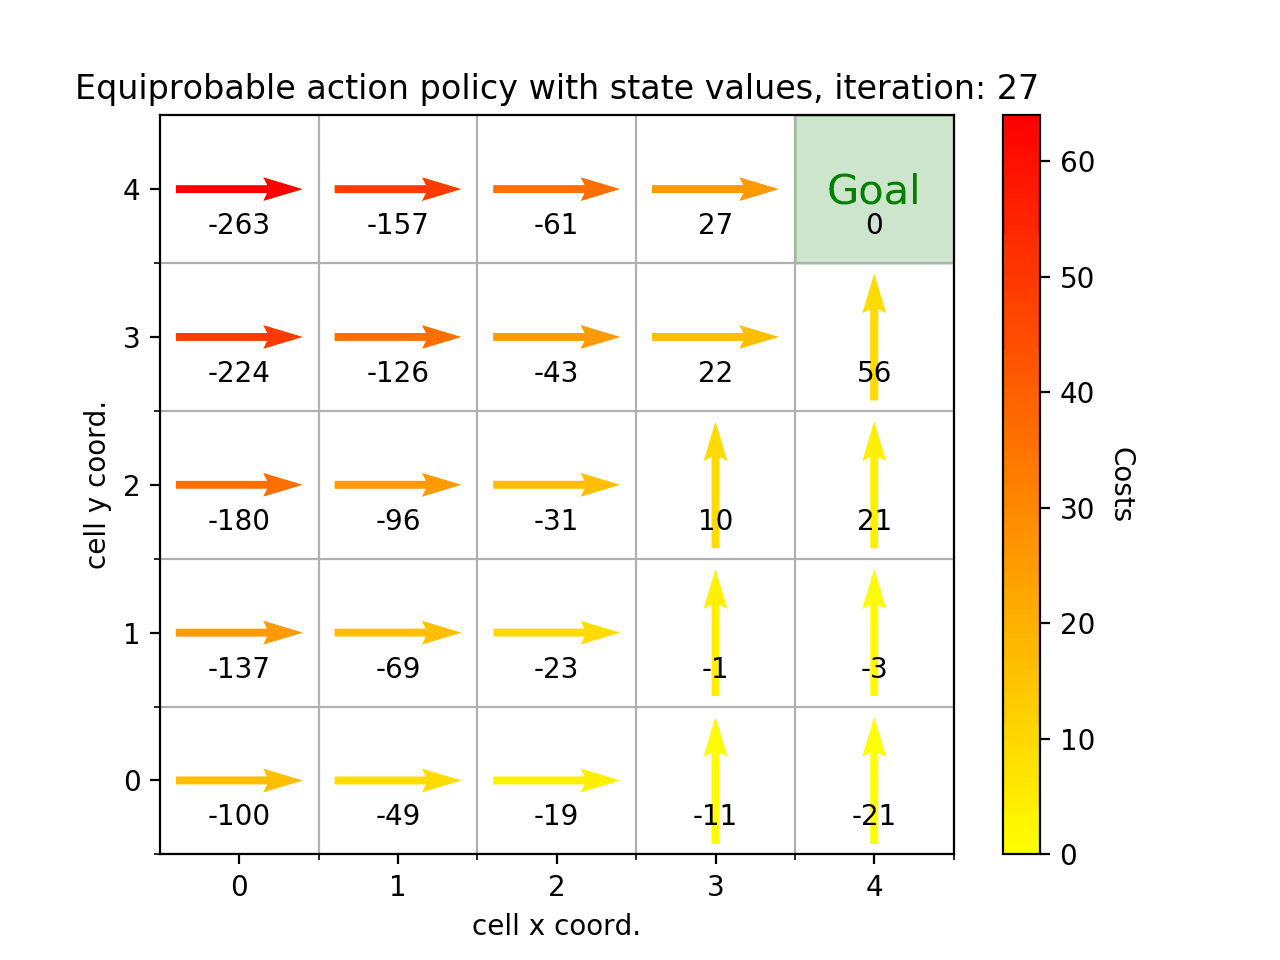
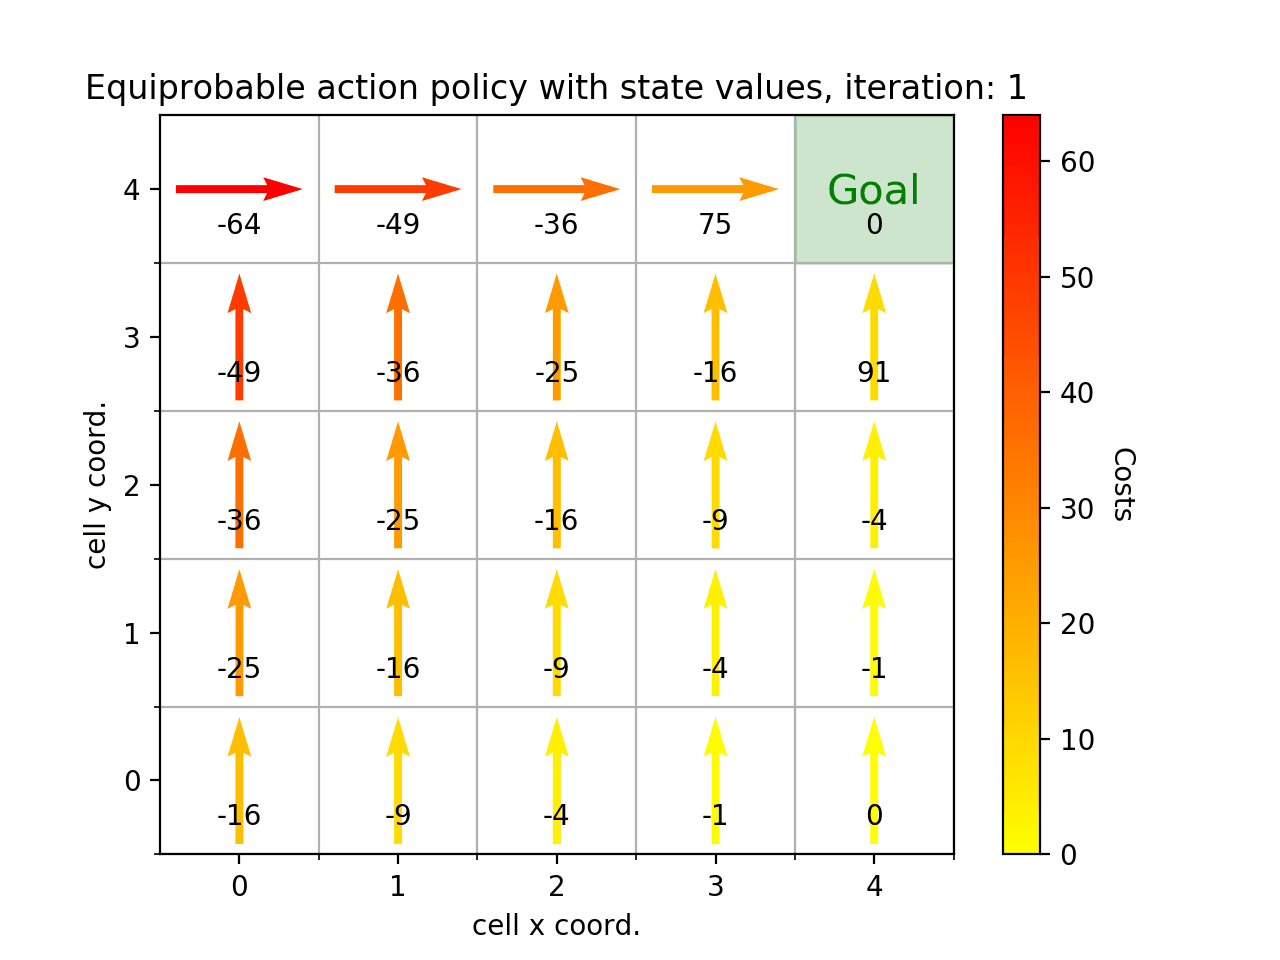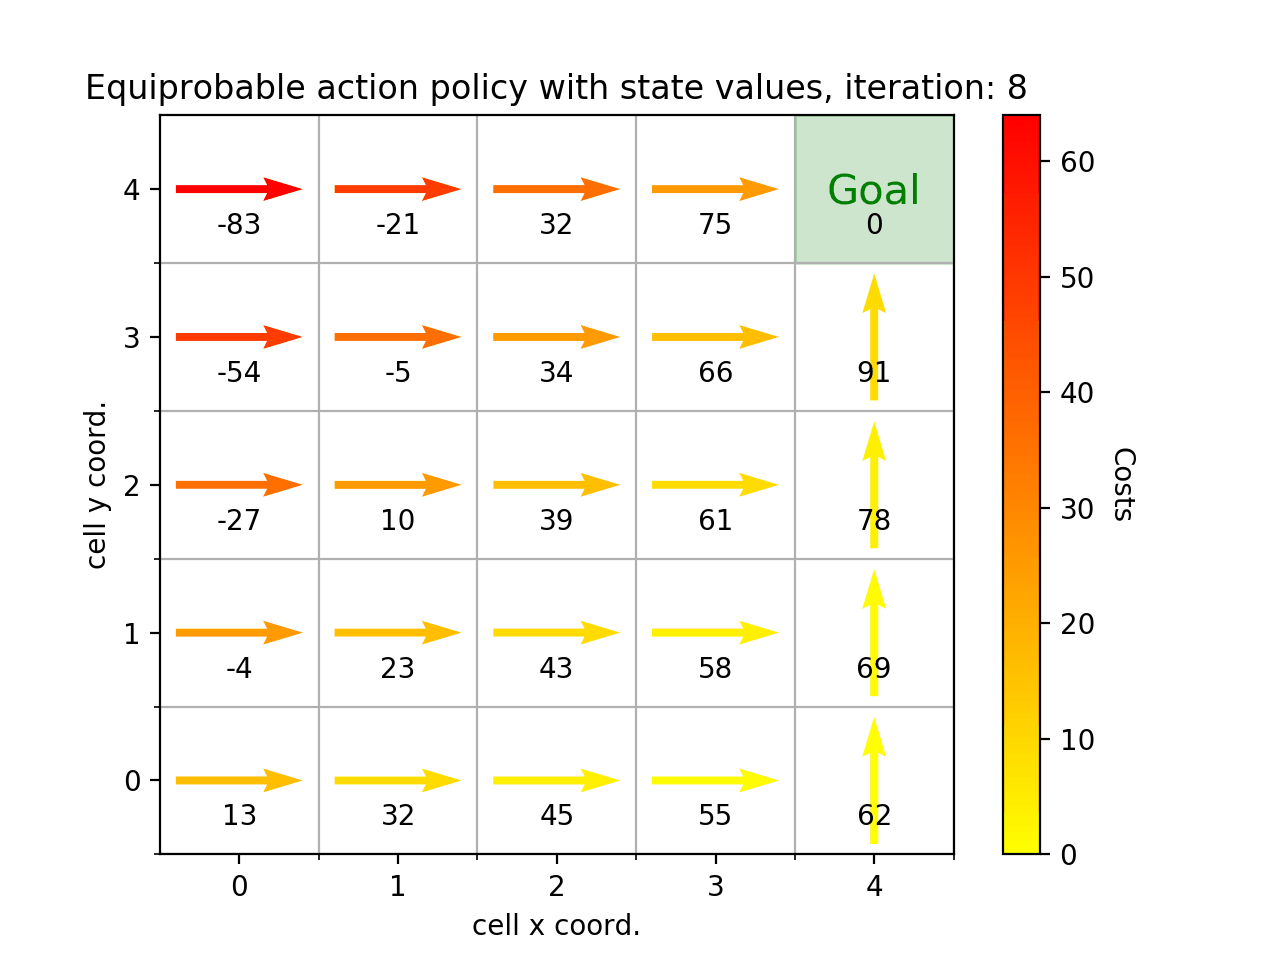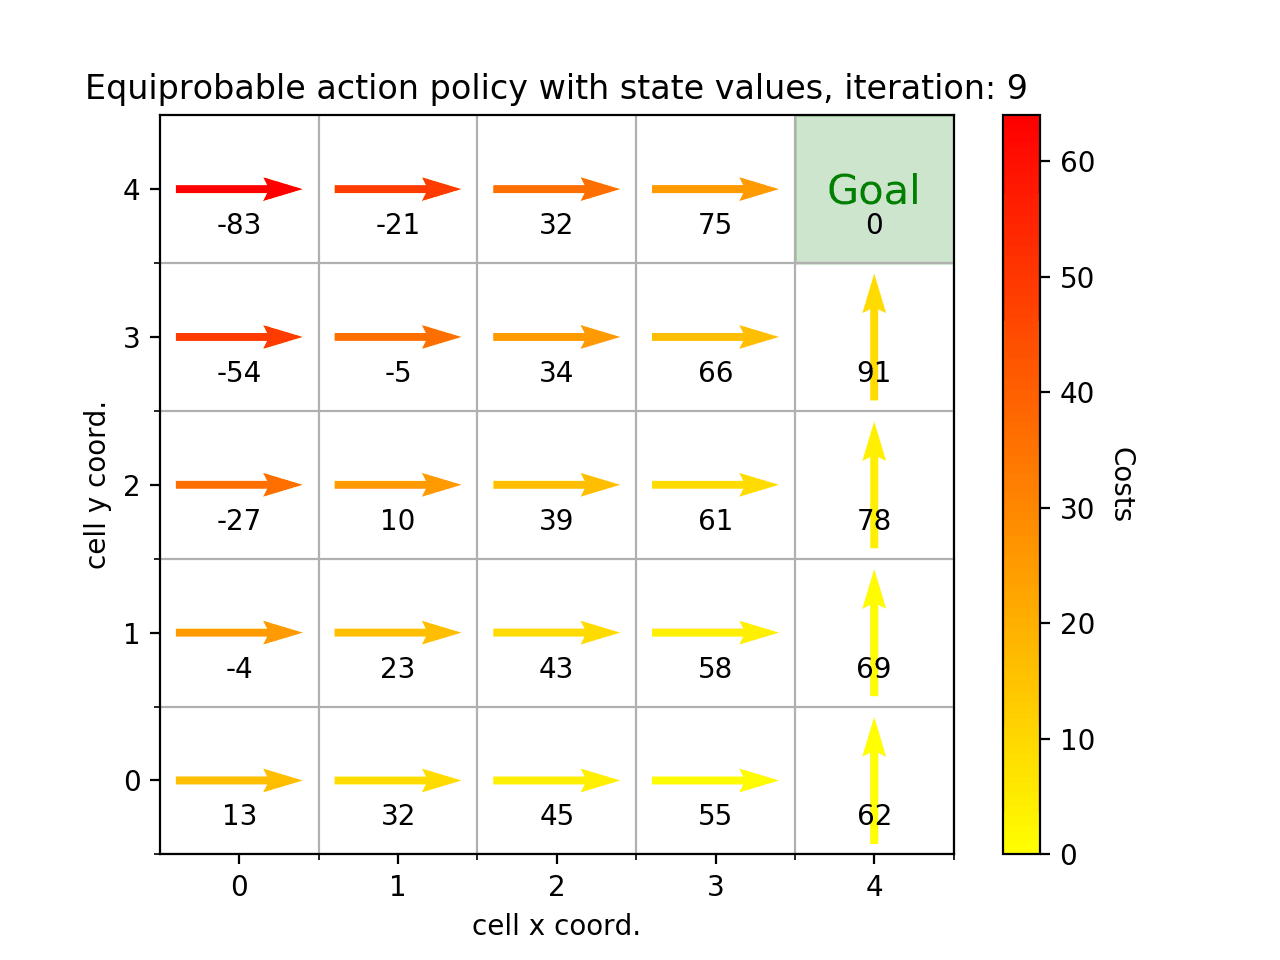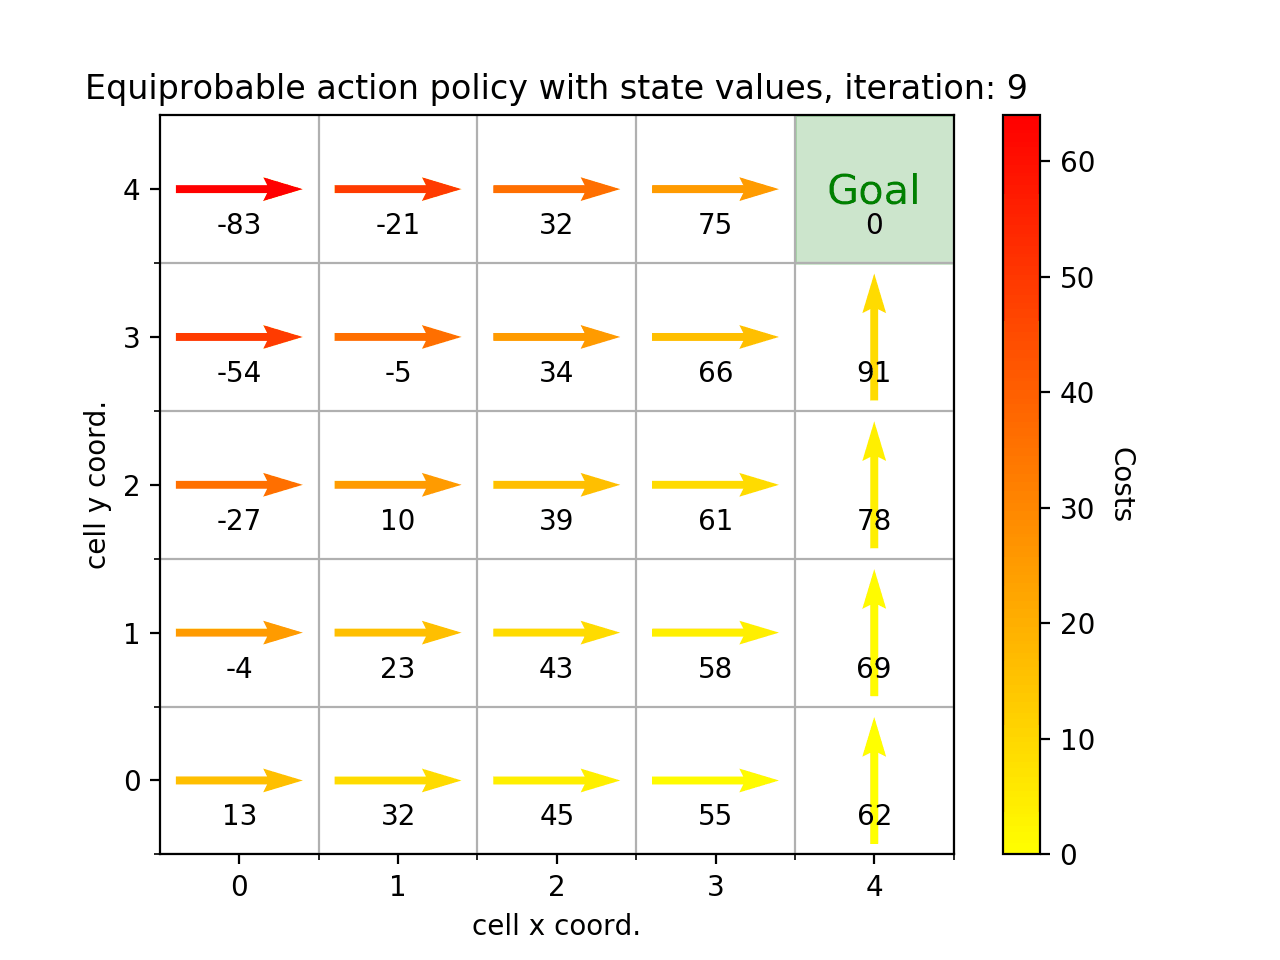
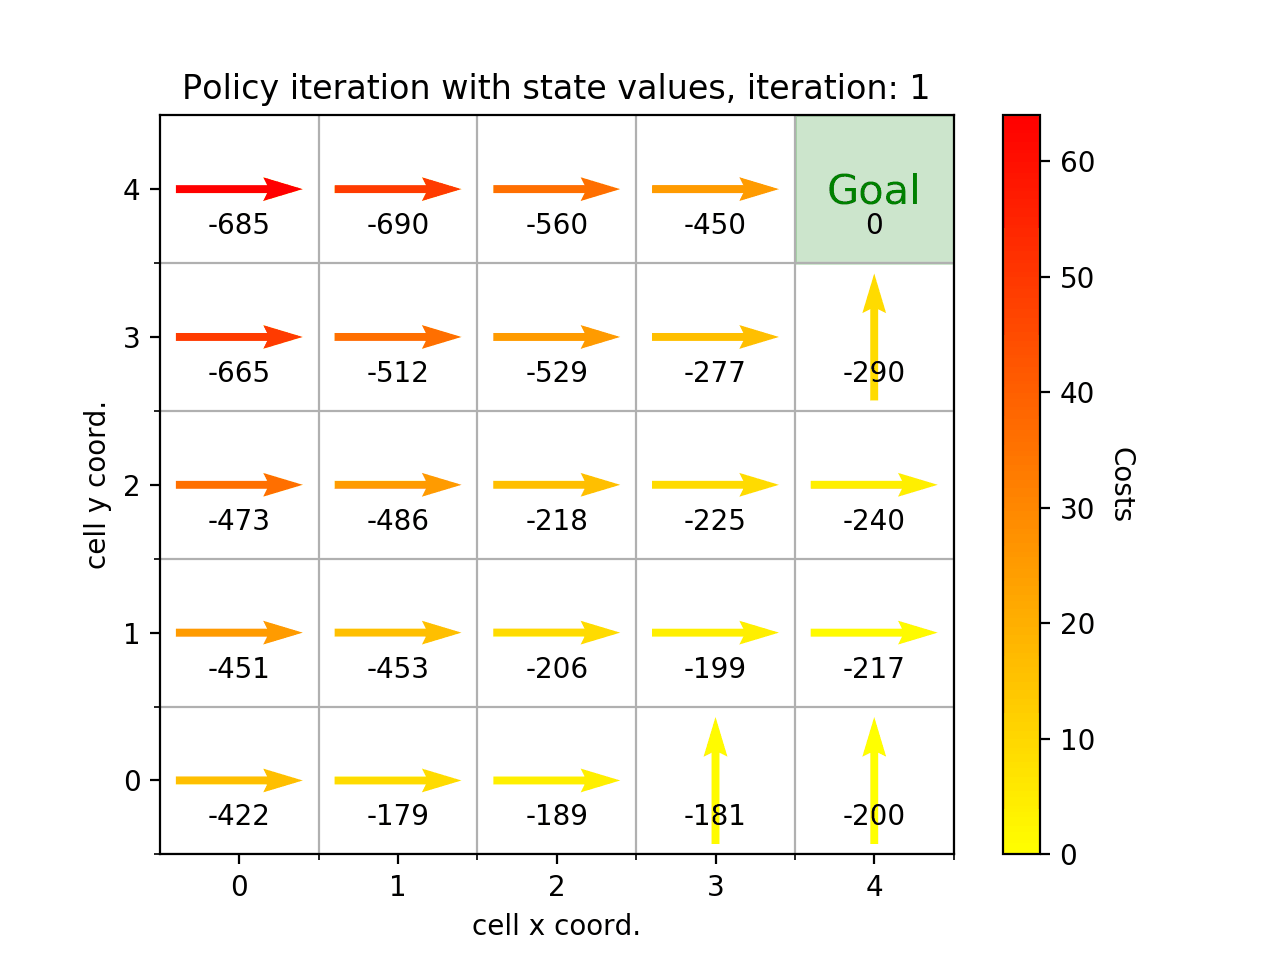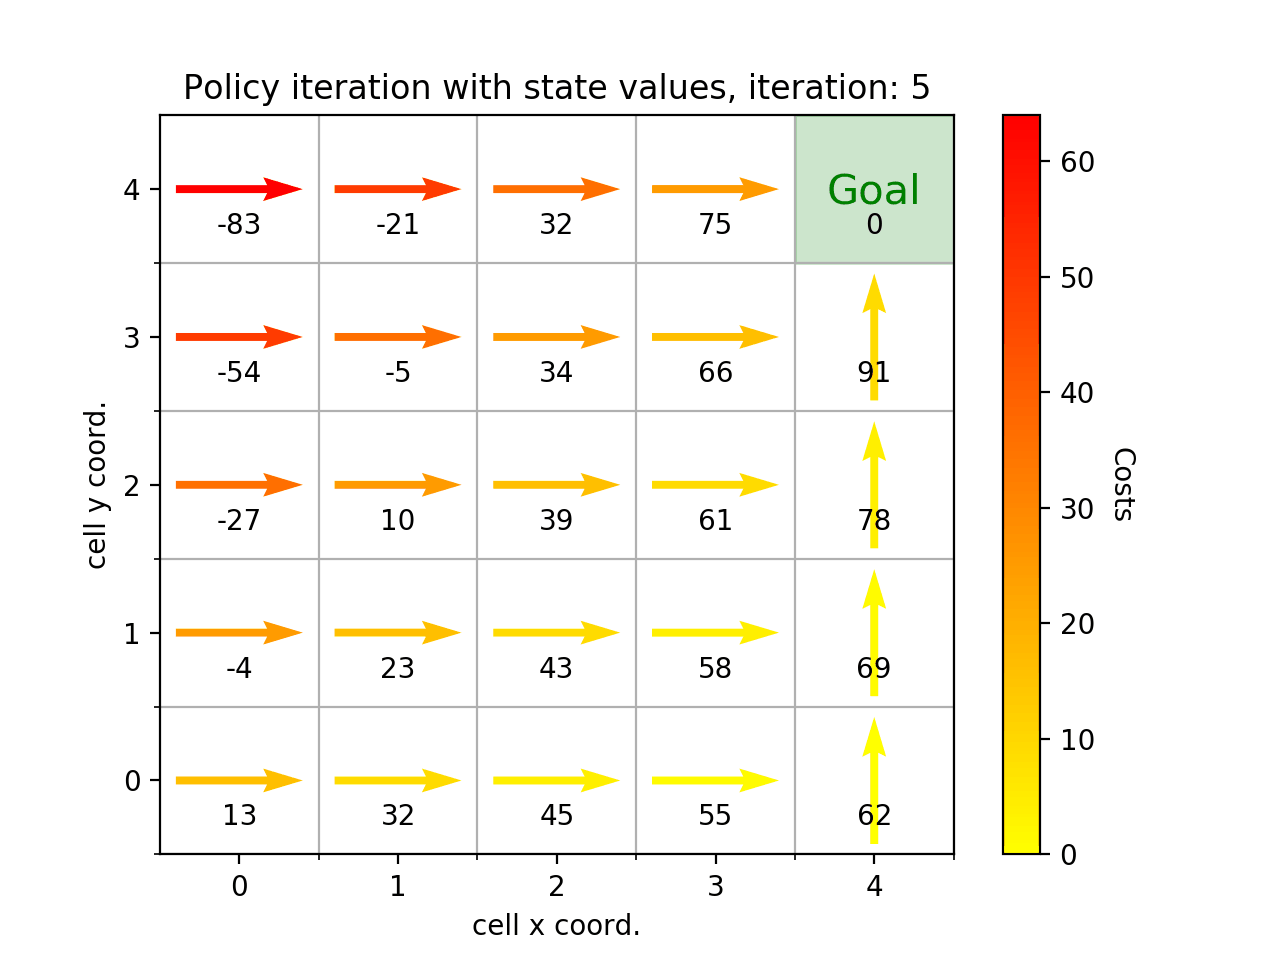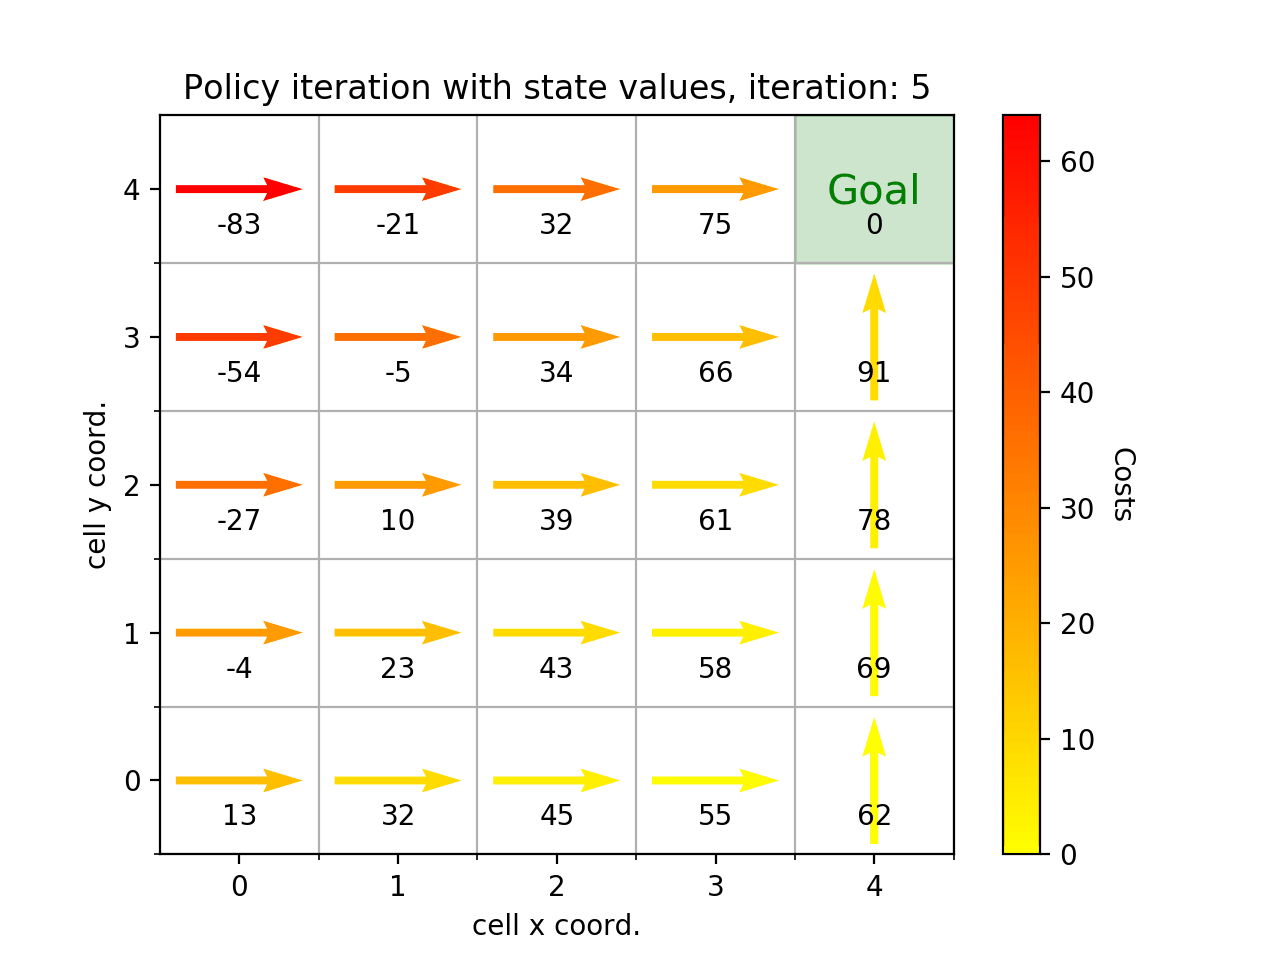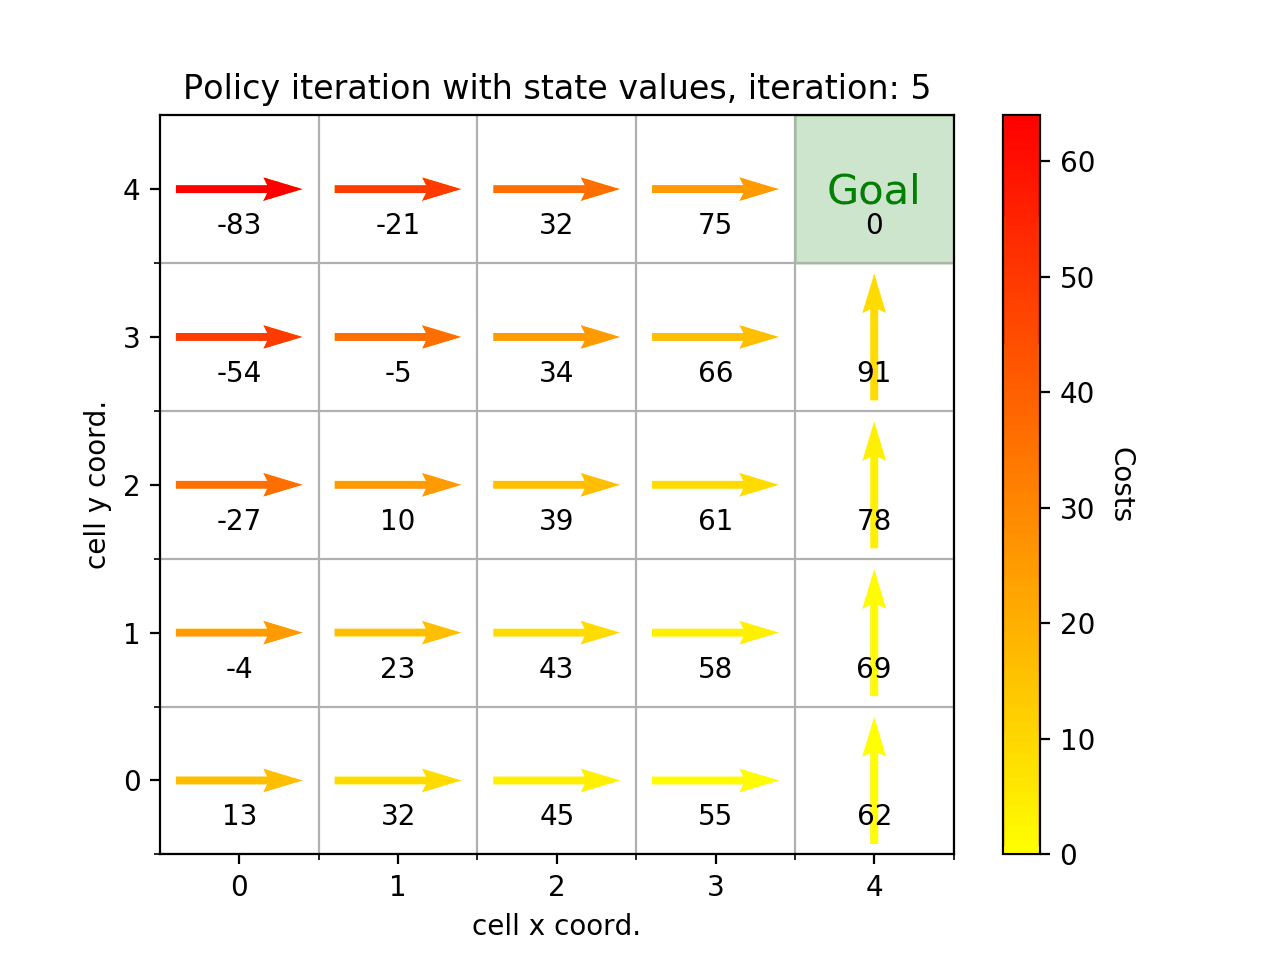
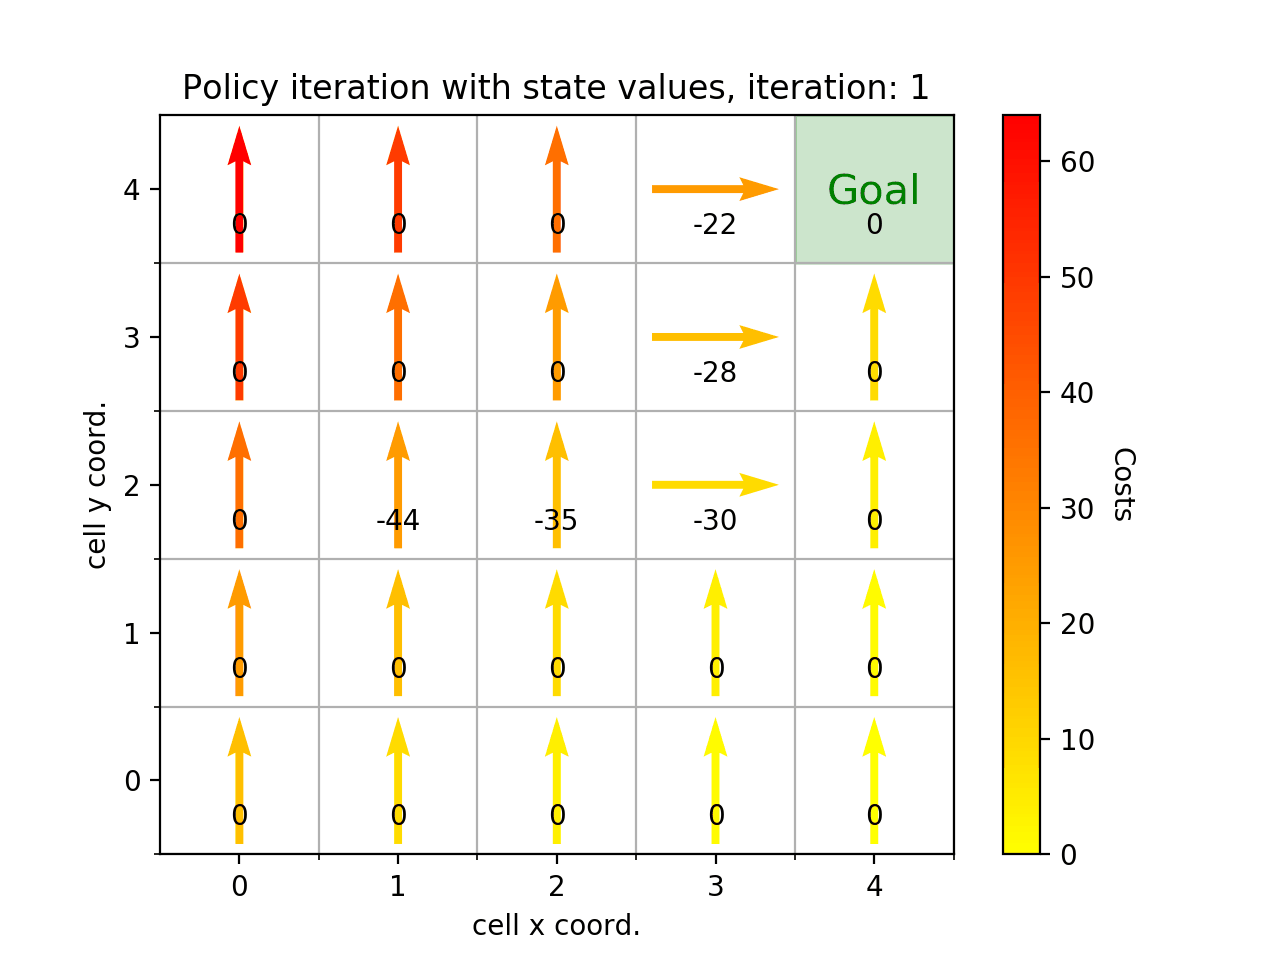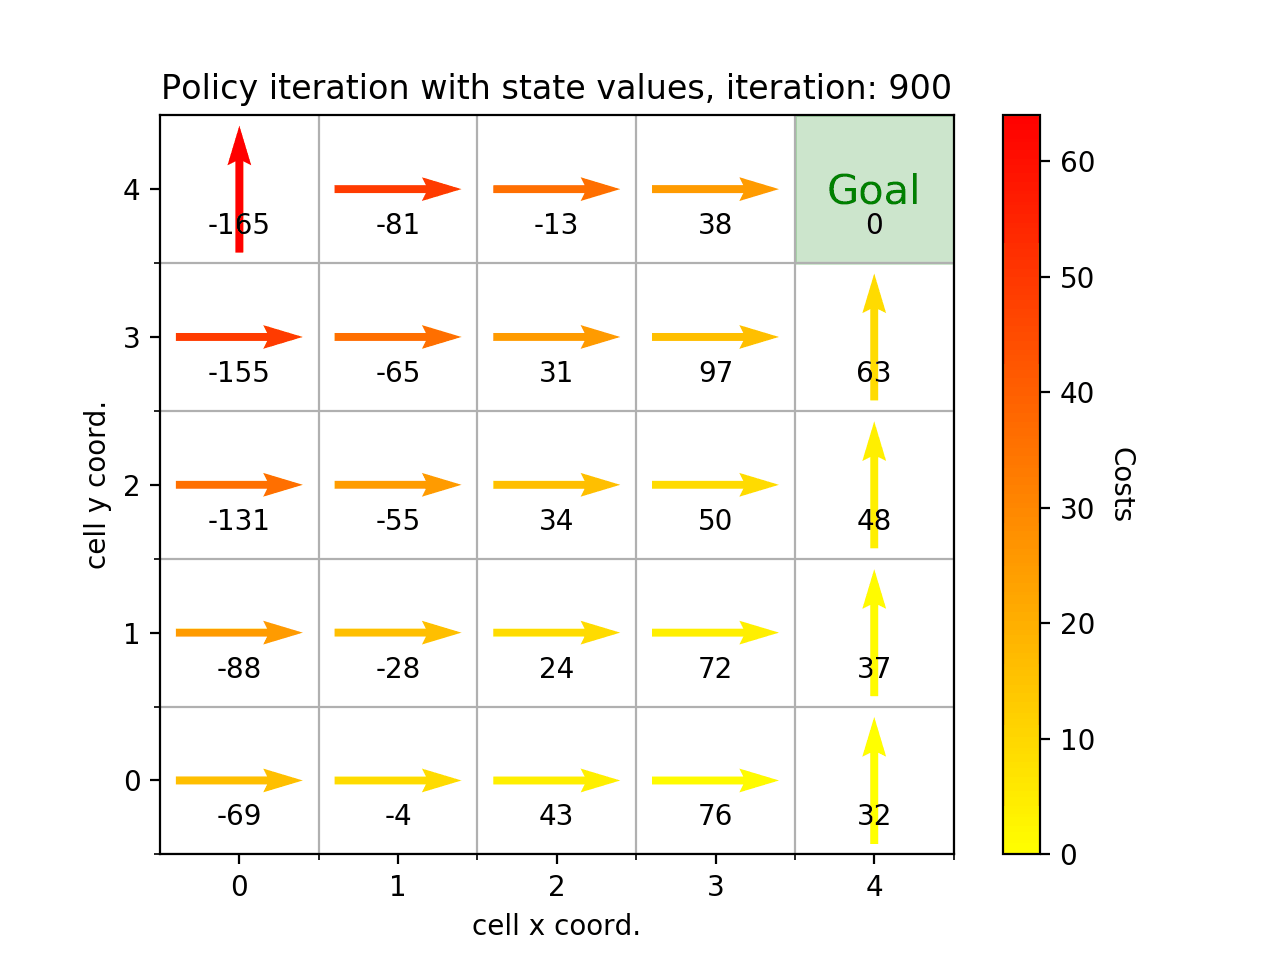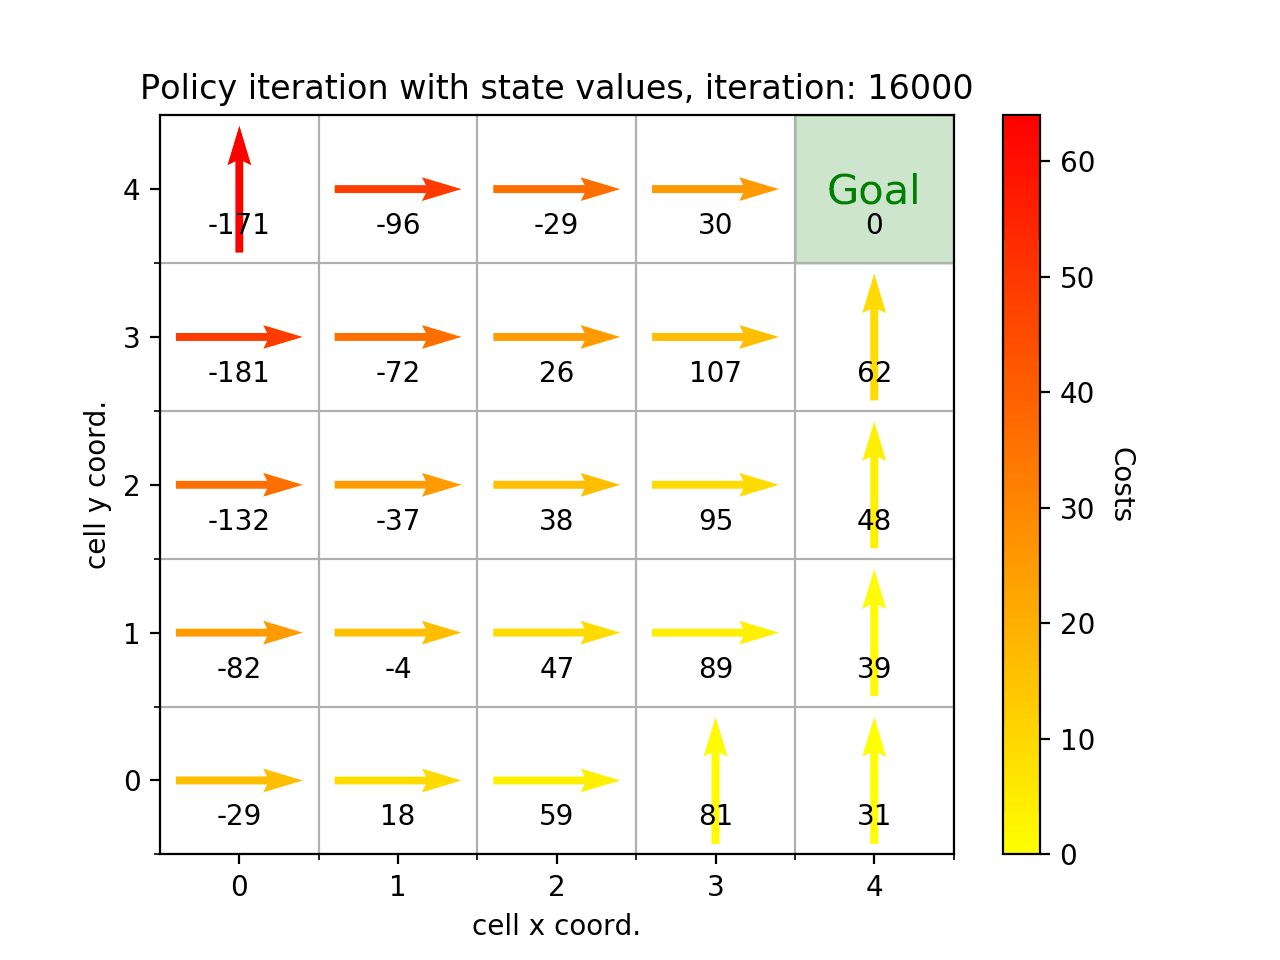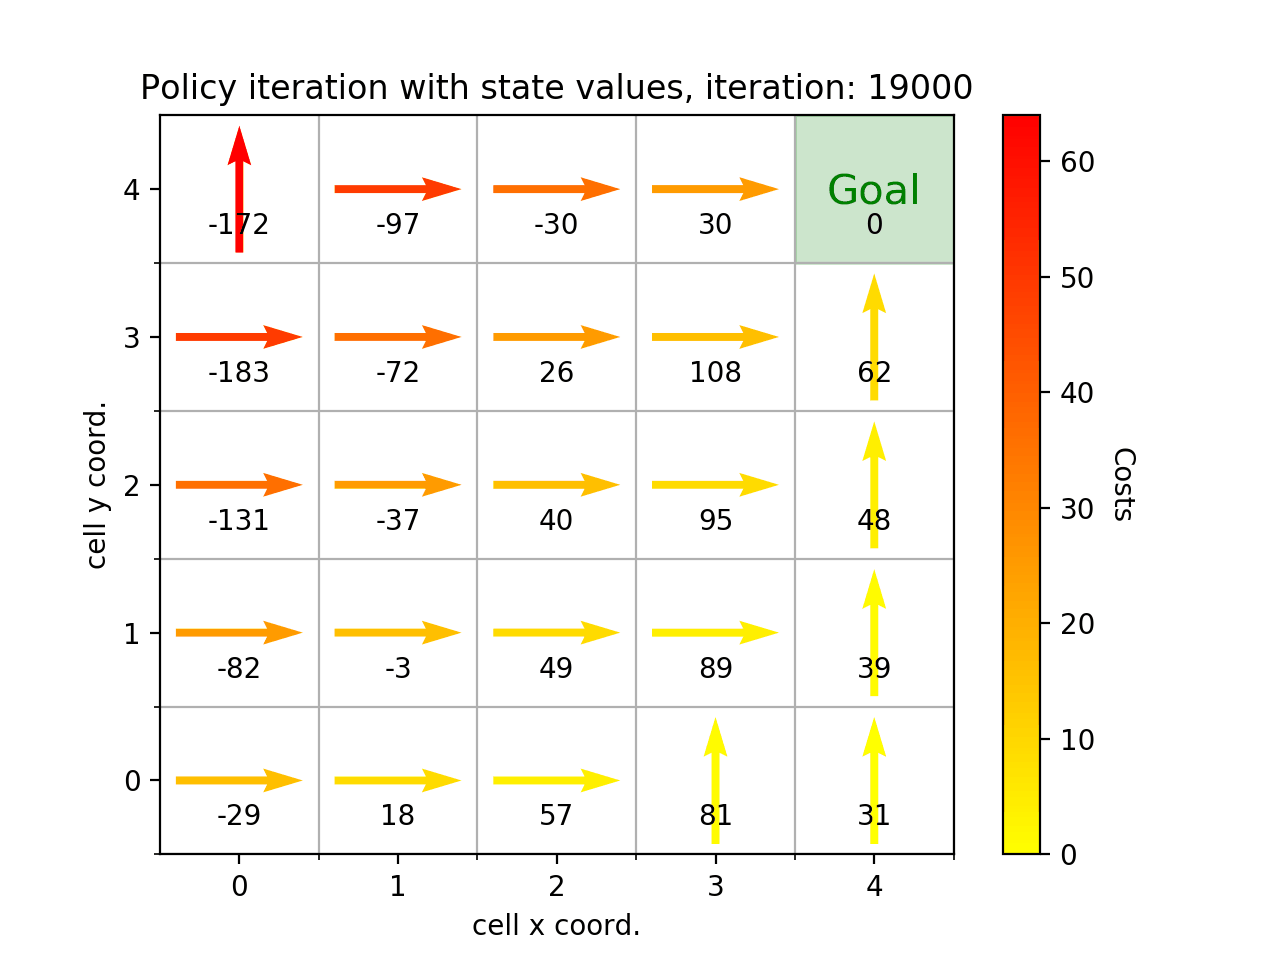
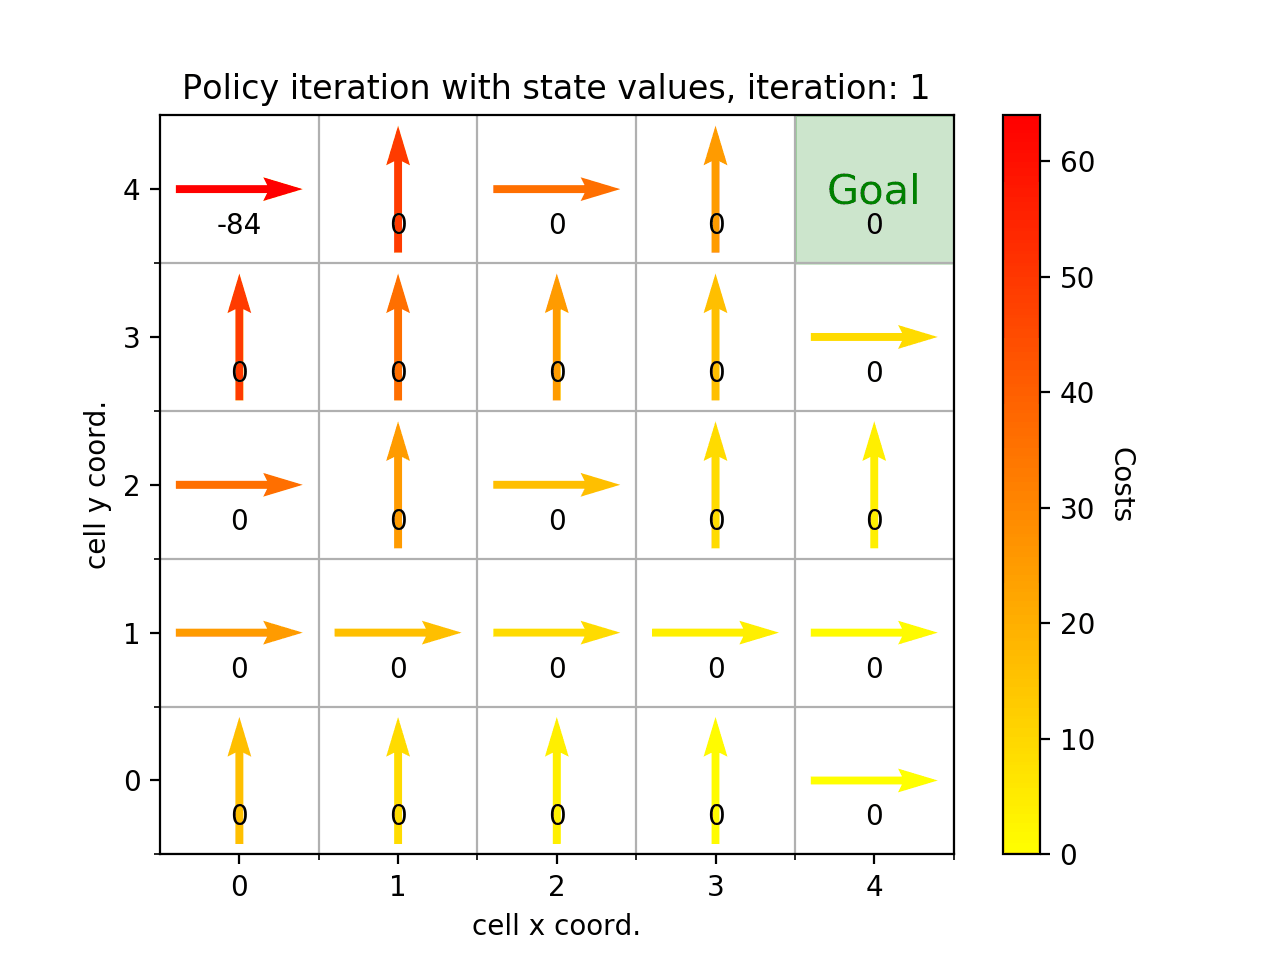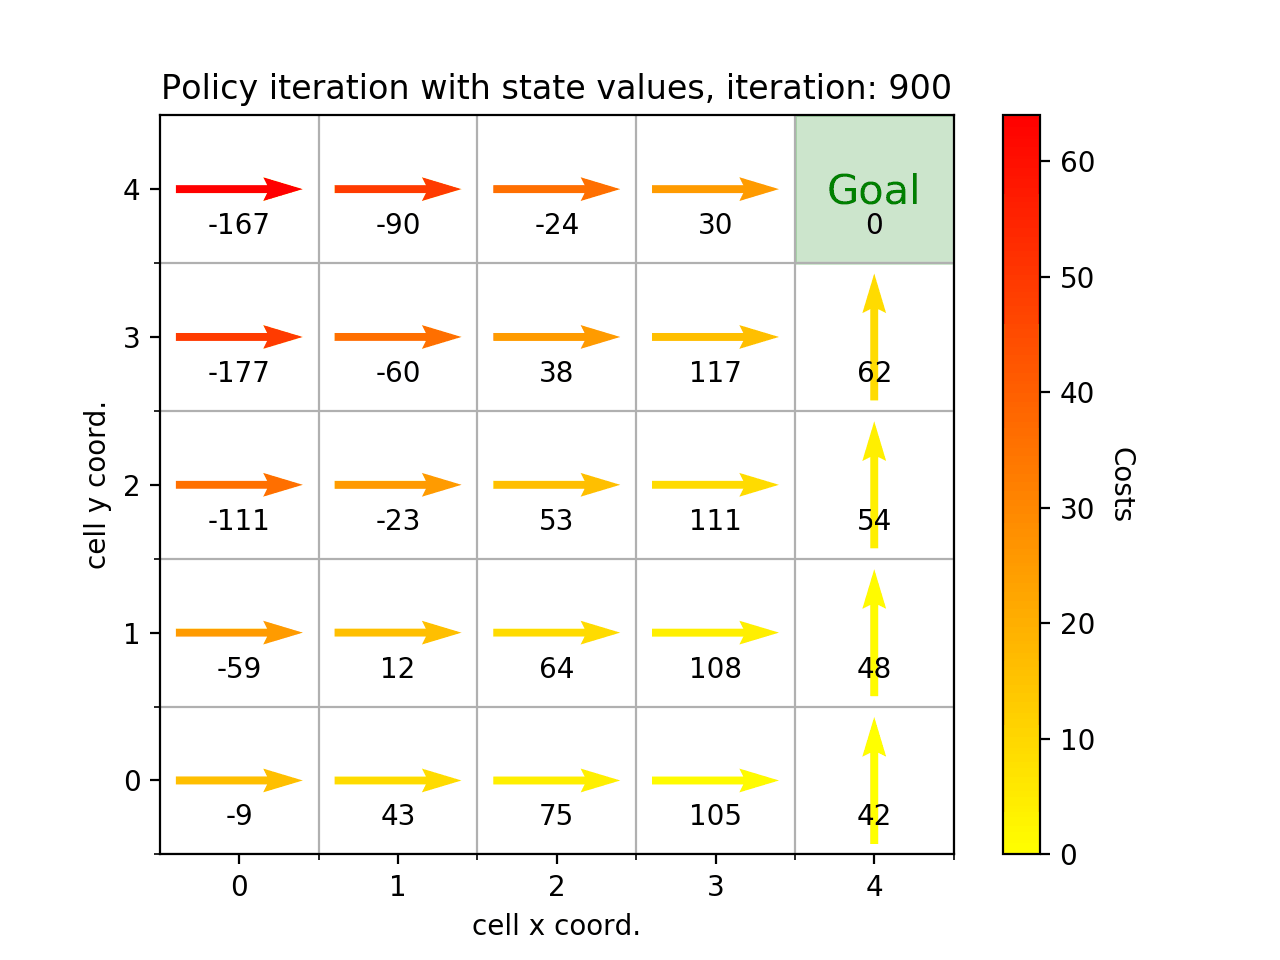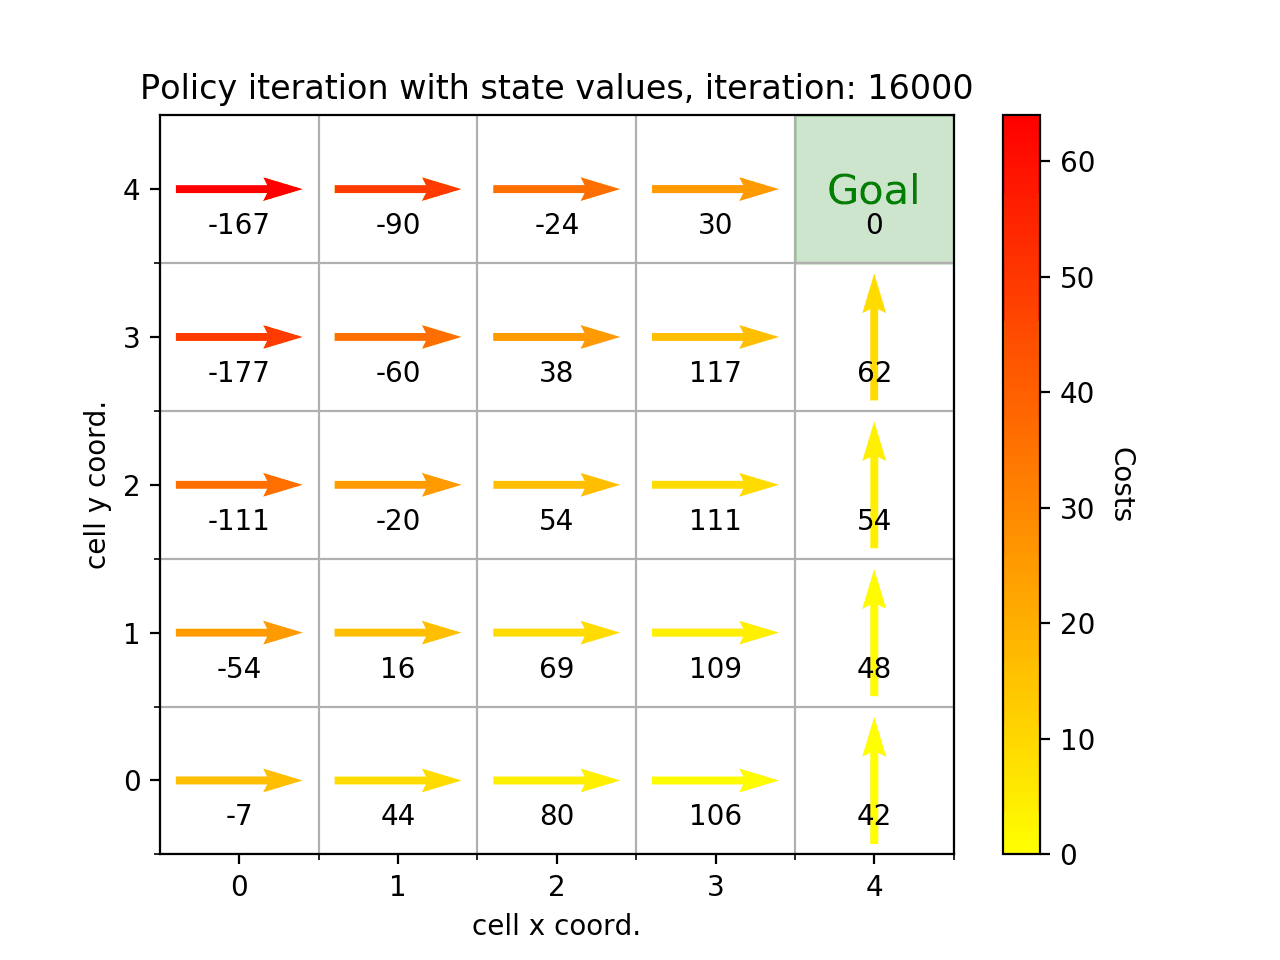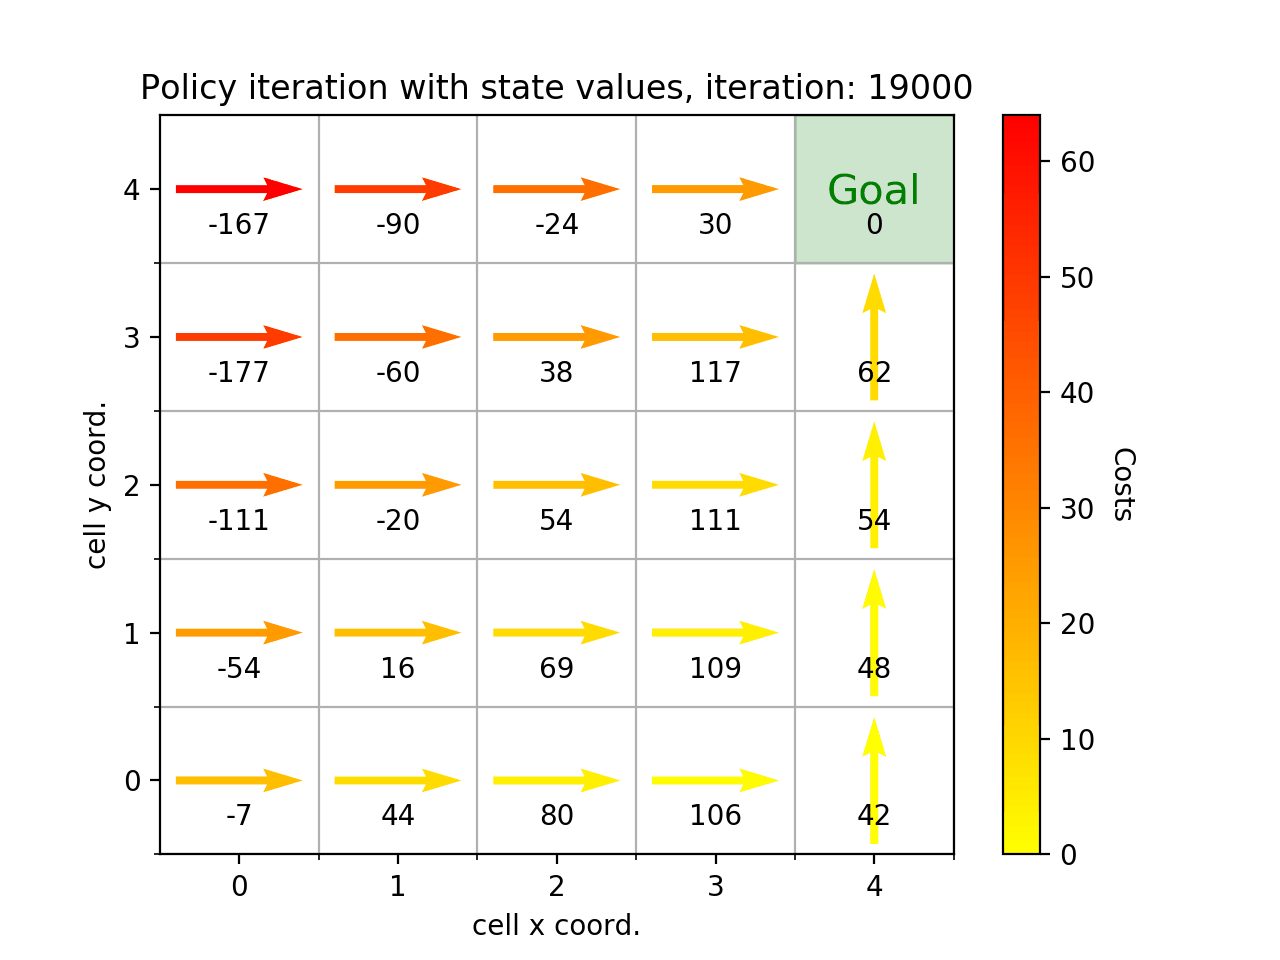
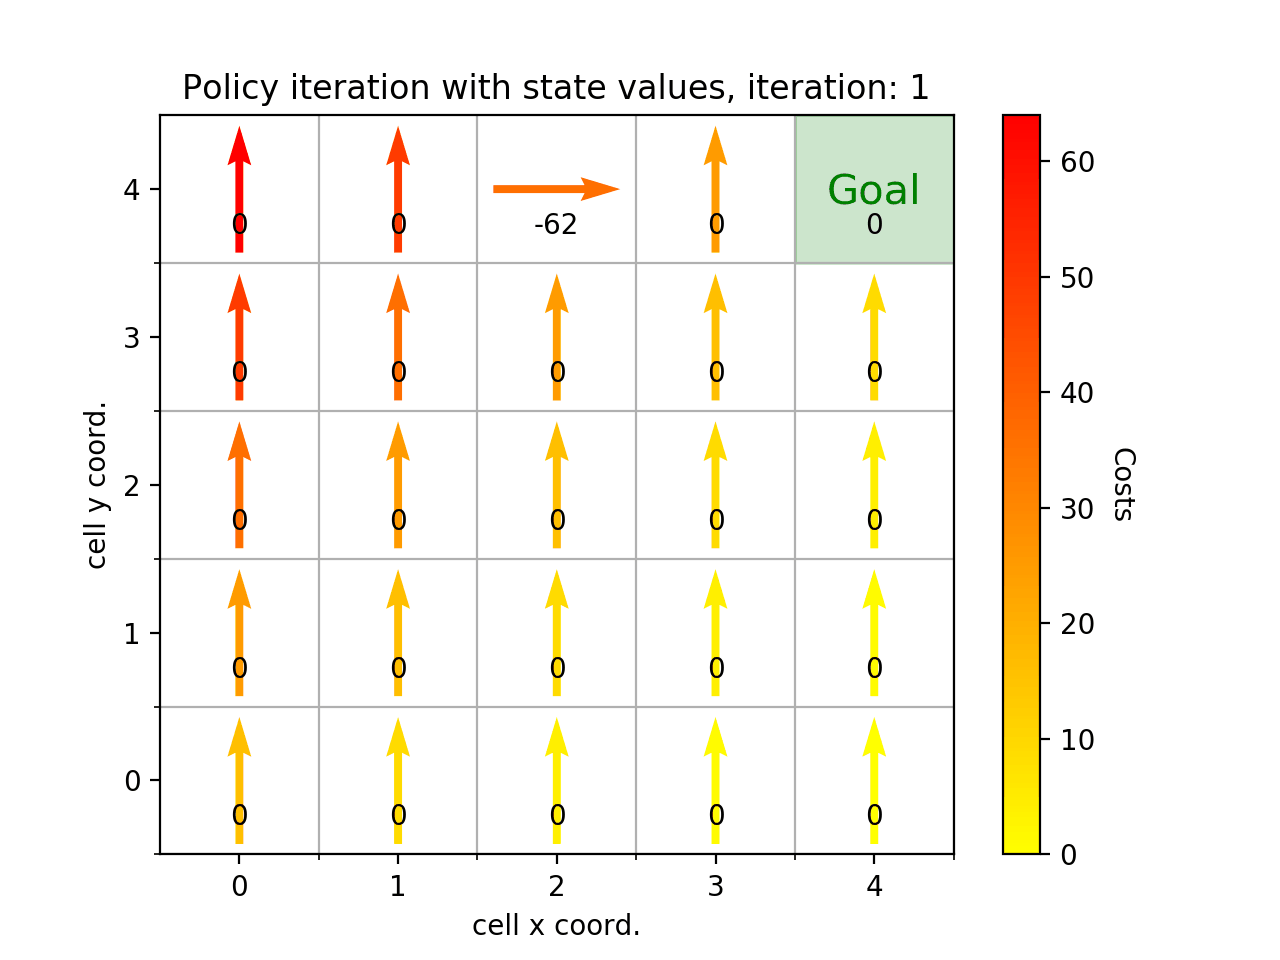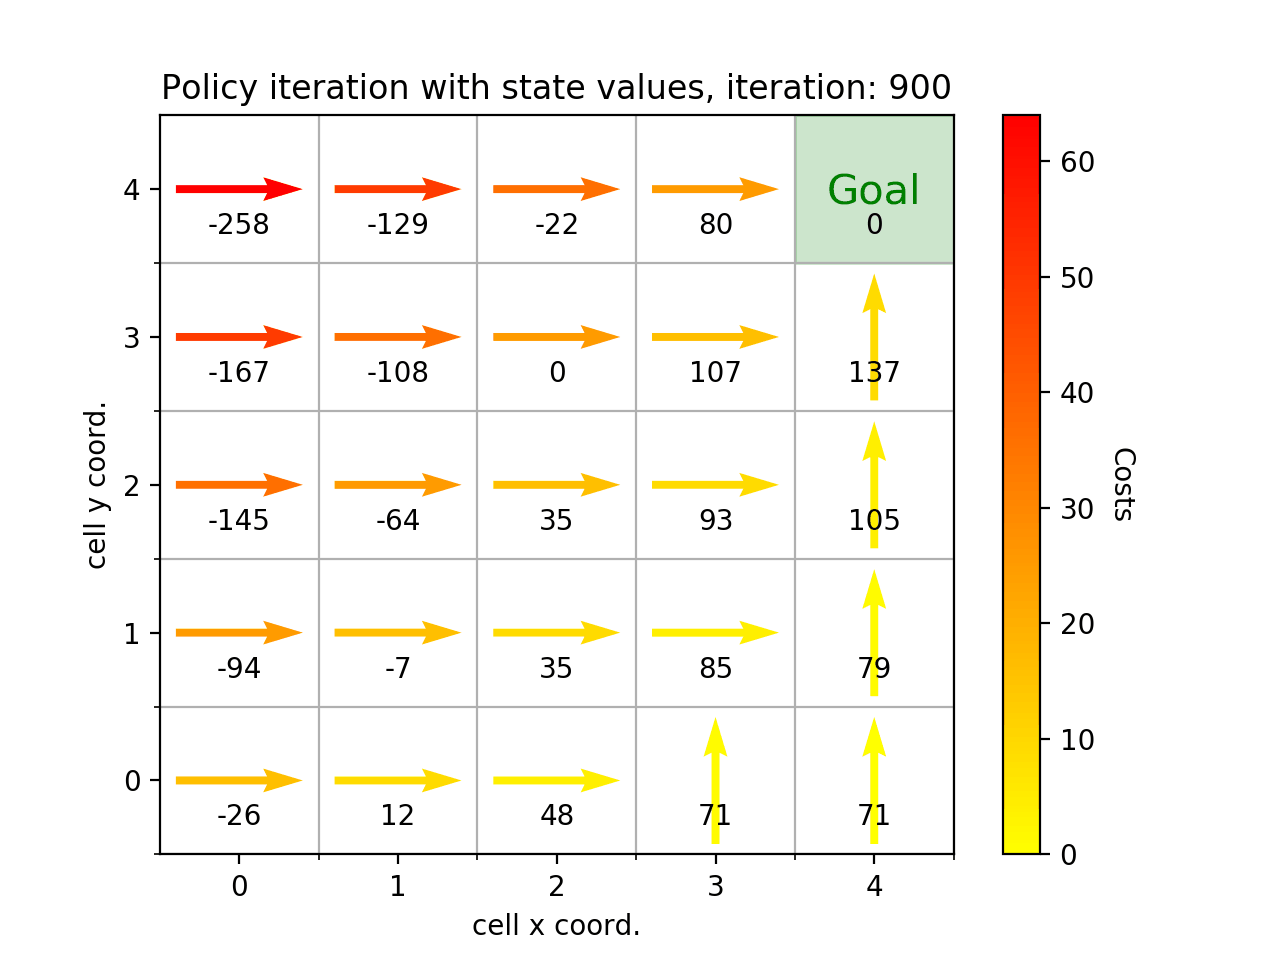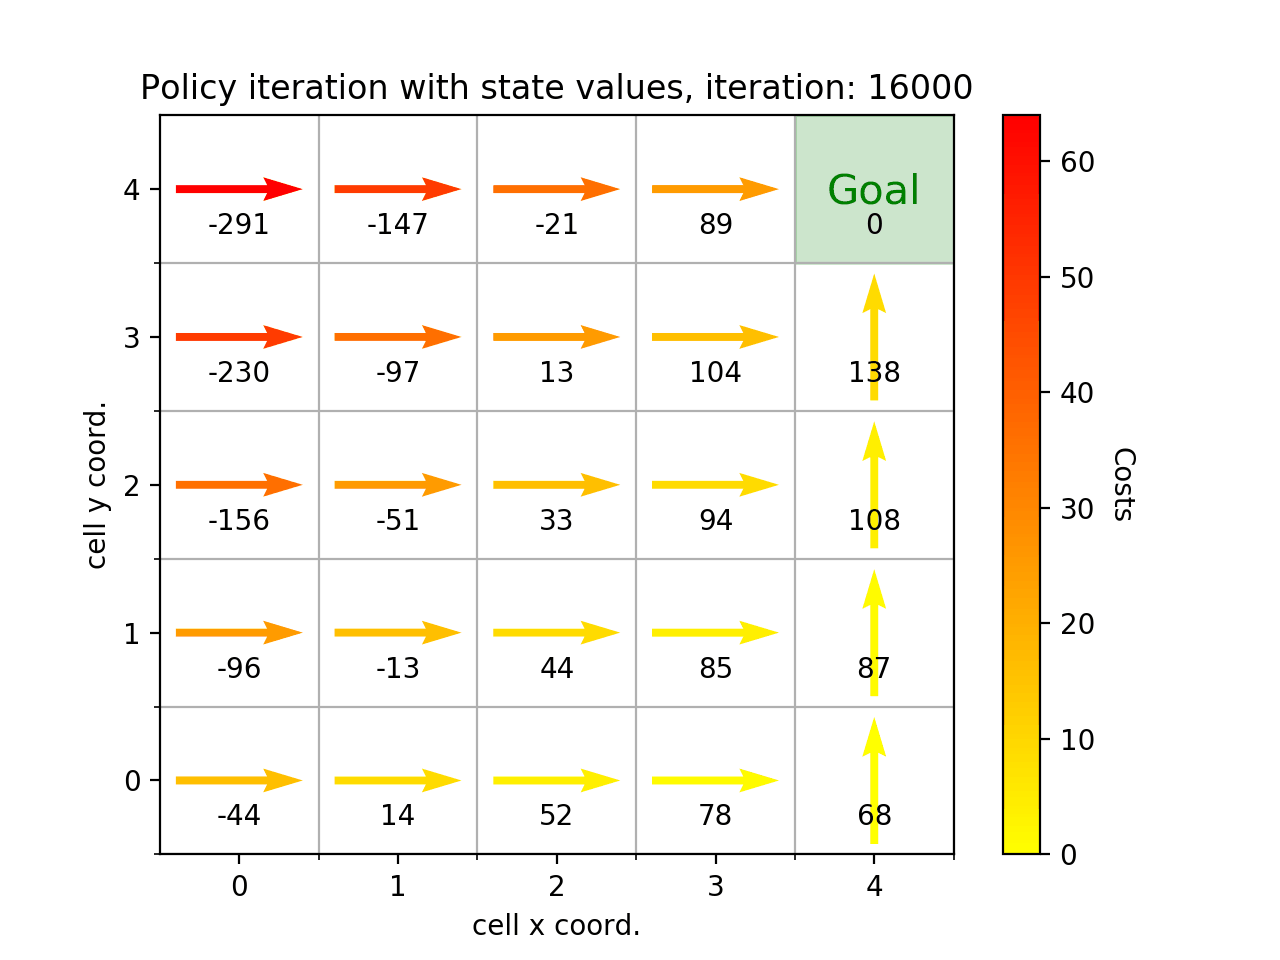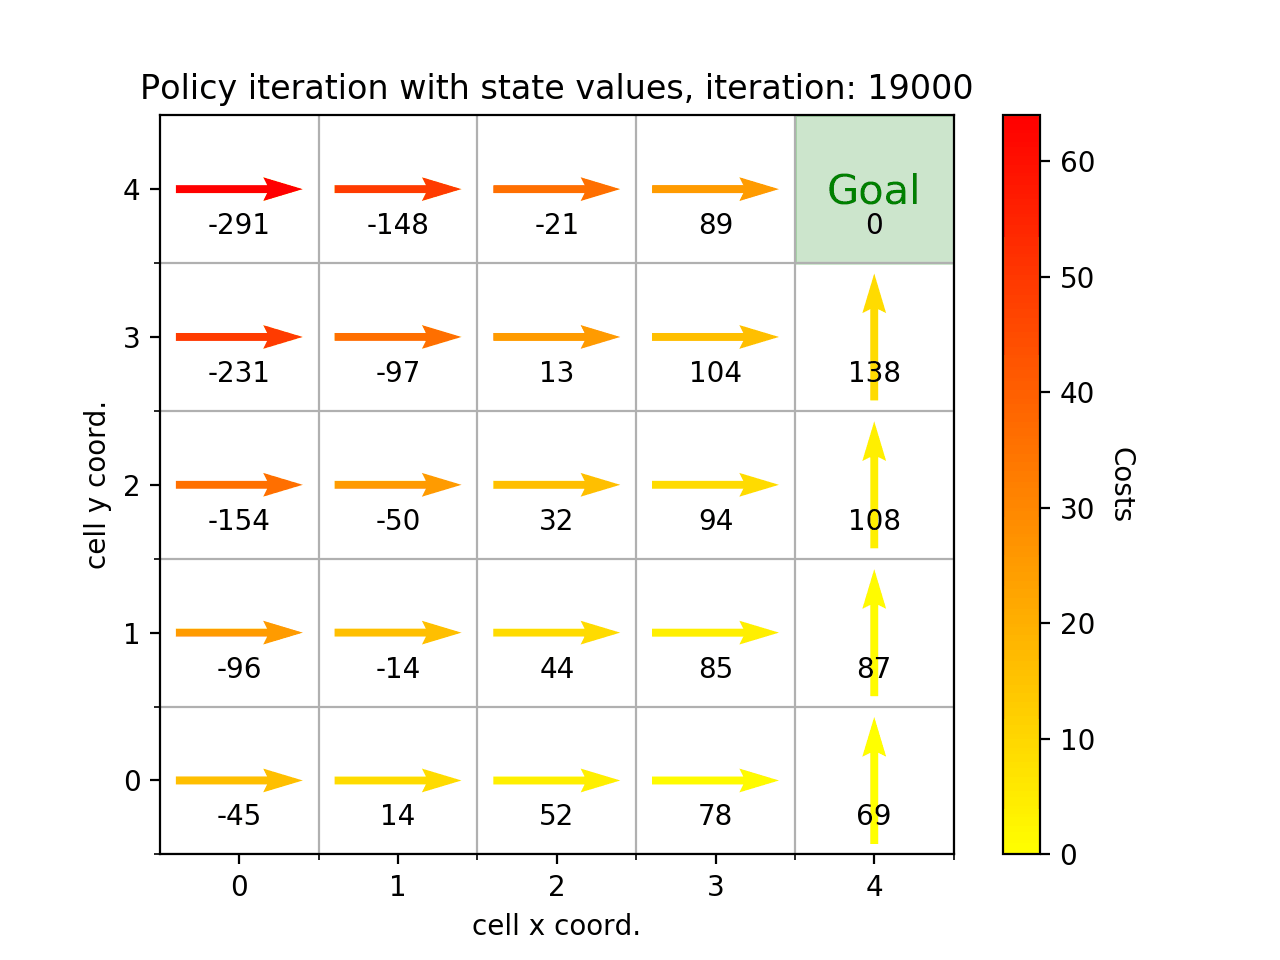
Learning gvalue function and greedy policy on my gridworld.
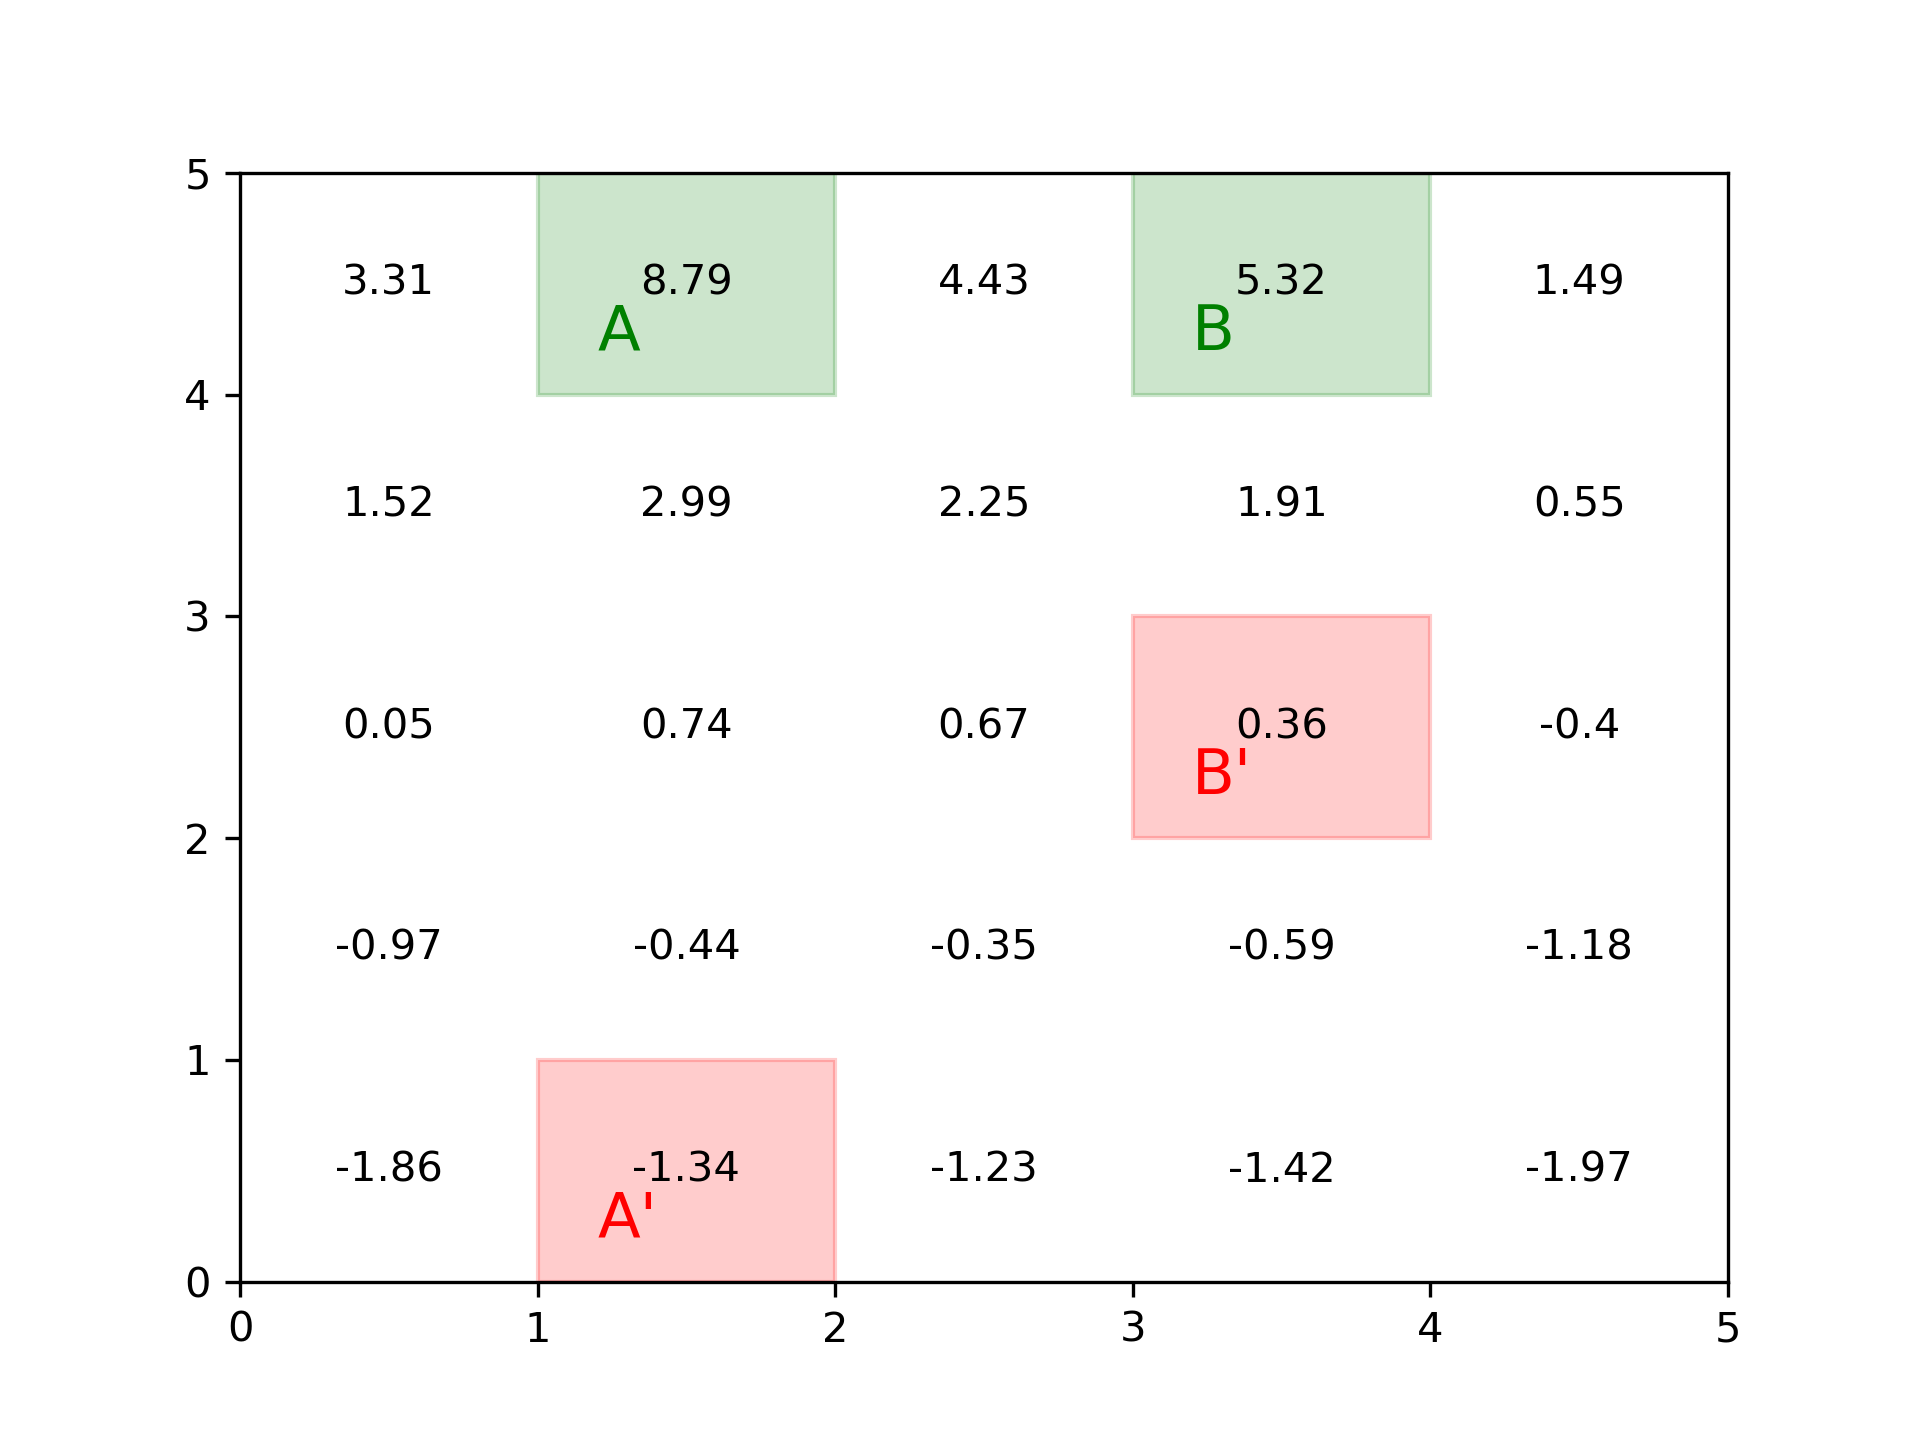
Optimal Policies and Optimal Value Functions
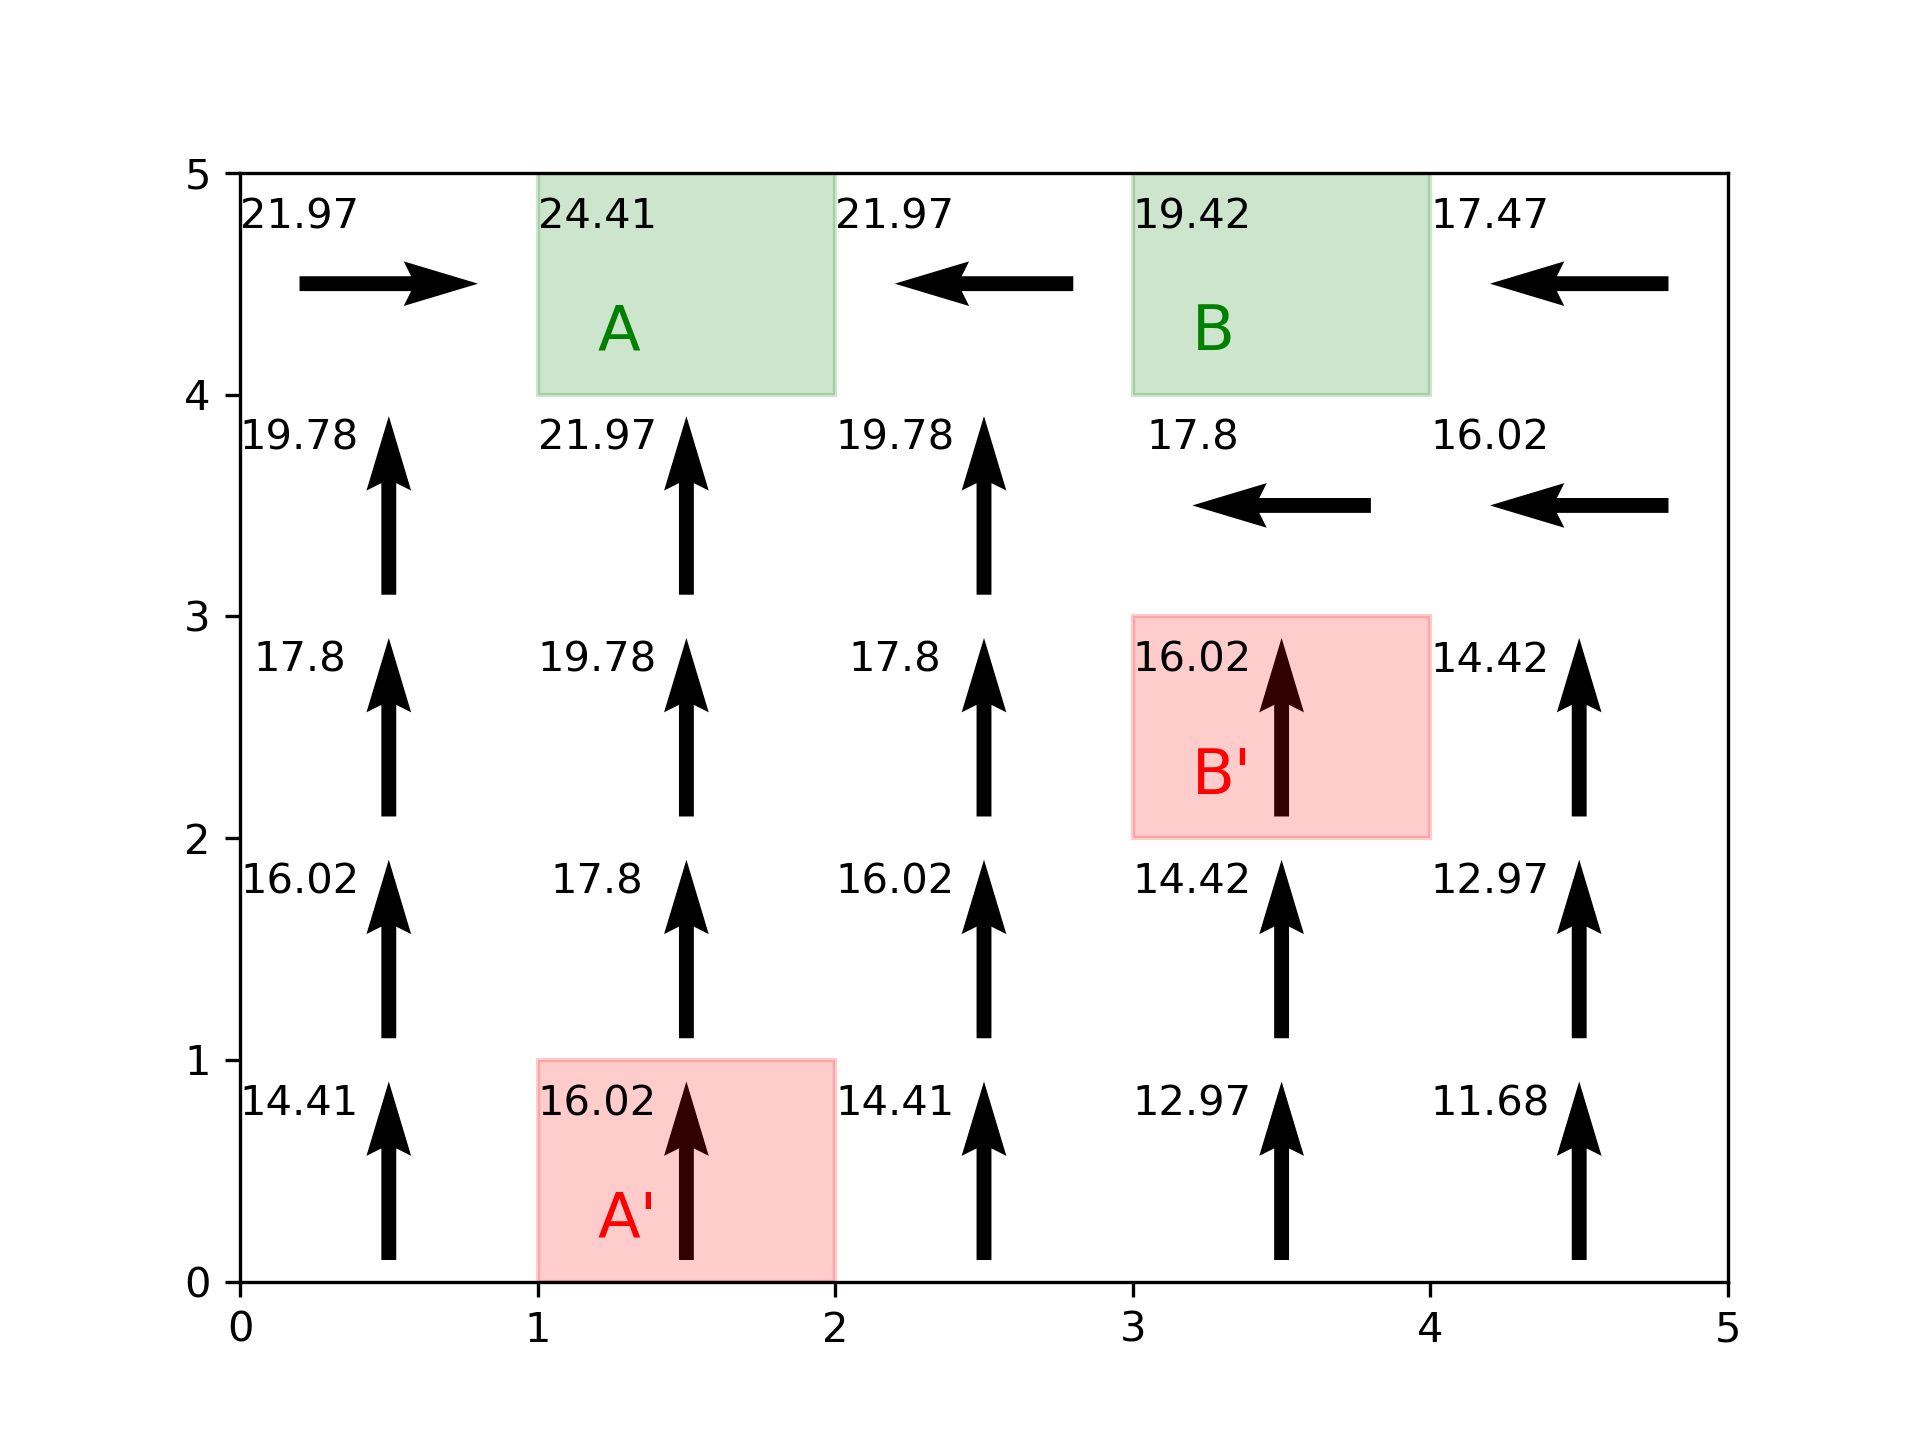
Optimality and Approximation
Policy Evaluation (Prediction)
Policy Improvement
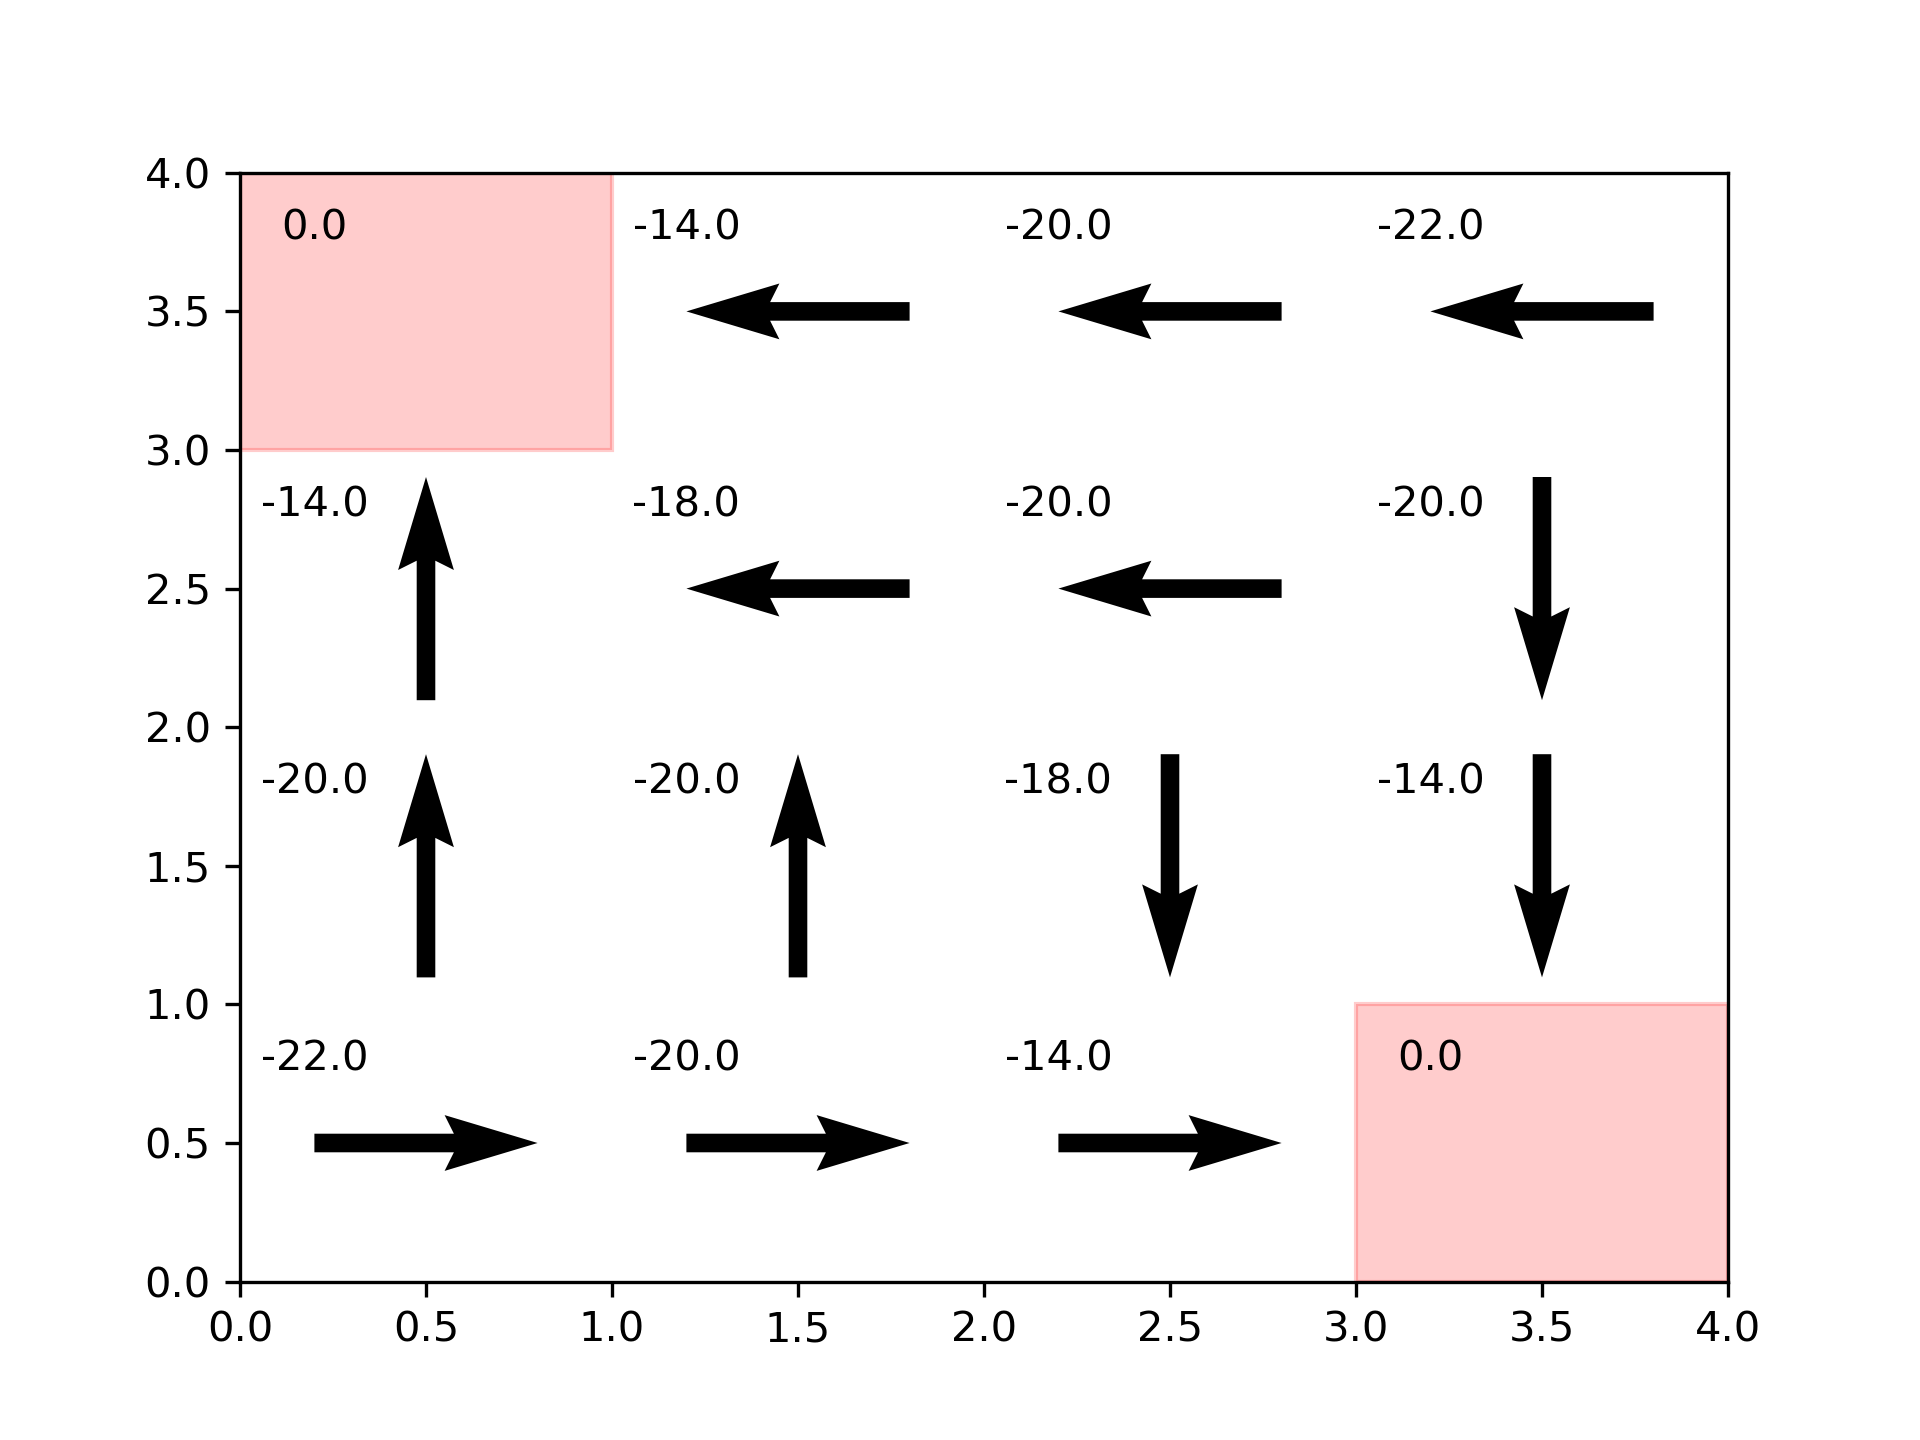
Policy Iteration
Value Iteration
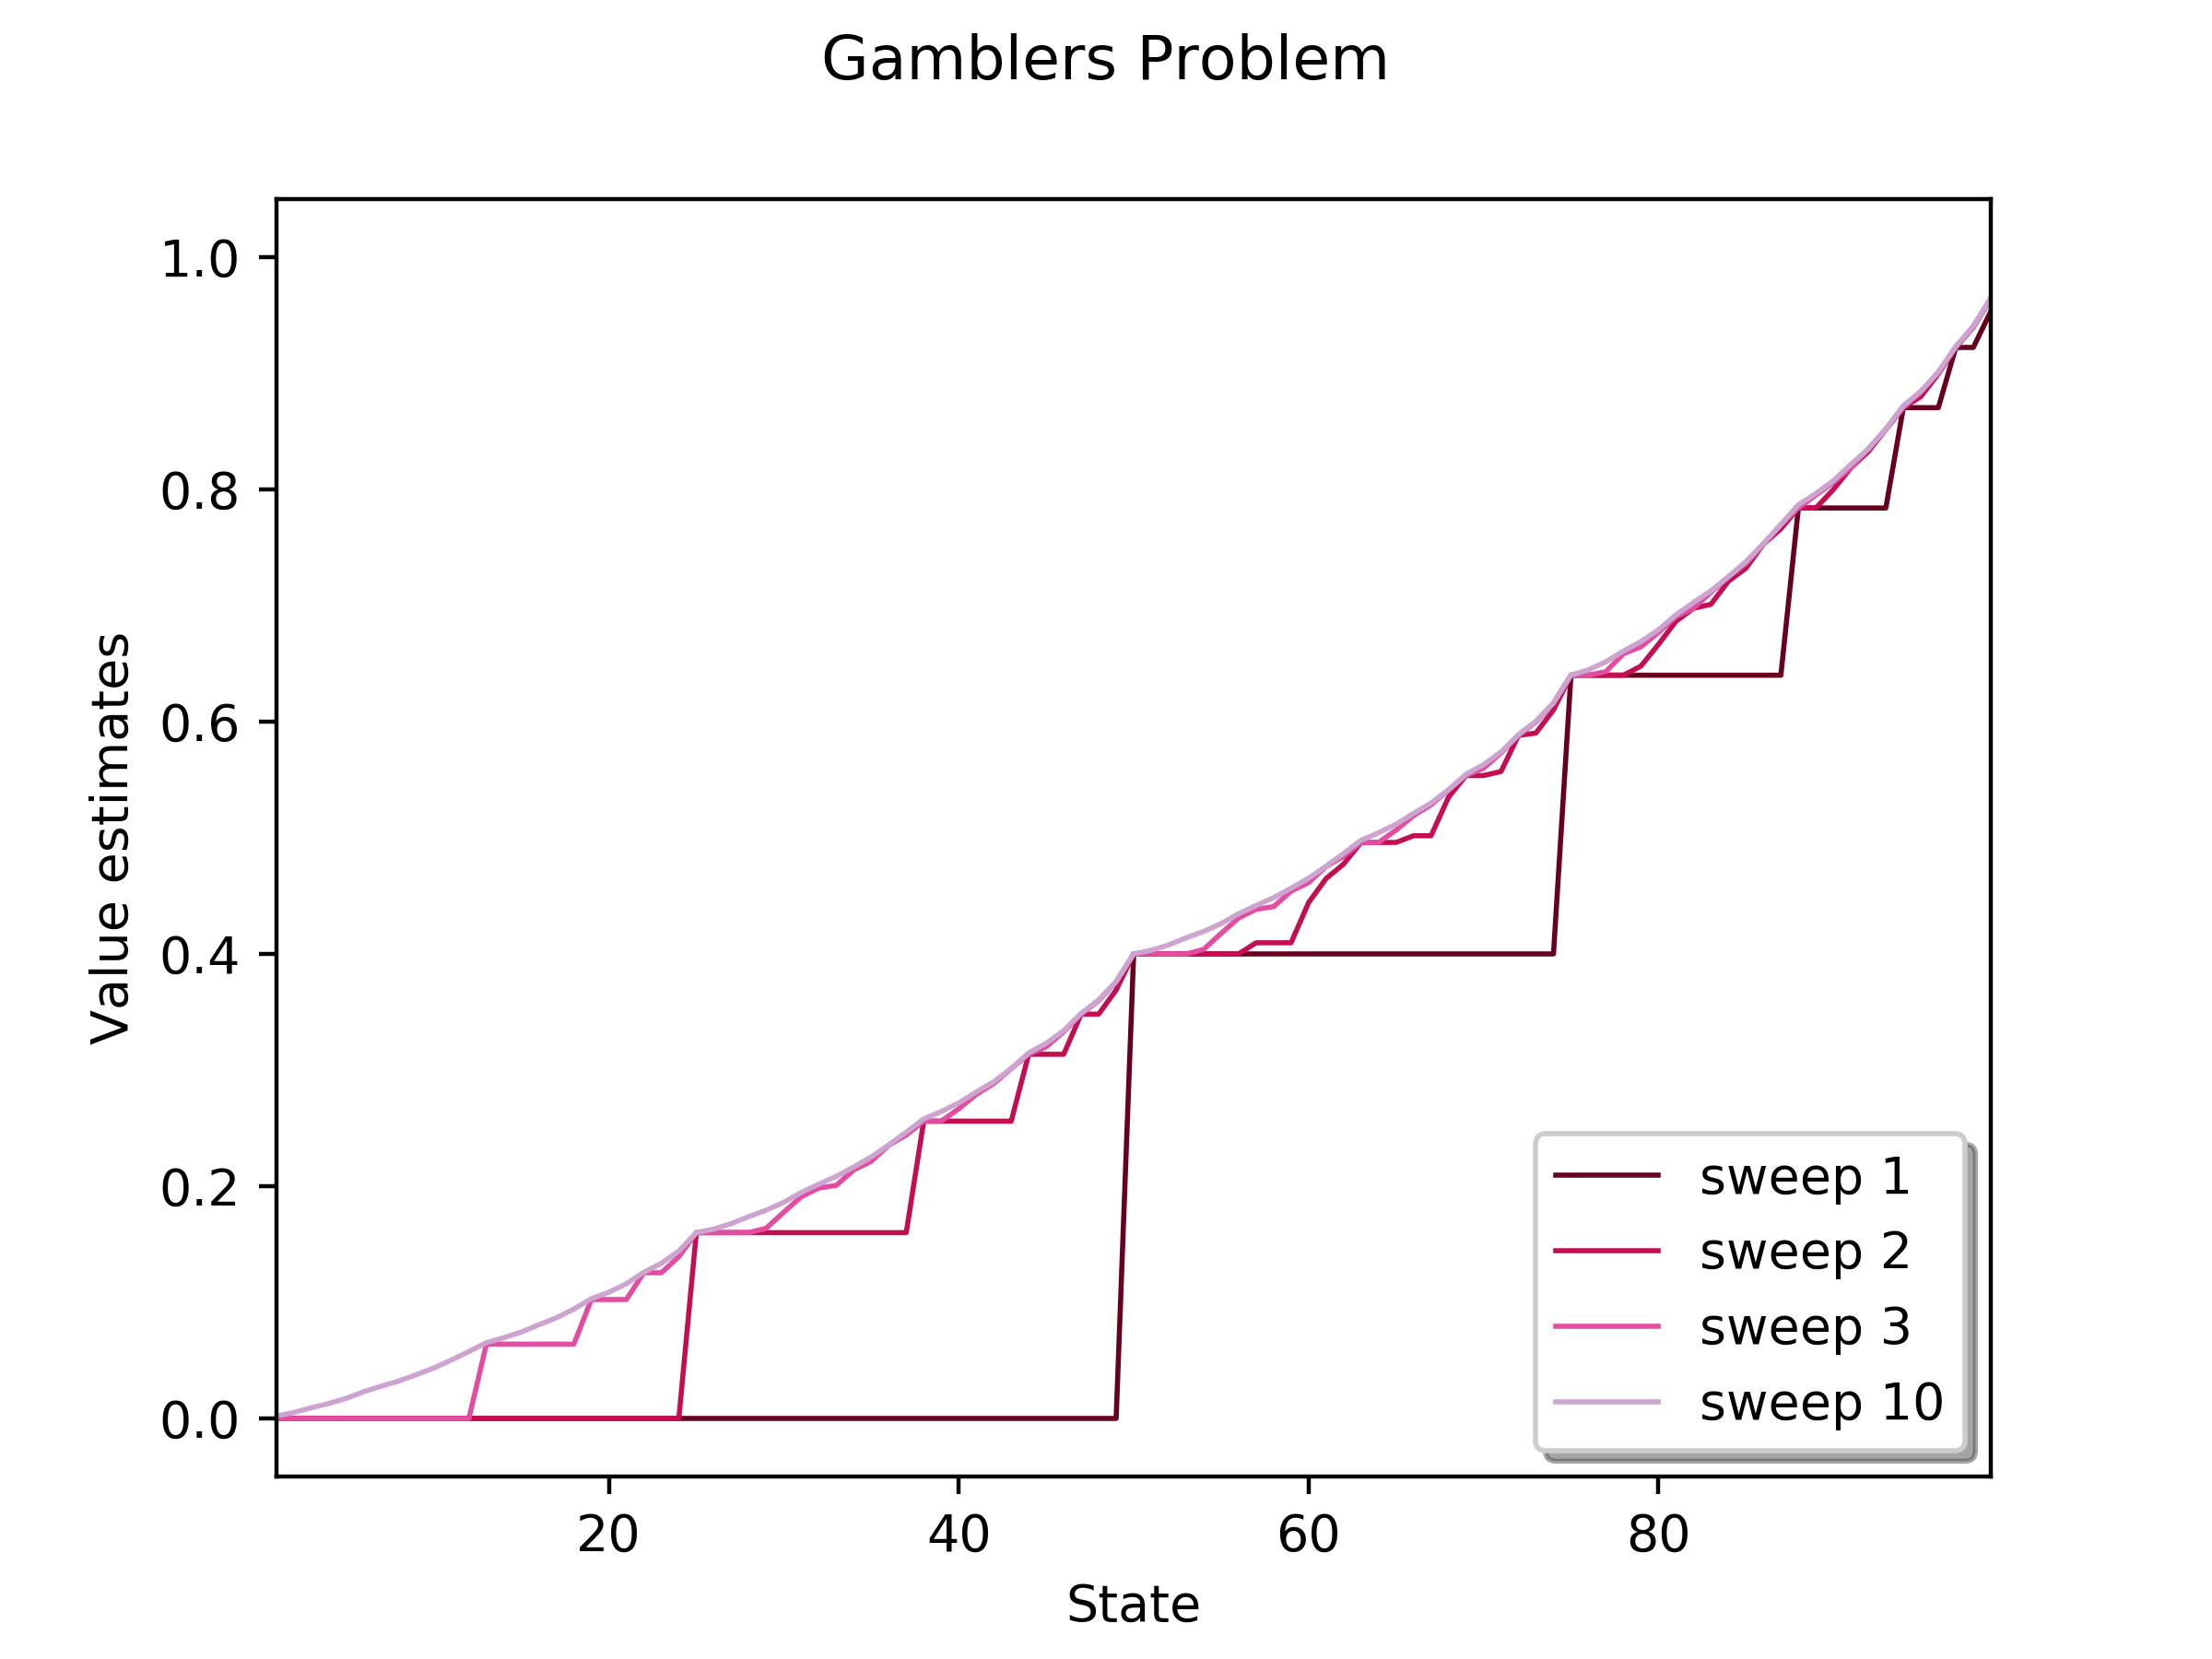
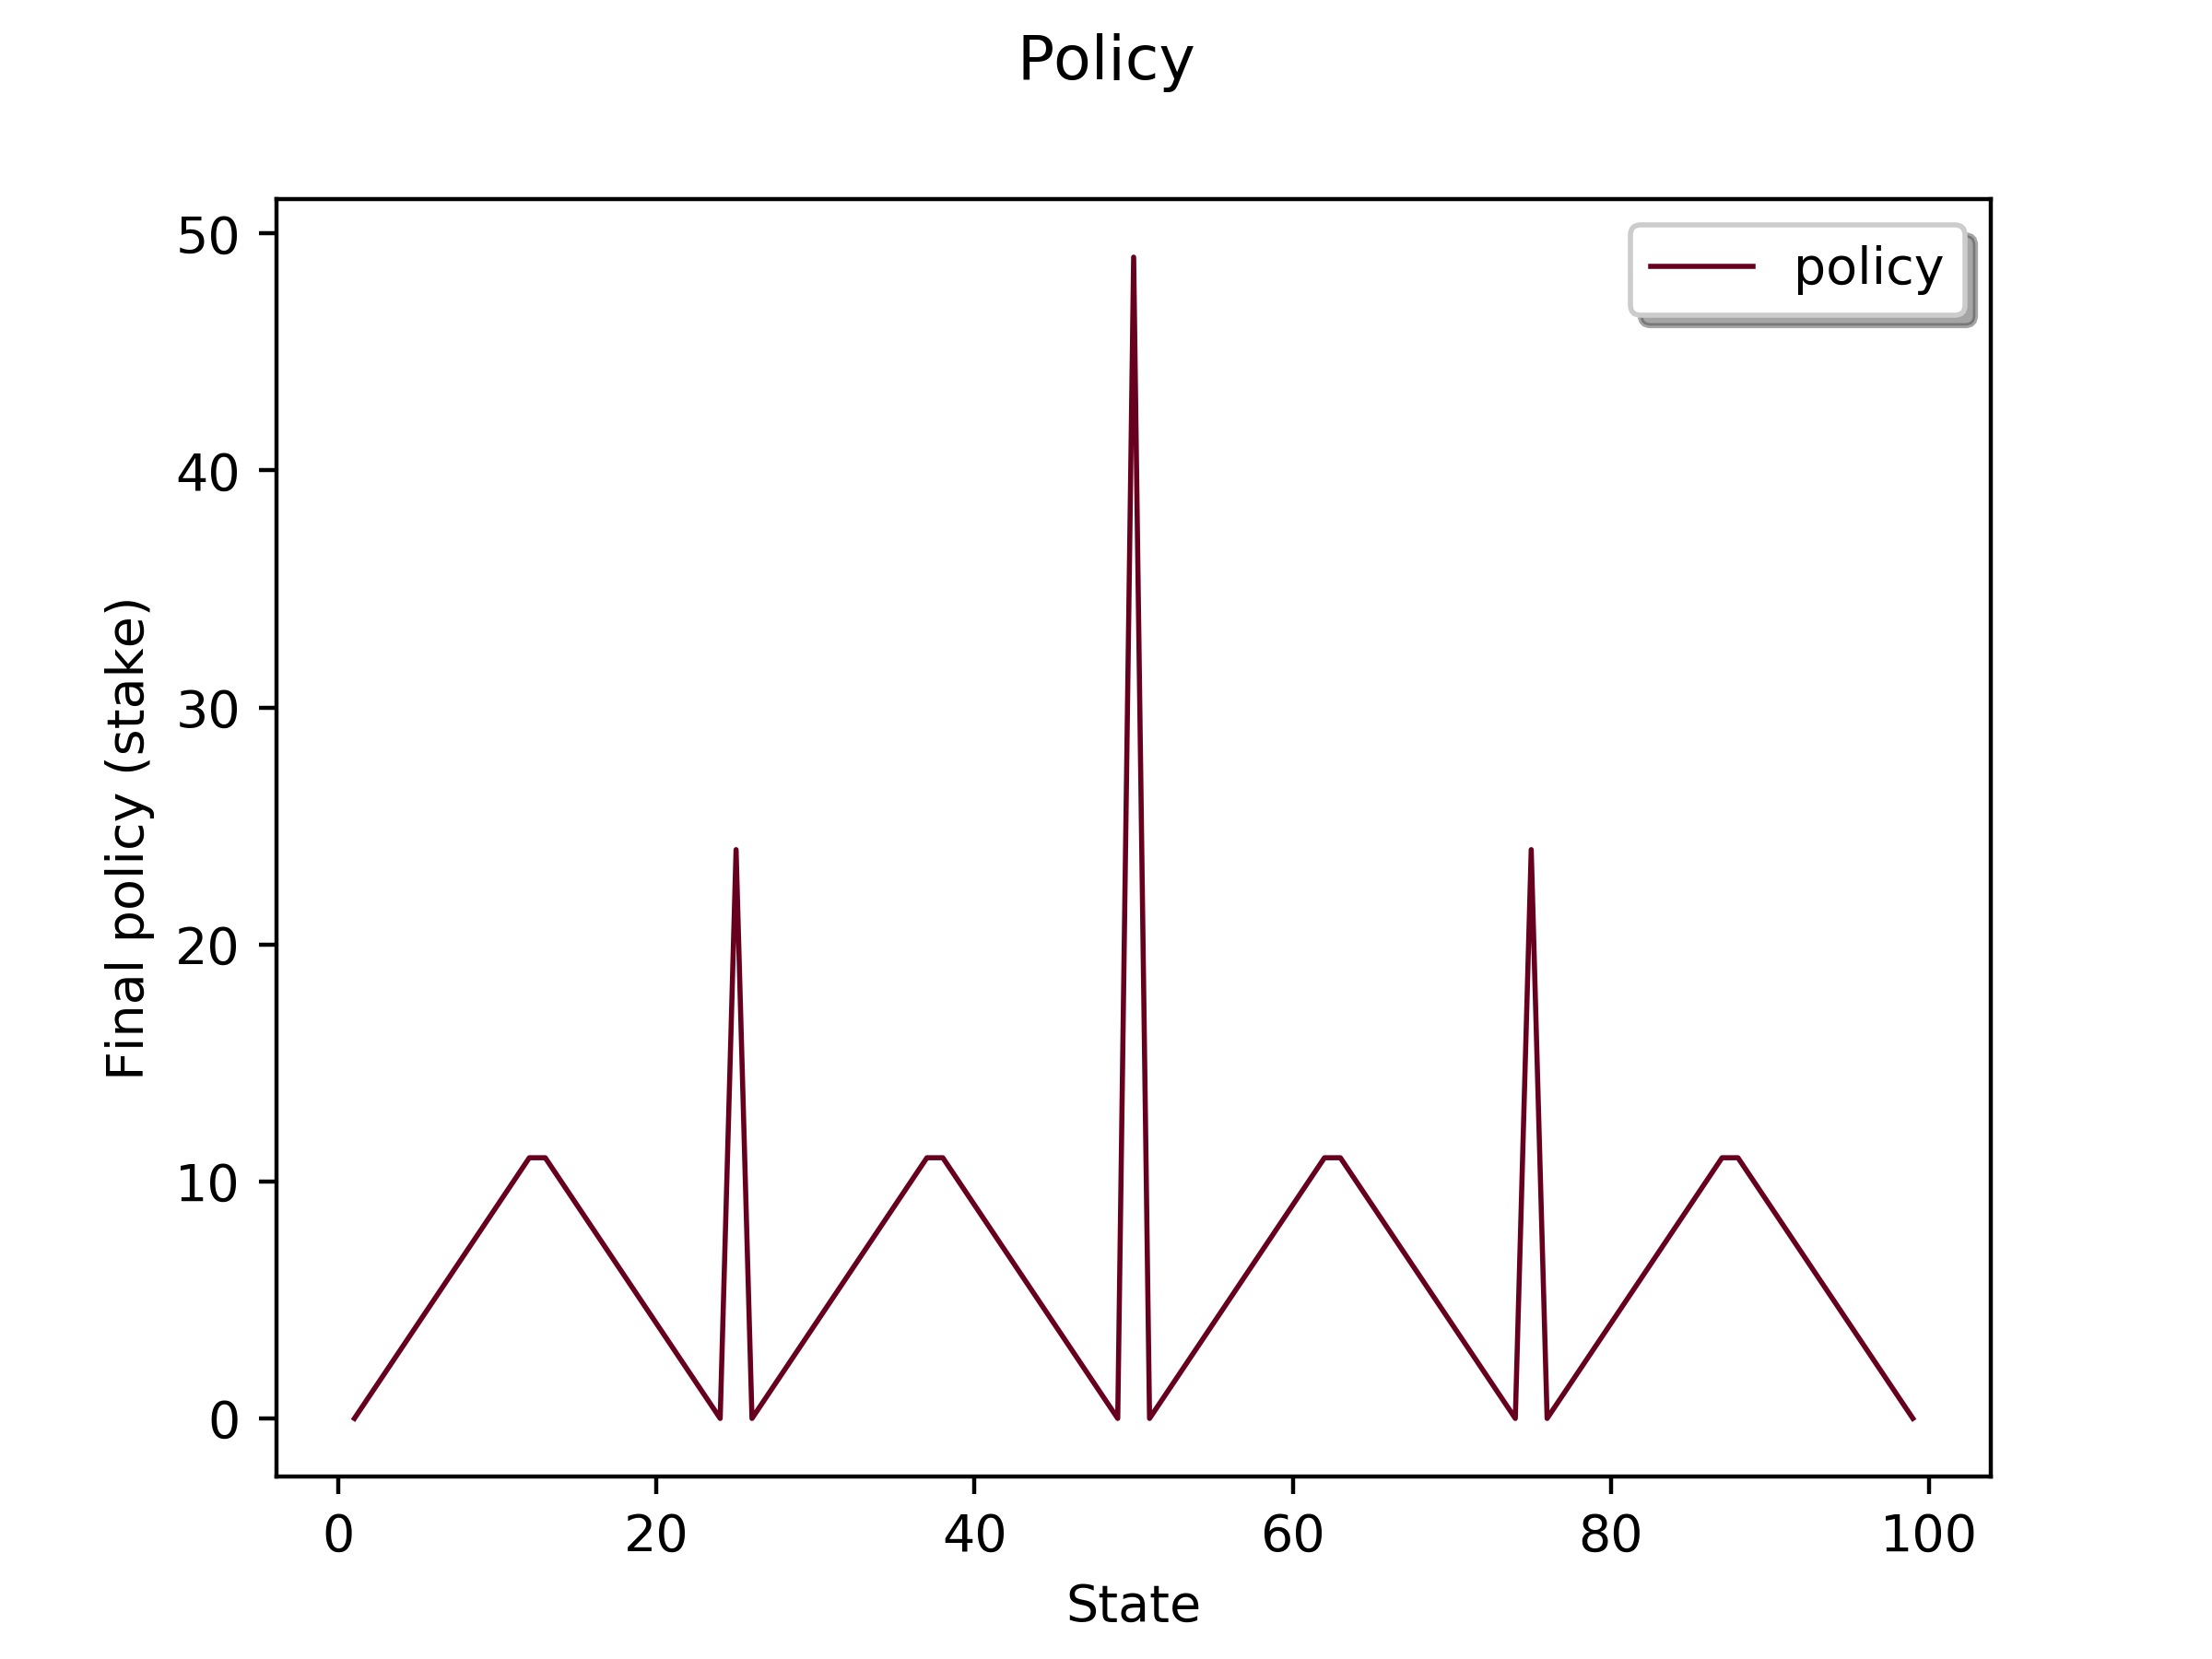
Gambler’s problem with ph = 0.4. Left: Value function found by successive sweeps of value iteration. Right: Final policy.
Asynchronous Dynamic Programming
Generalized Policy Iteration
Efficiency of Dynamic Programming
Monte Carlo Prediction
Monte Carlo Estimation of Action Values
Monte Carlo Control
Monte Carlo Control without Exploring Starts
Off-policy Prediction via Importance Sampling
Incremental Implementation
Off-policy Monte Carlo Control
Discounting-aware Importance Sampling
Per-decision Importance Sampling
TD Prediction
Advantages of TD Prediction Methods
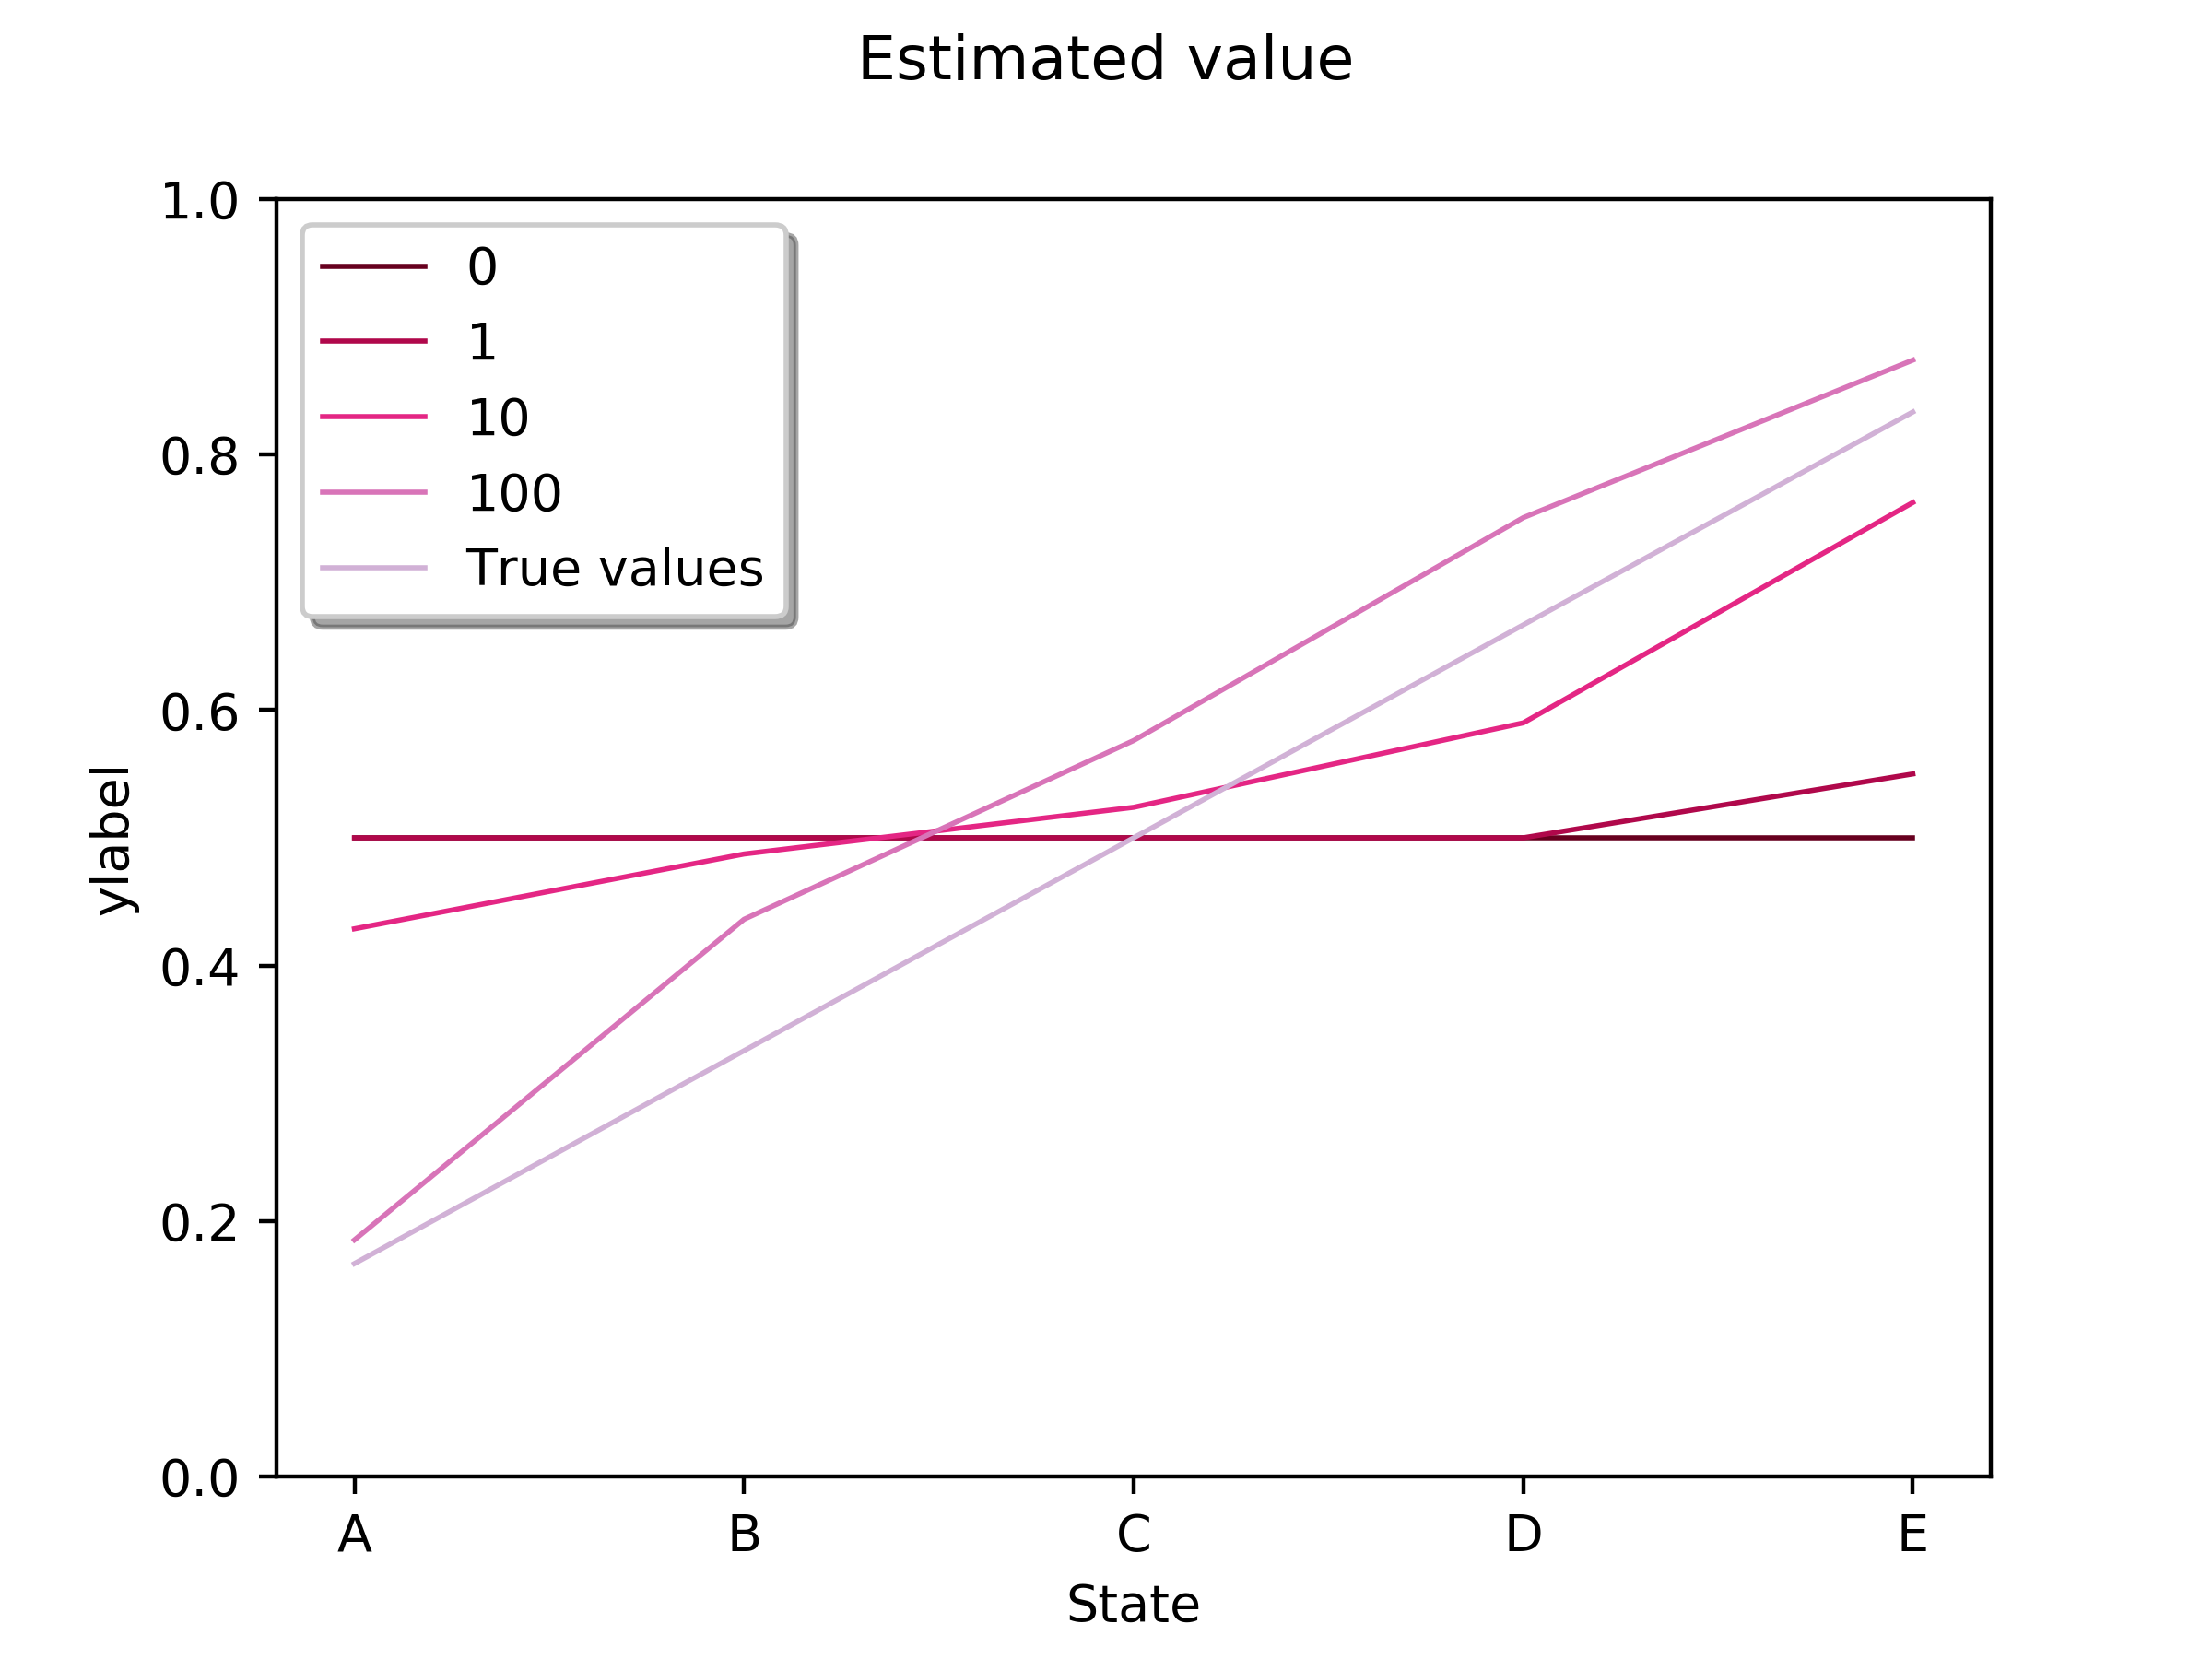
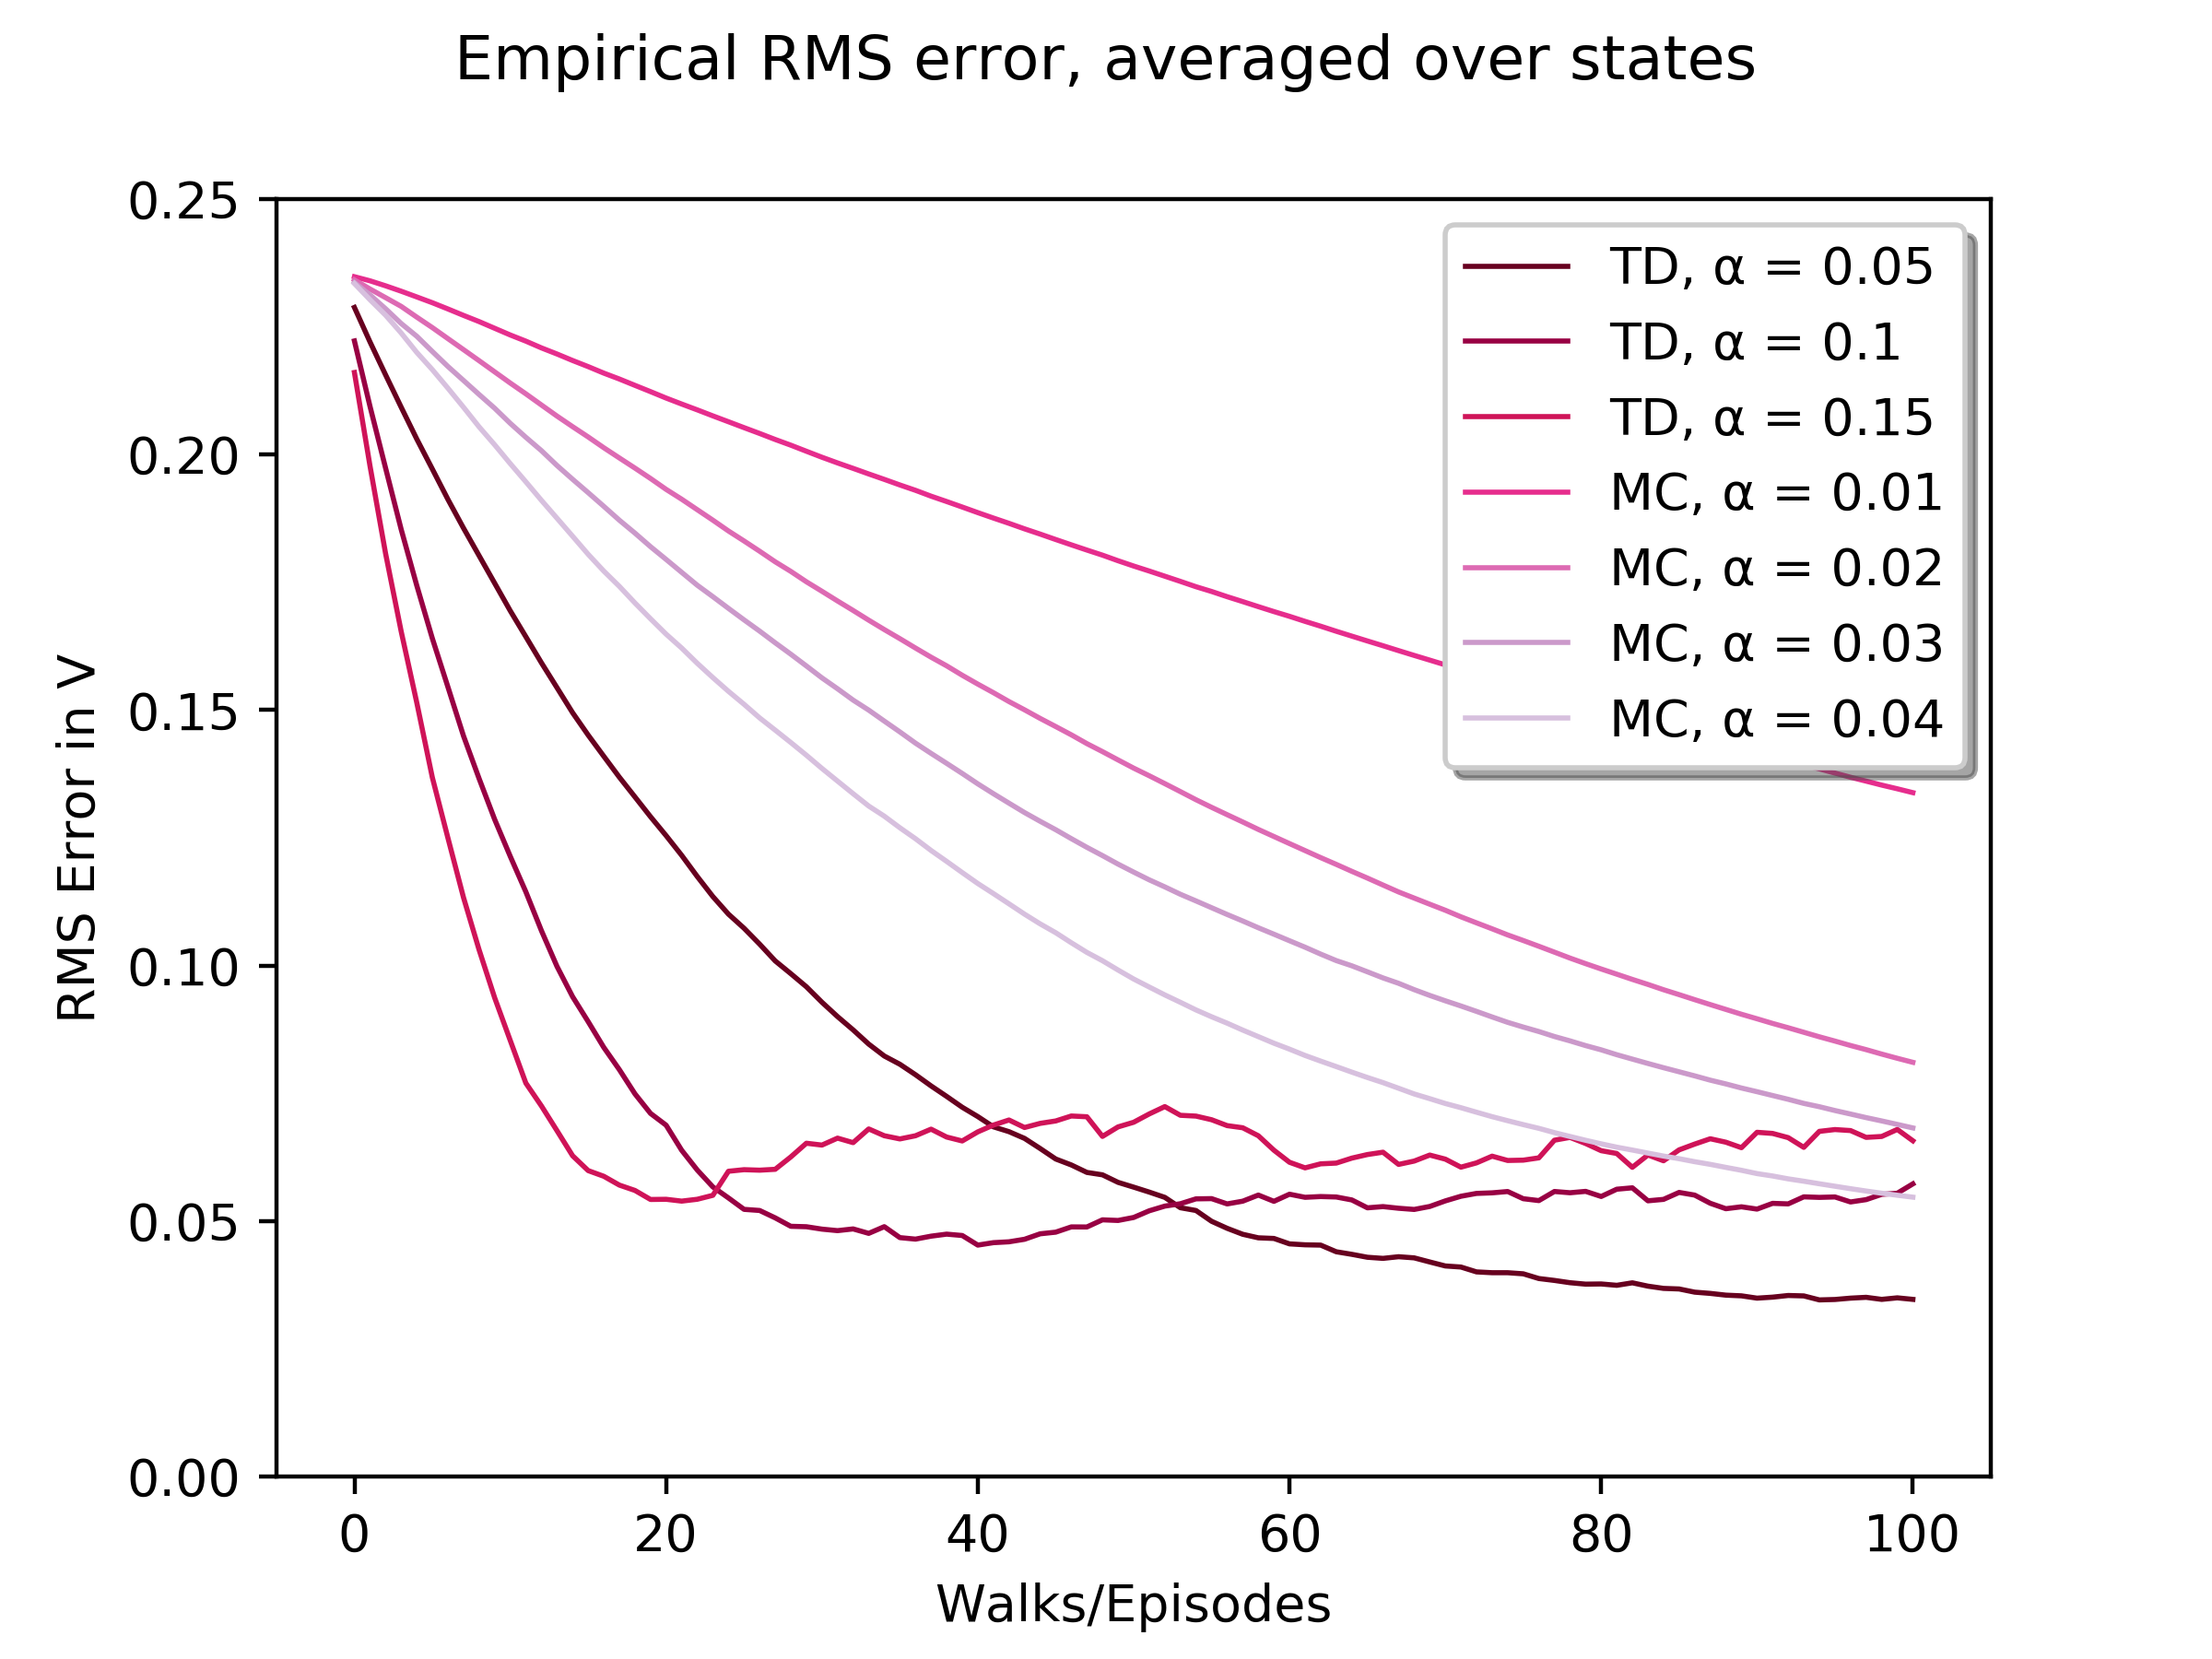
Left: values learned after various numbers of episodes on a single run of TD(0). Right: learning curves for the two methods for various values of α
Optimality of TD(0)
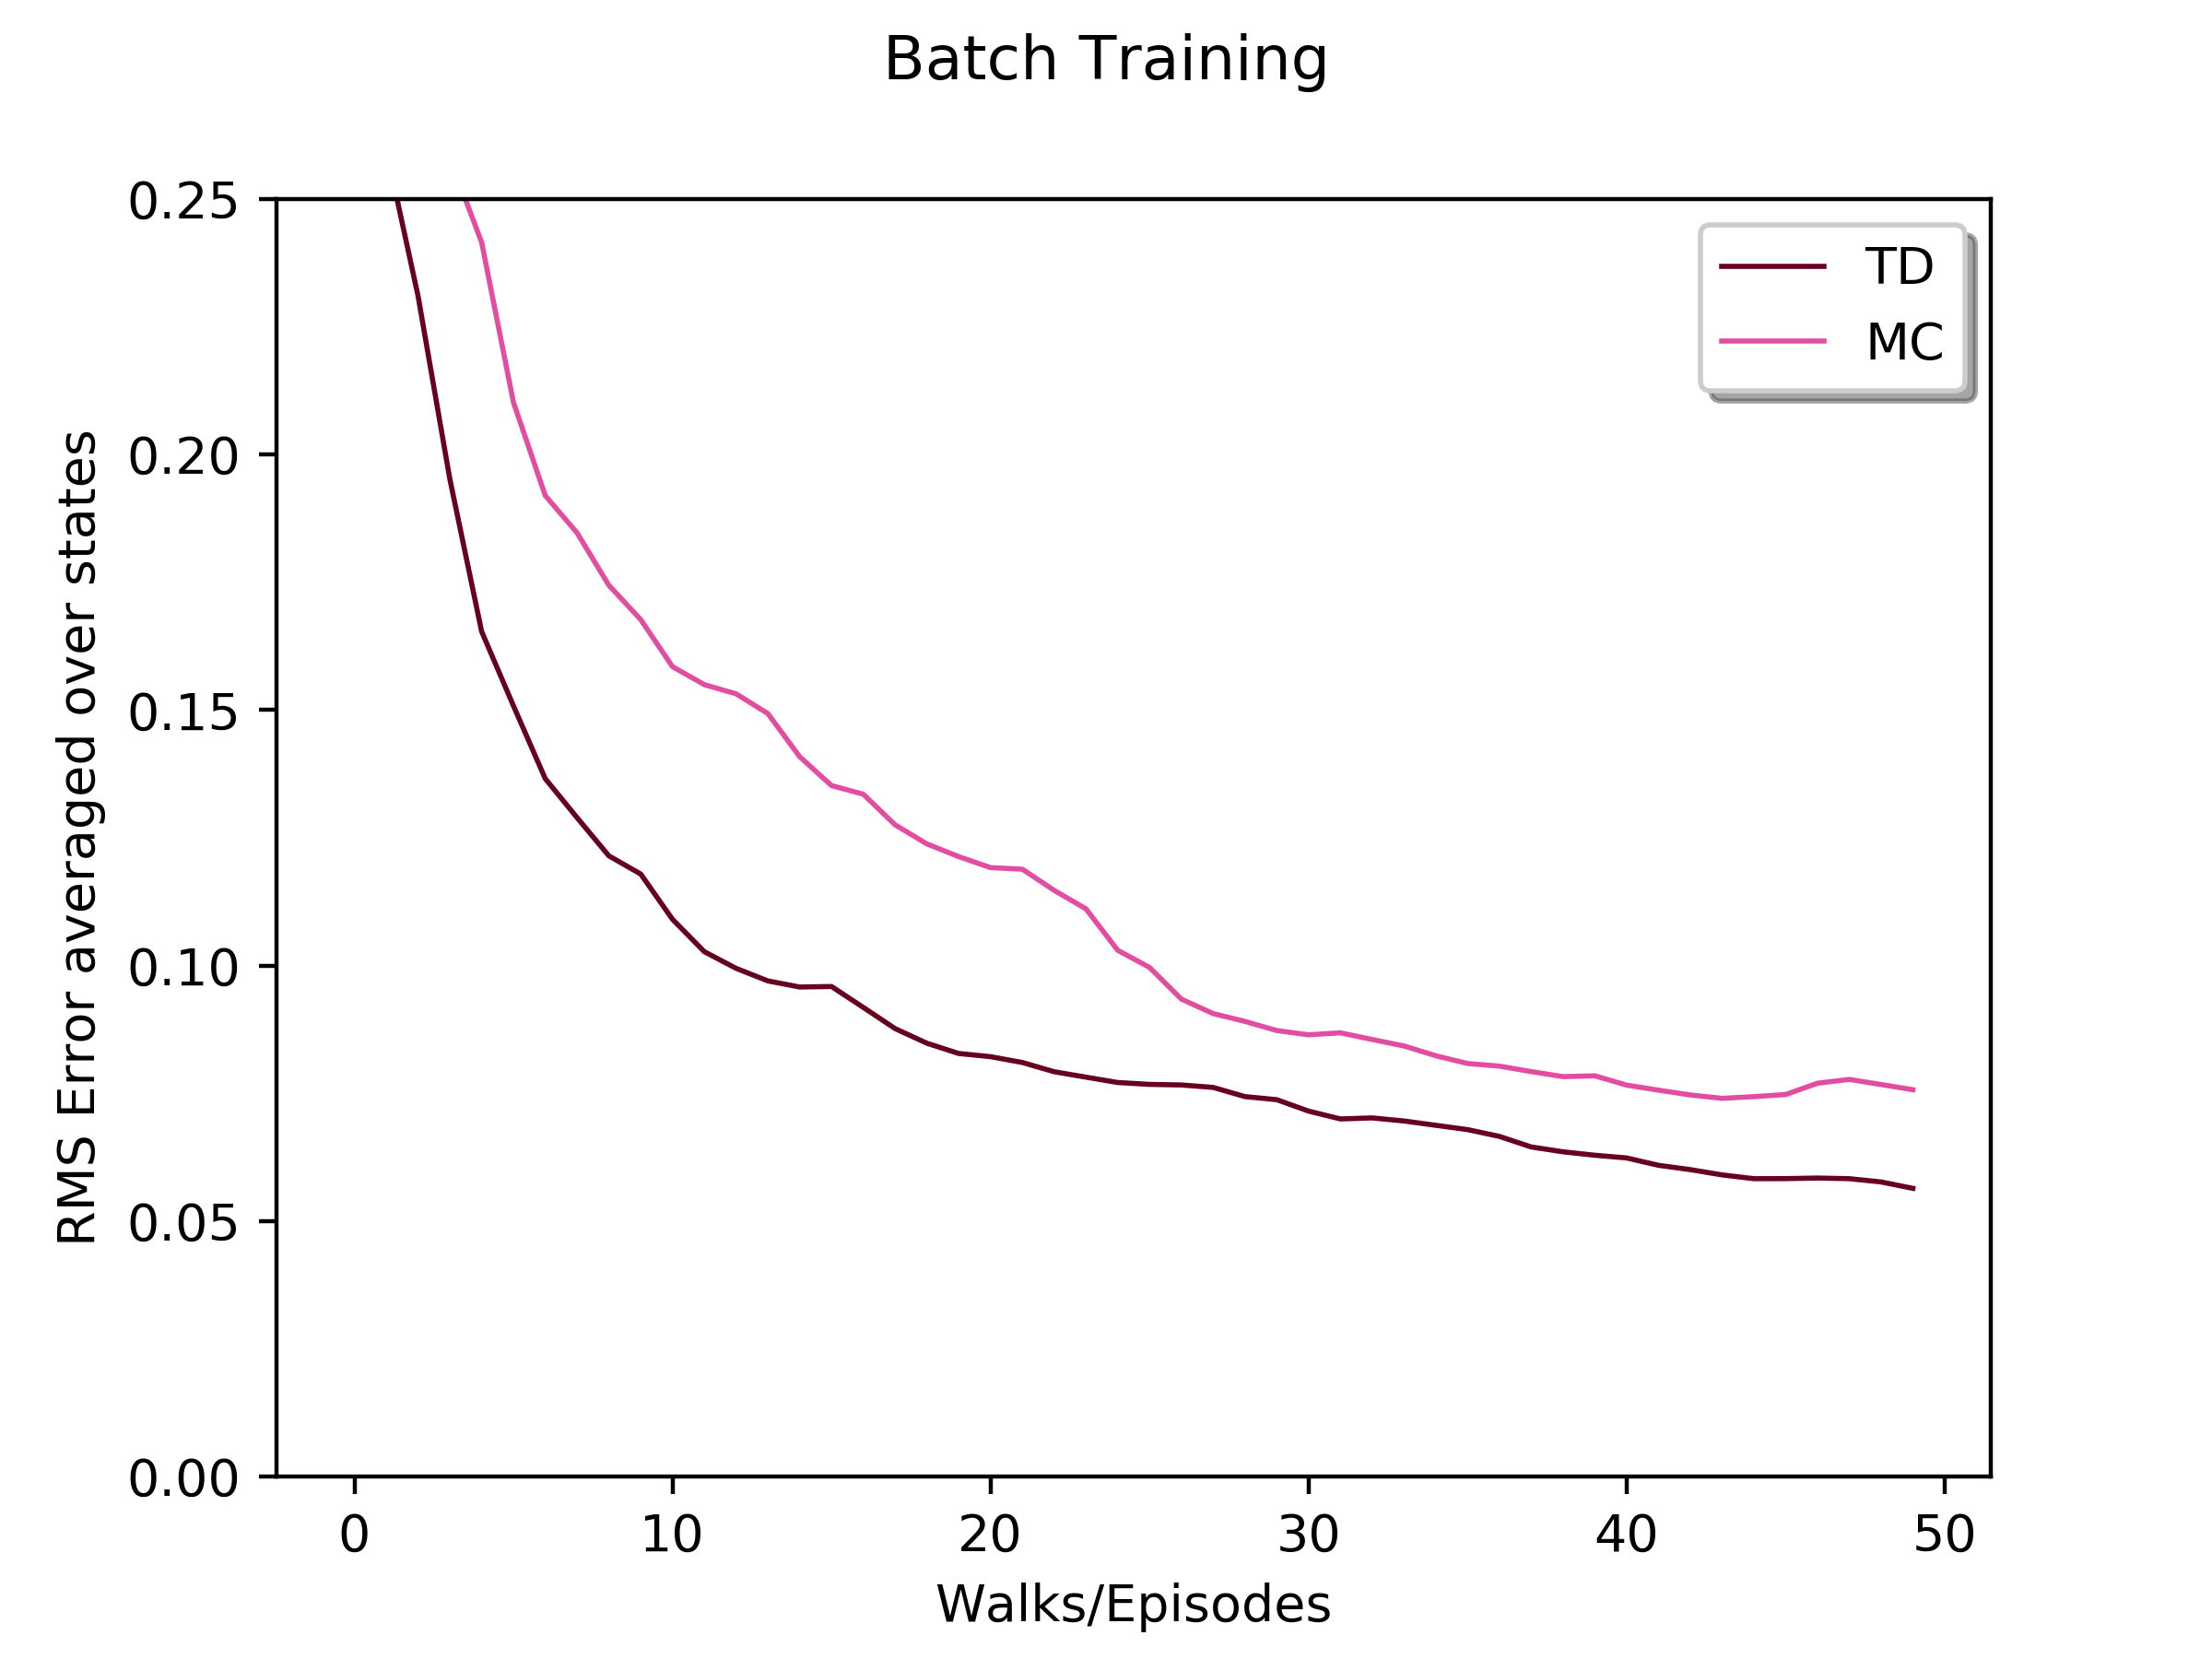
Sarsa: On-policy TD Control
Q-learning: Off-policy TD Control
Expected Sarsa
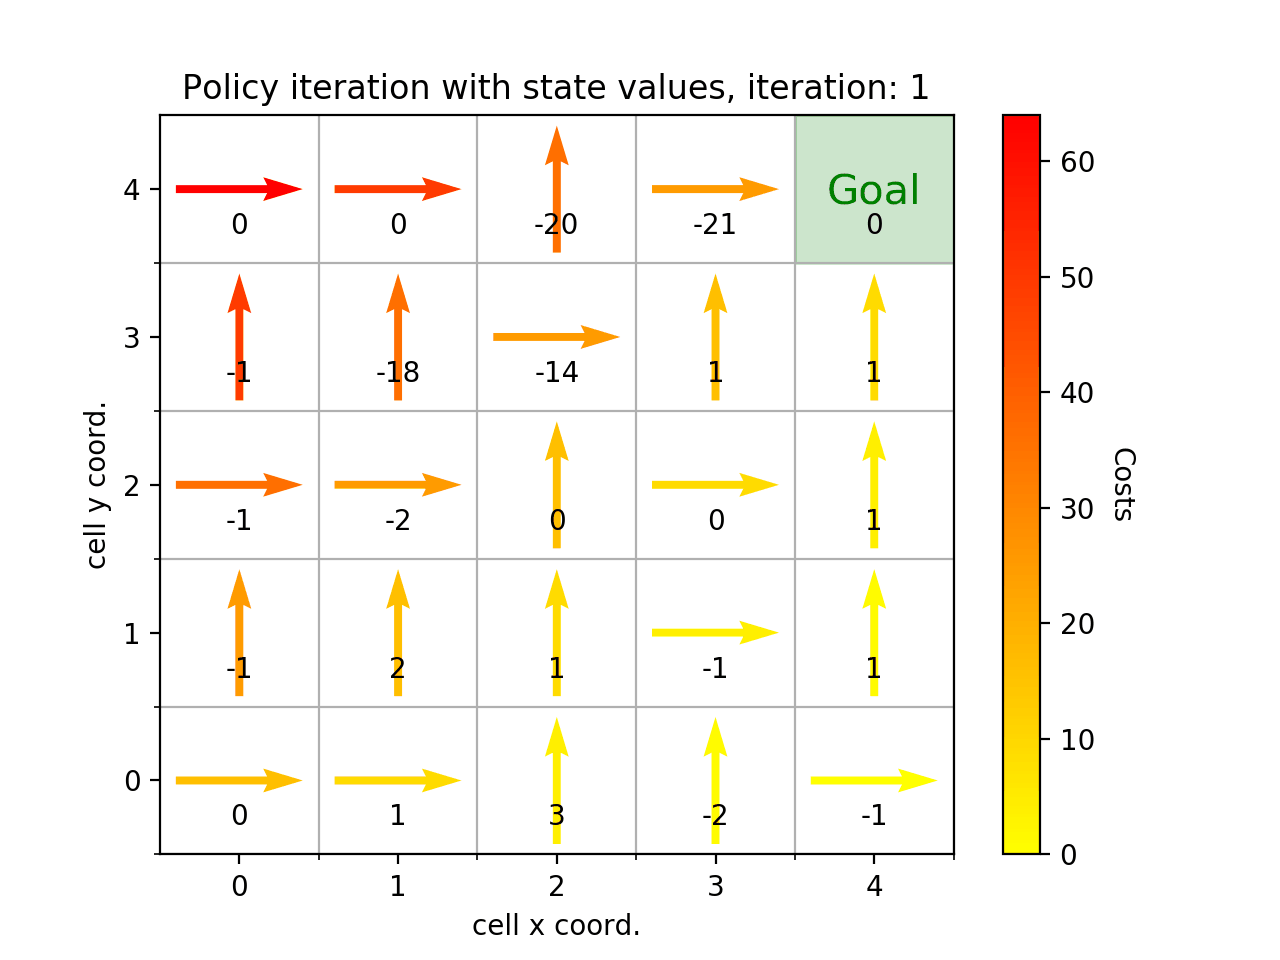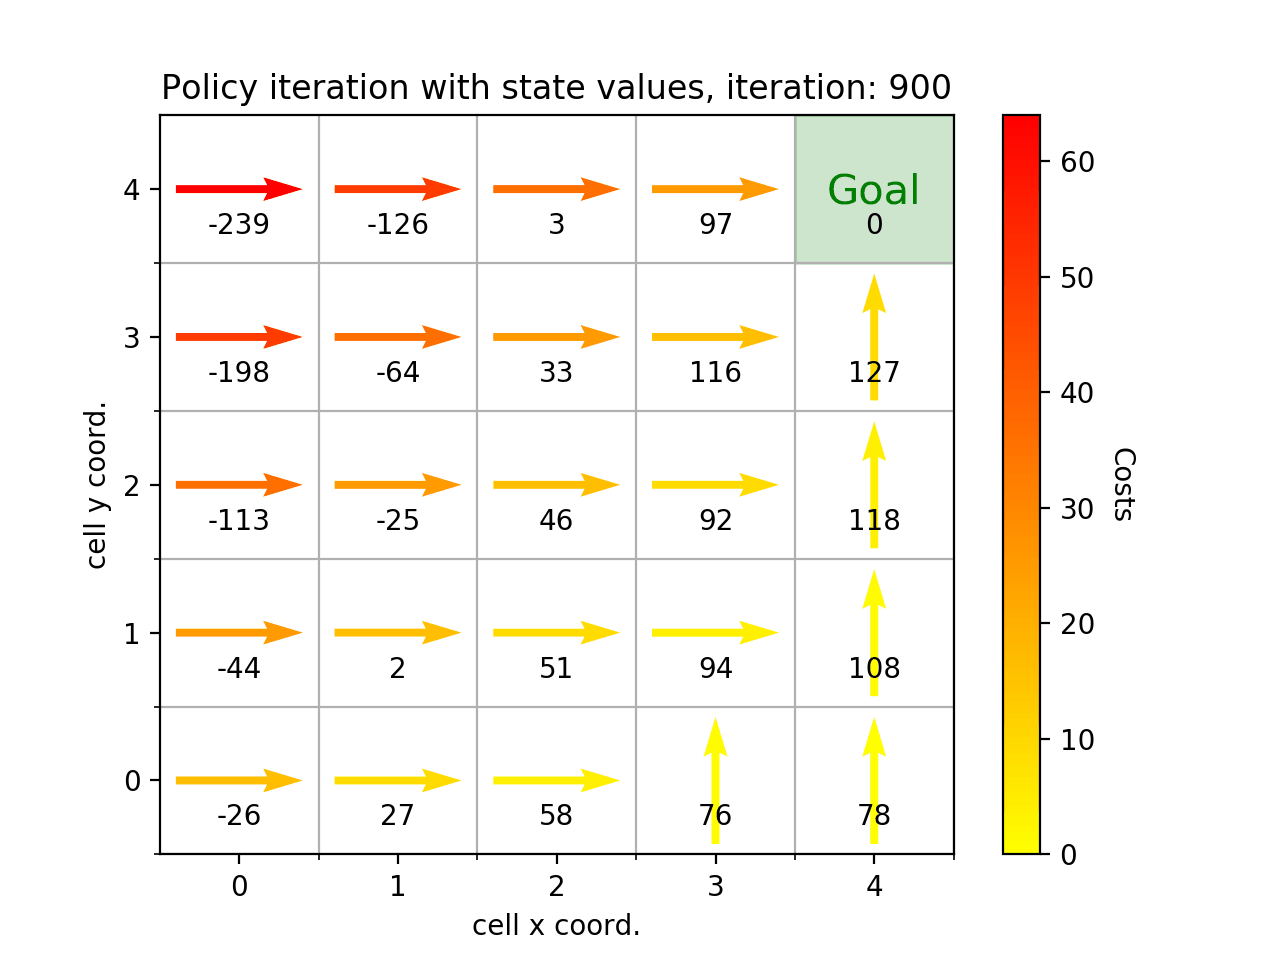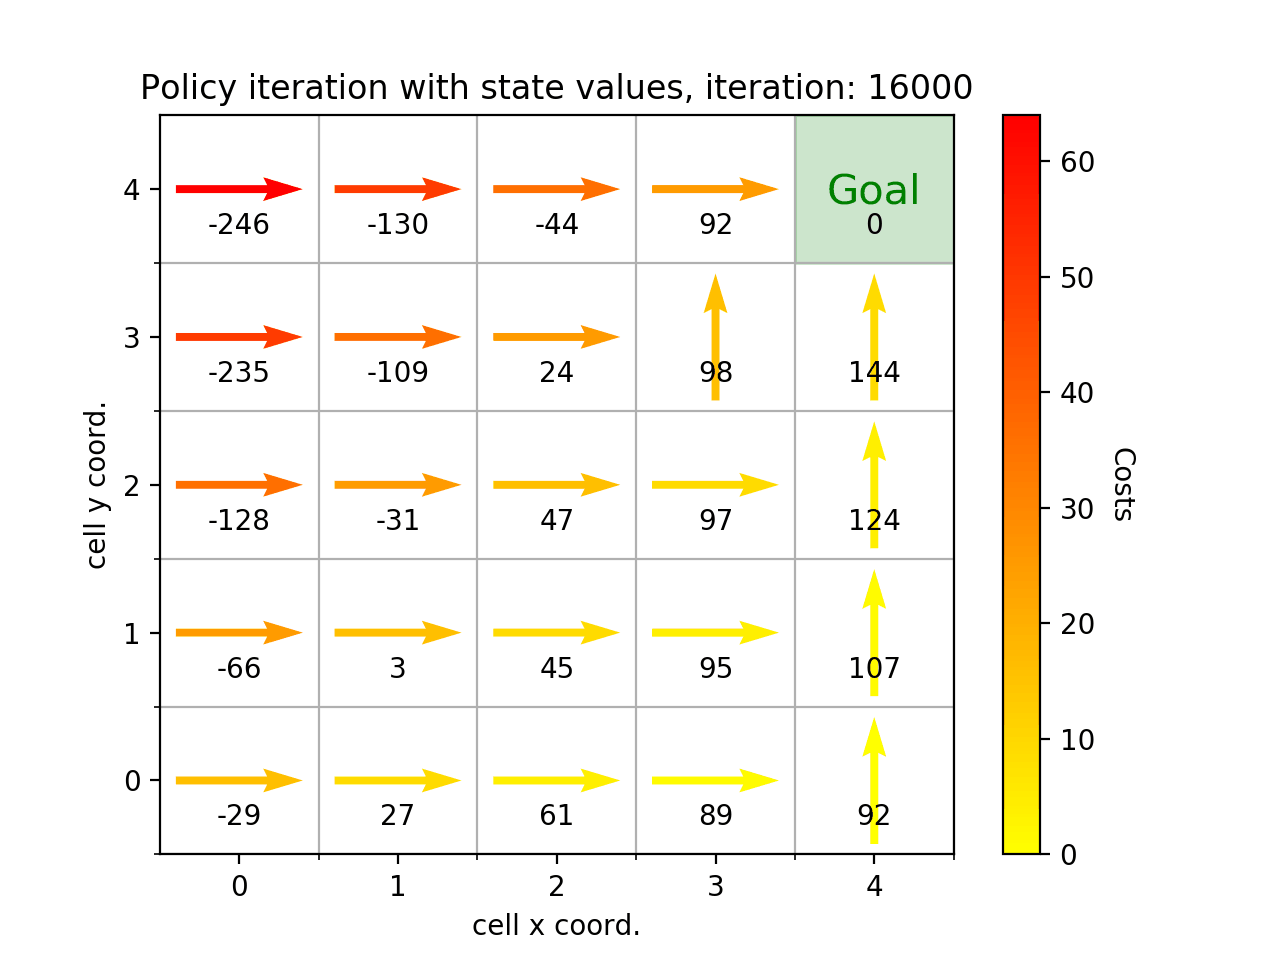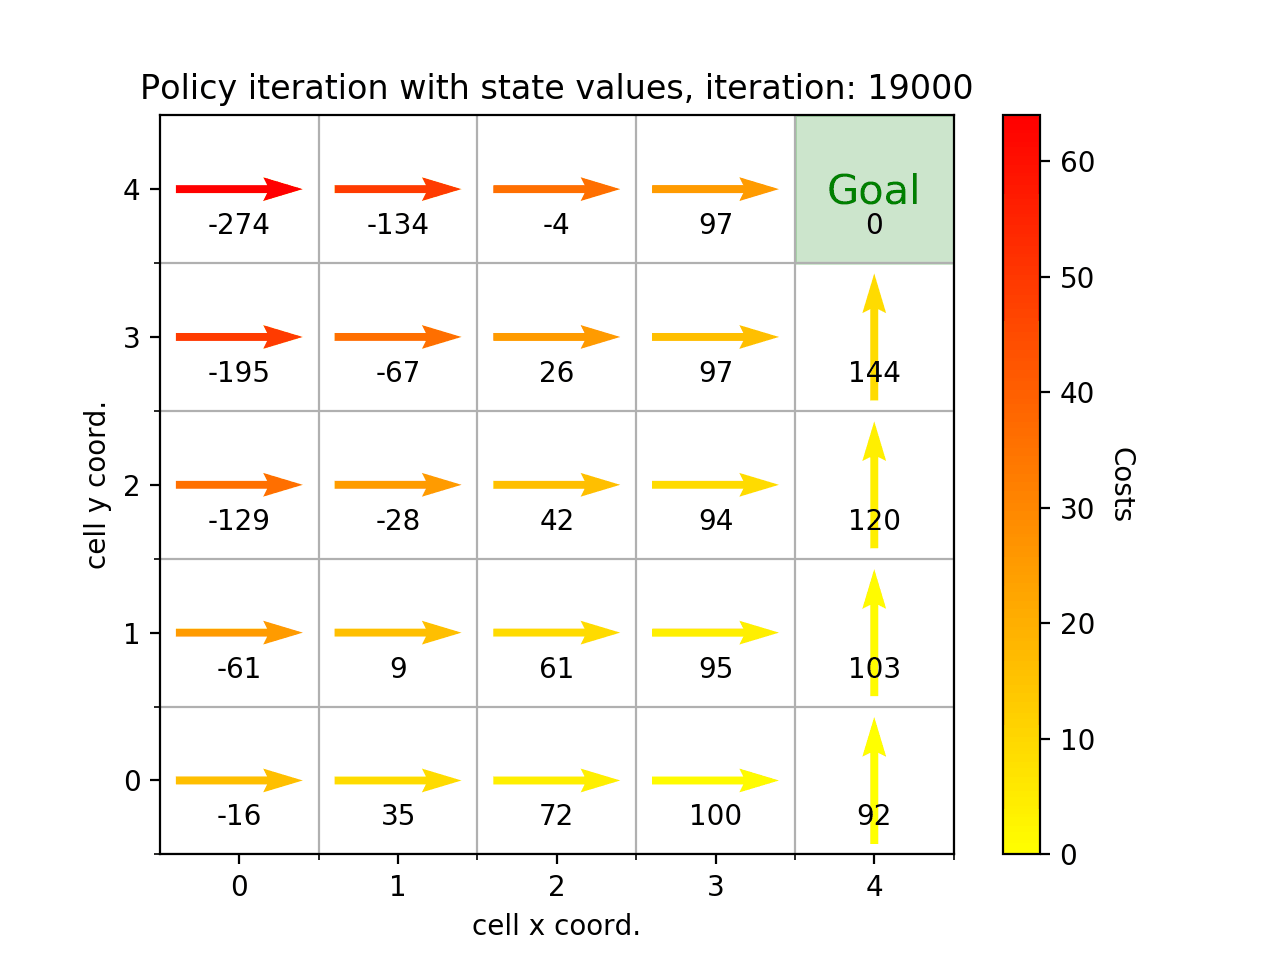
Sarsa on my grid-world.
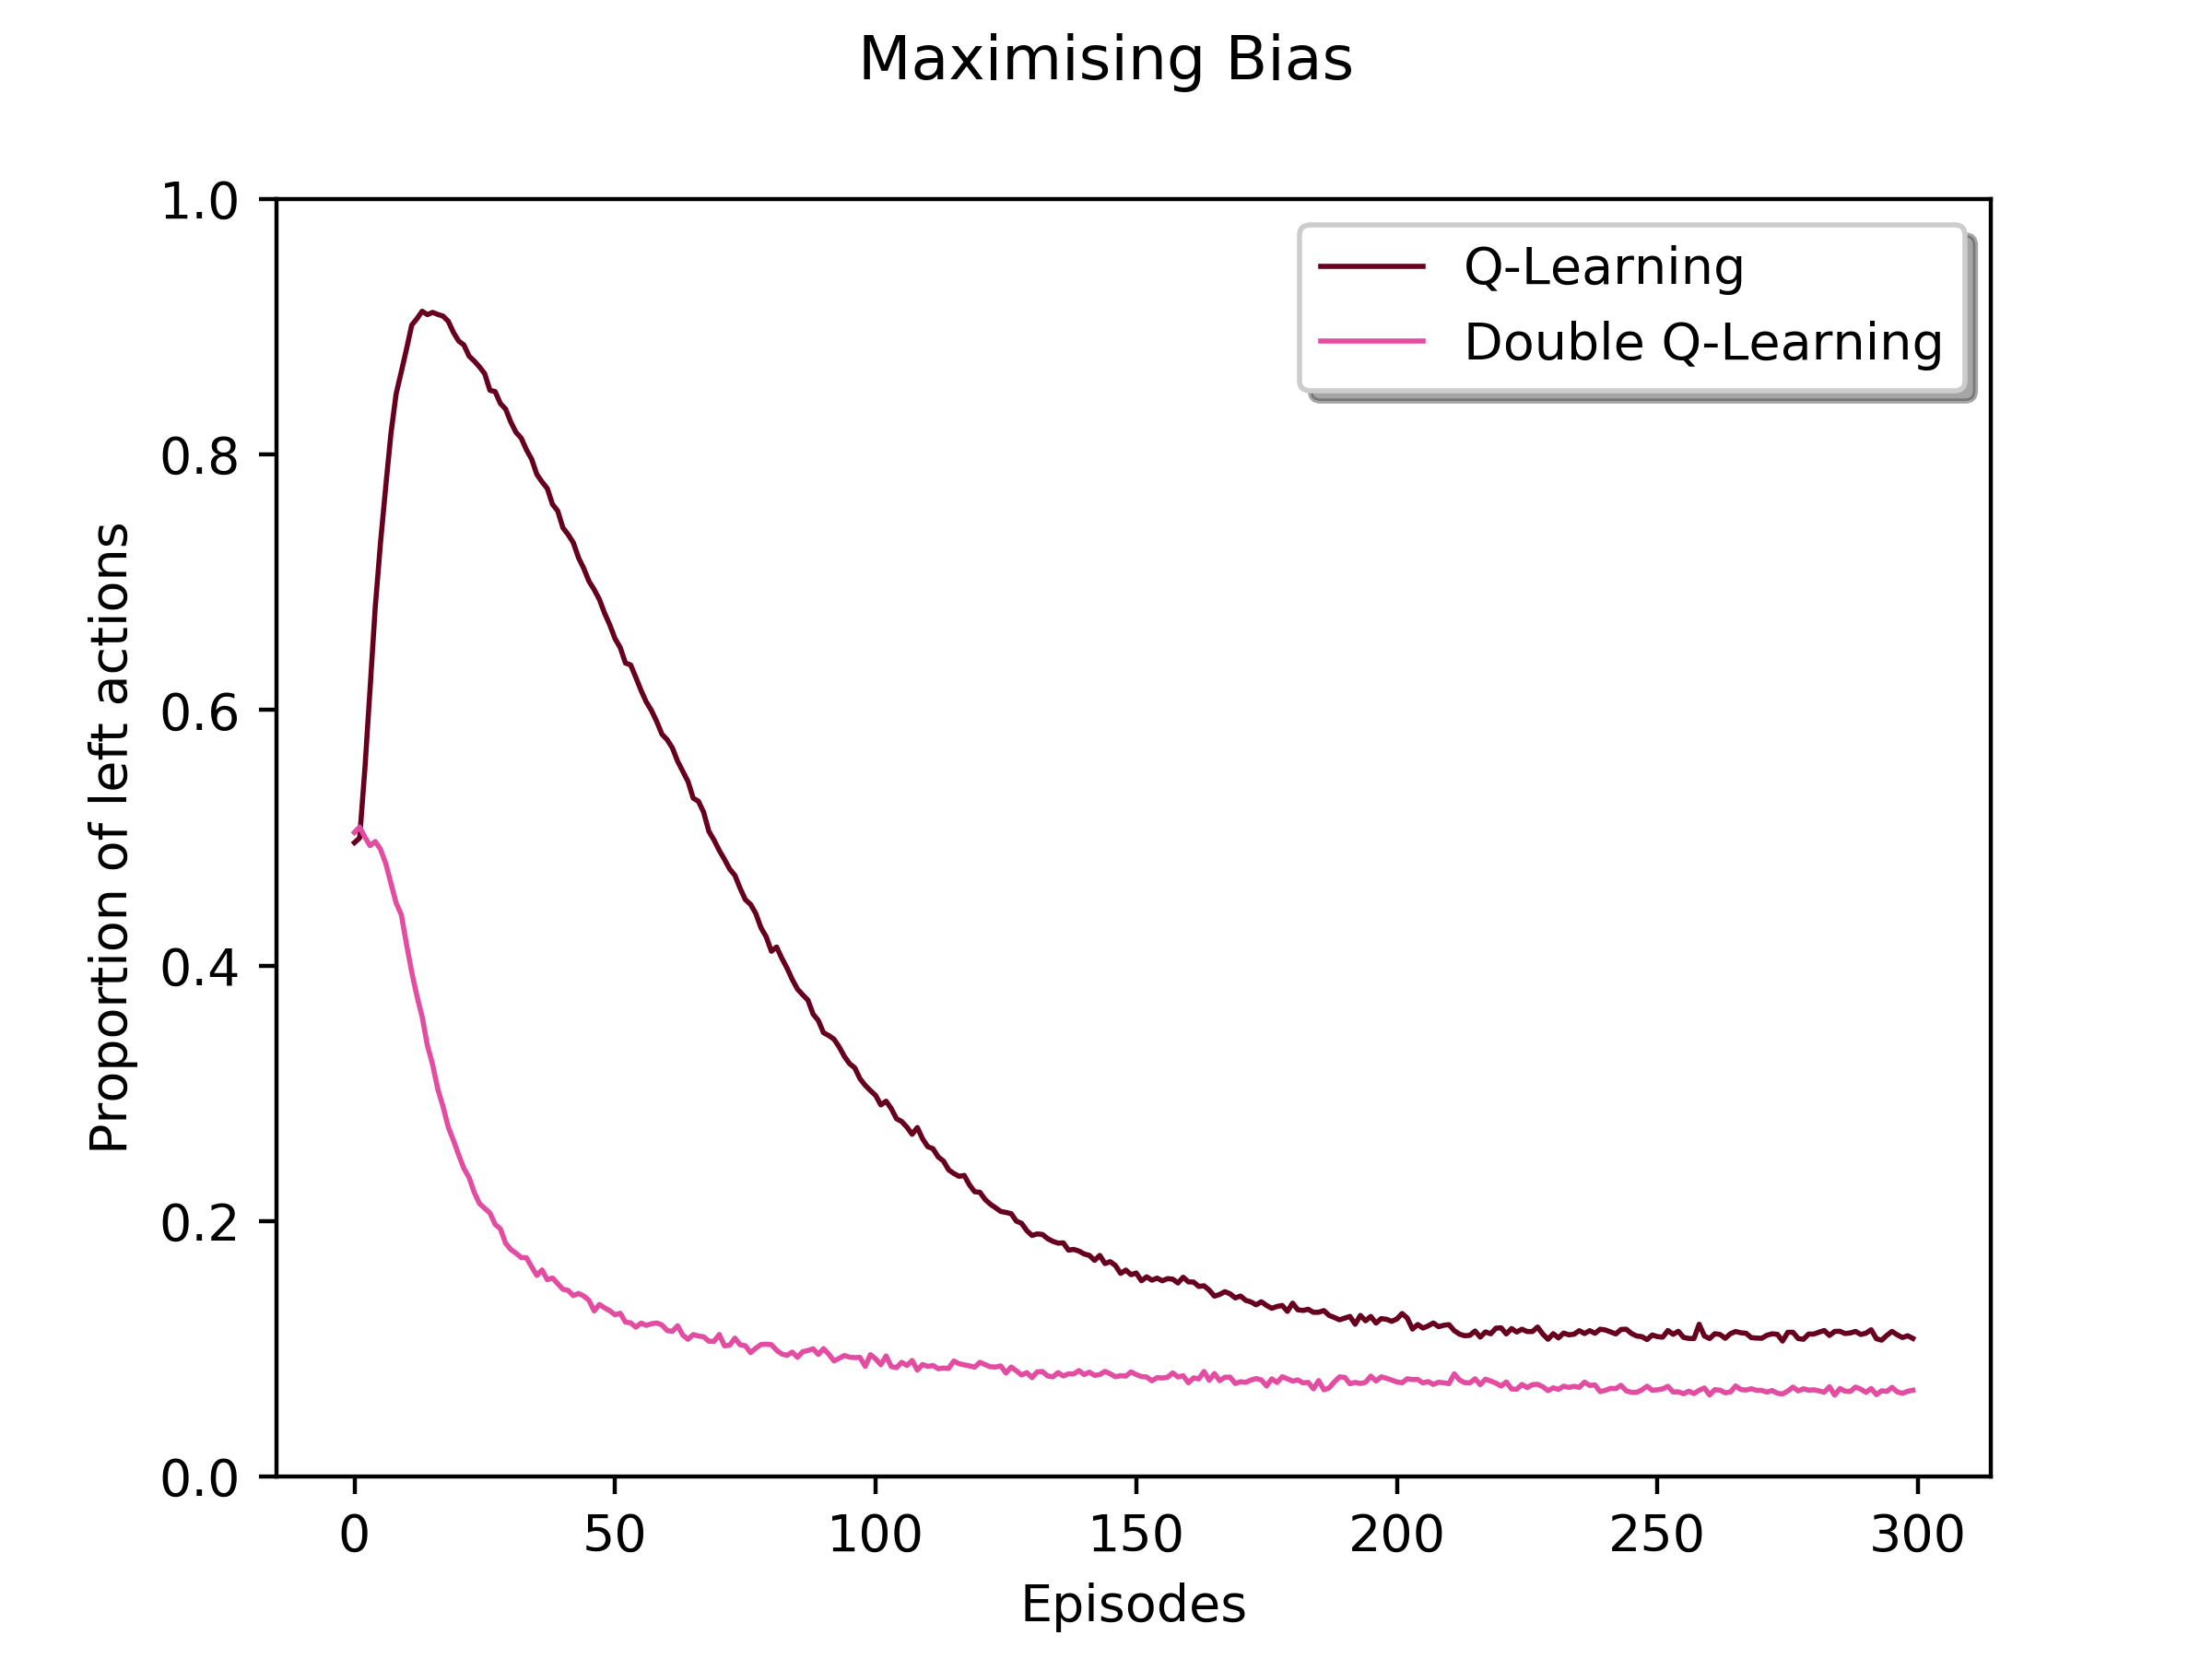
Maximization Bias and Double Learning
Games, Afterstates, and Other Special Cases
n-step TD Prediction
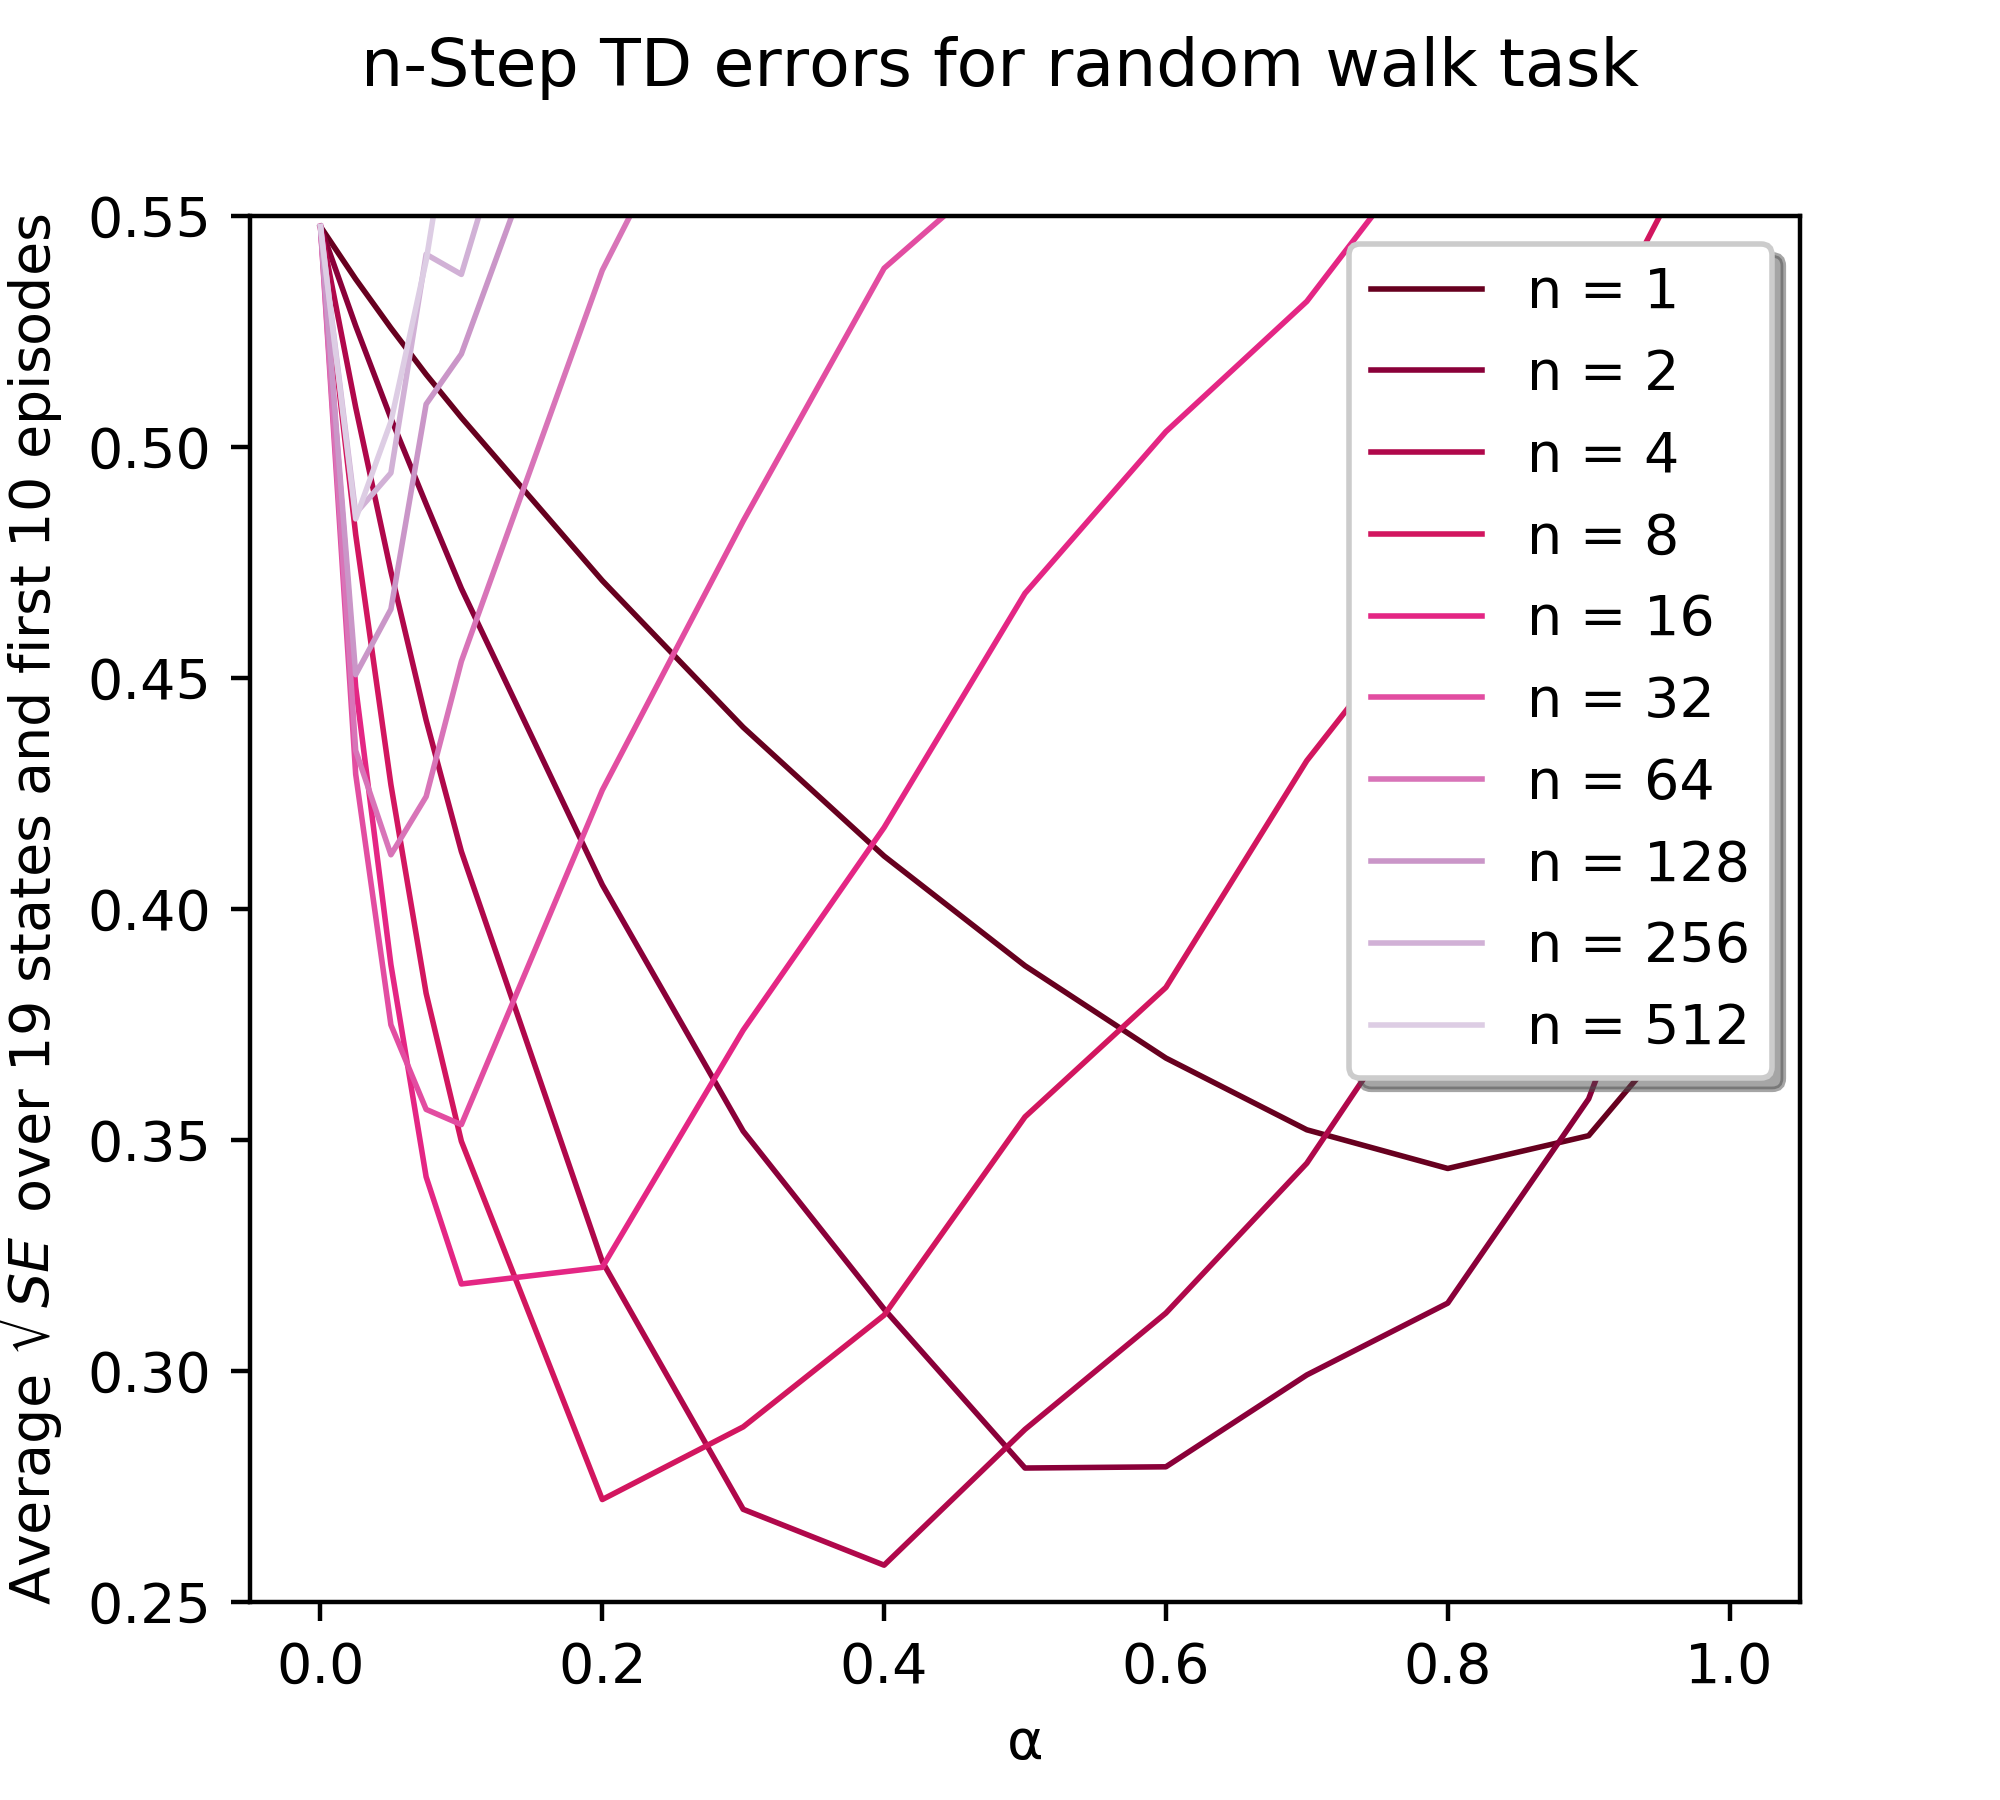
n-step Sarsa
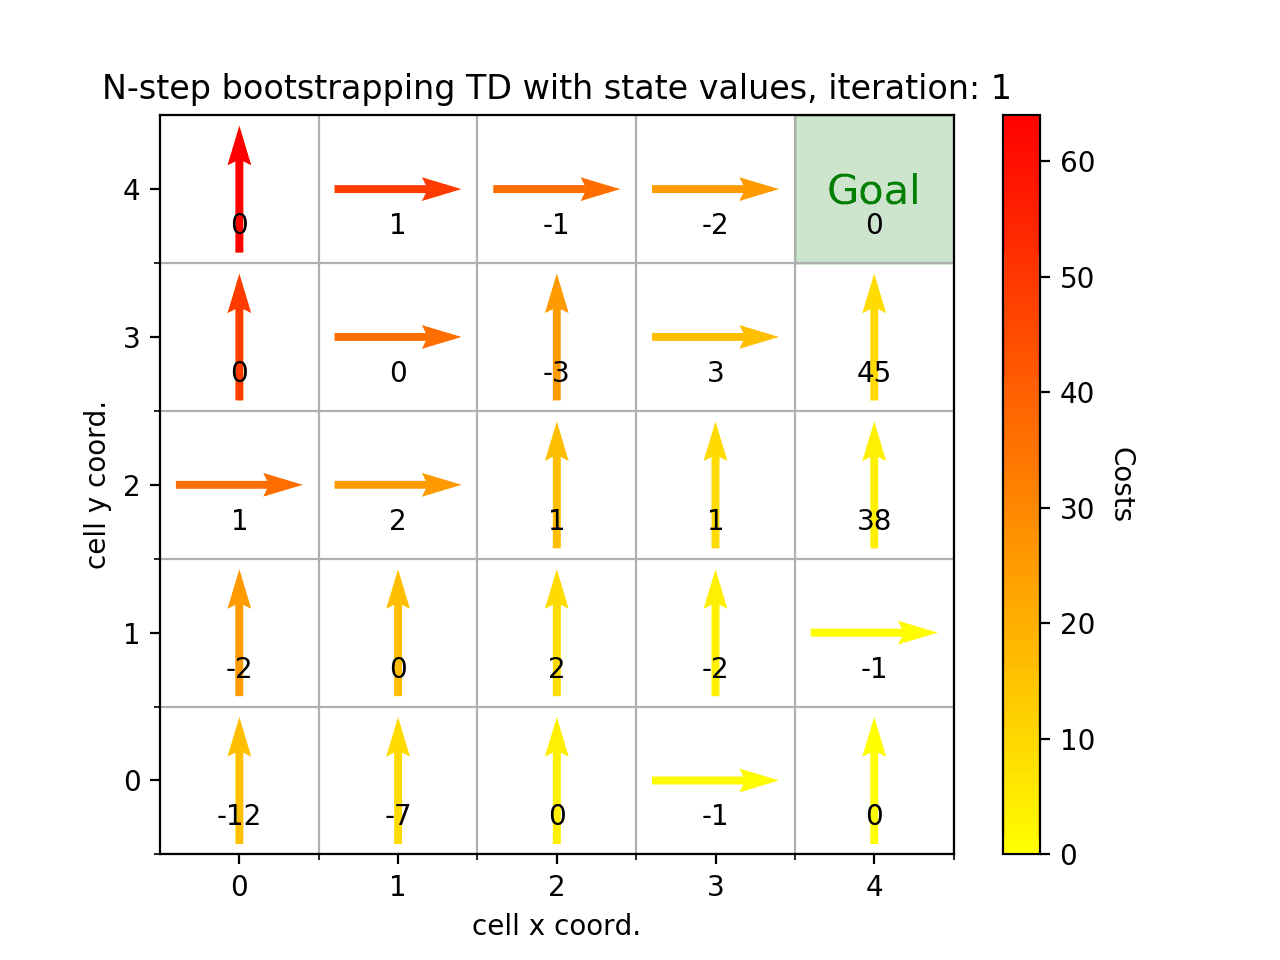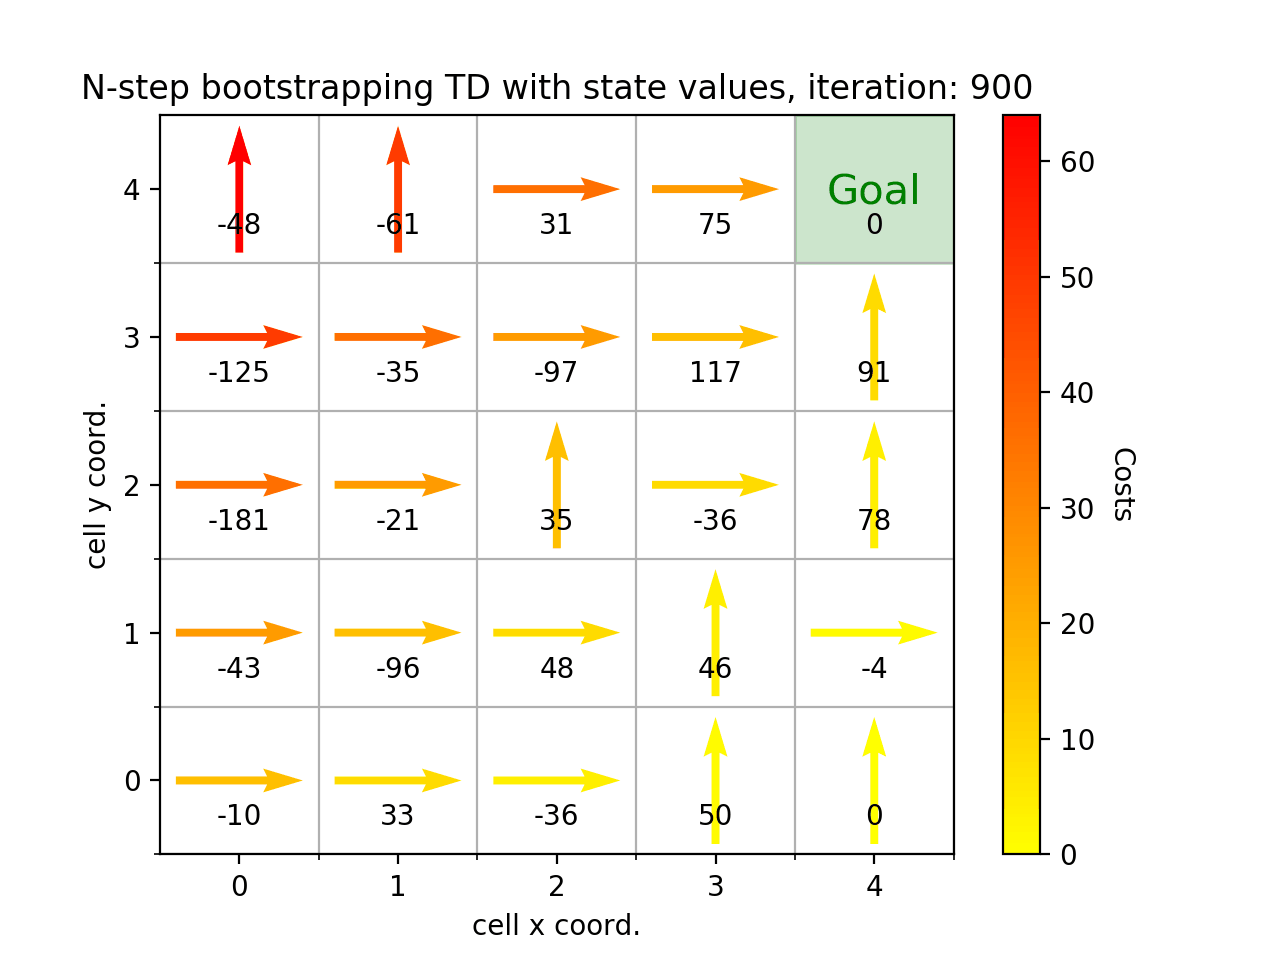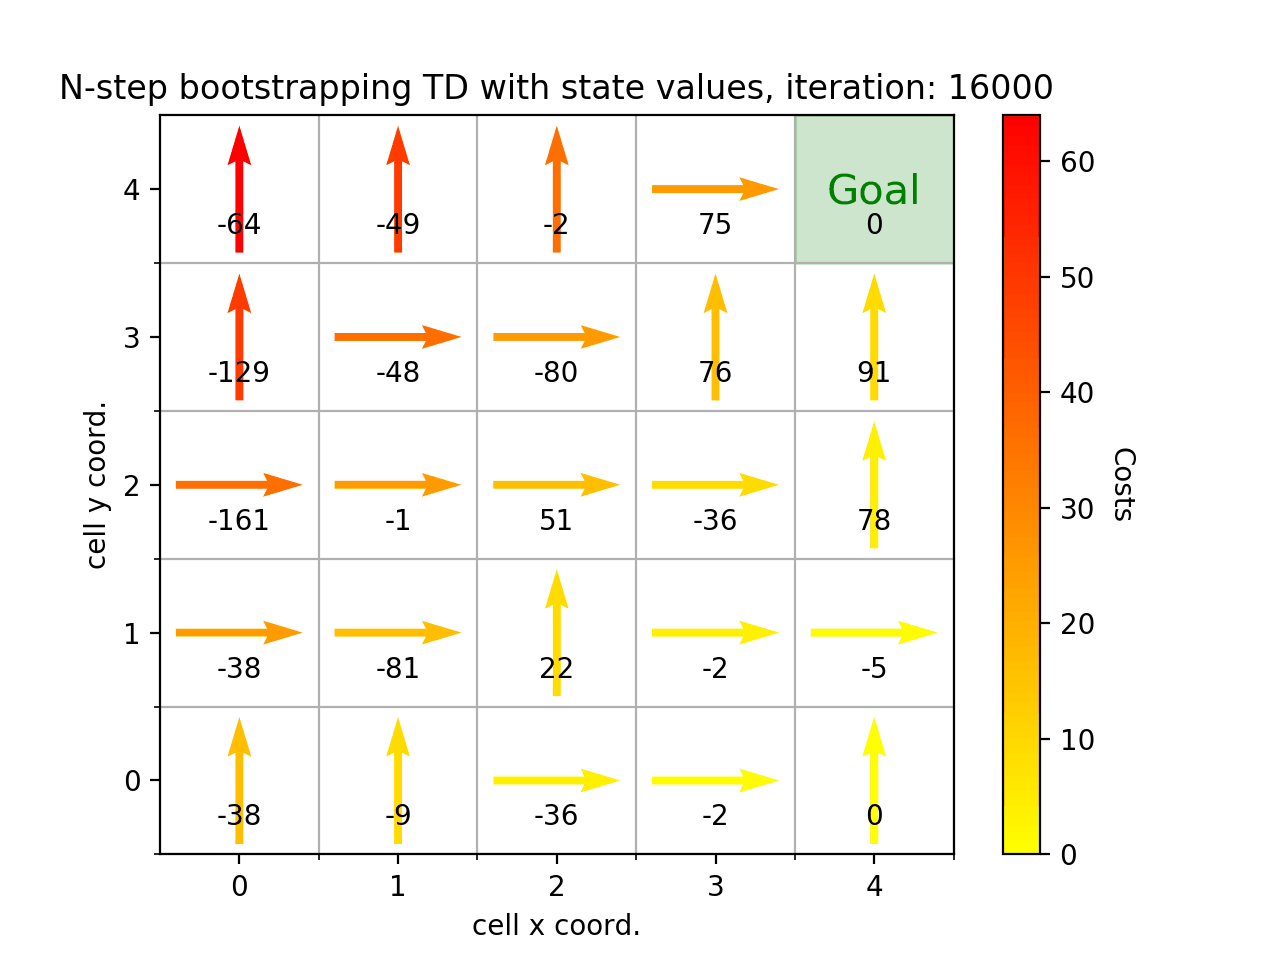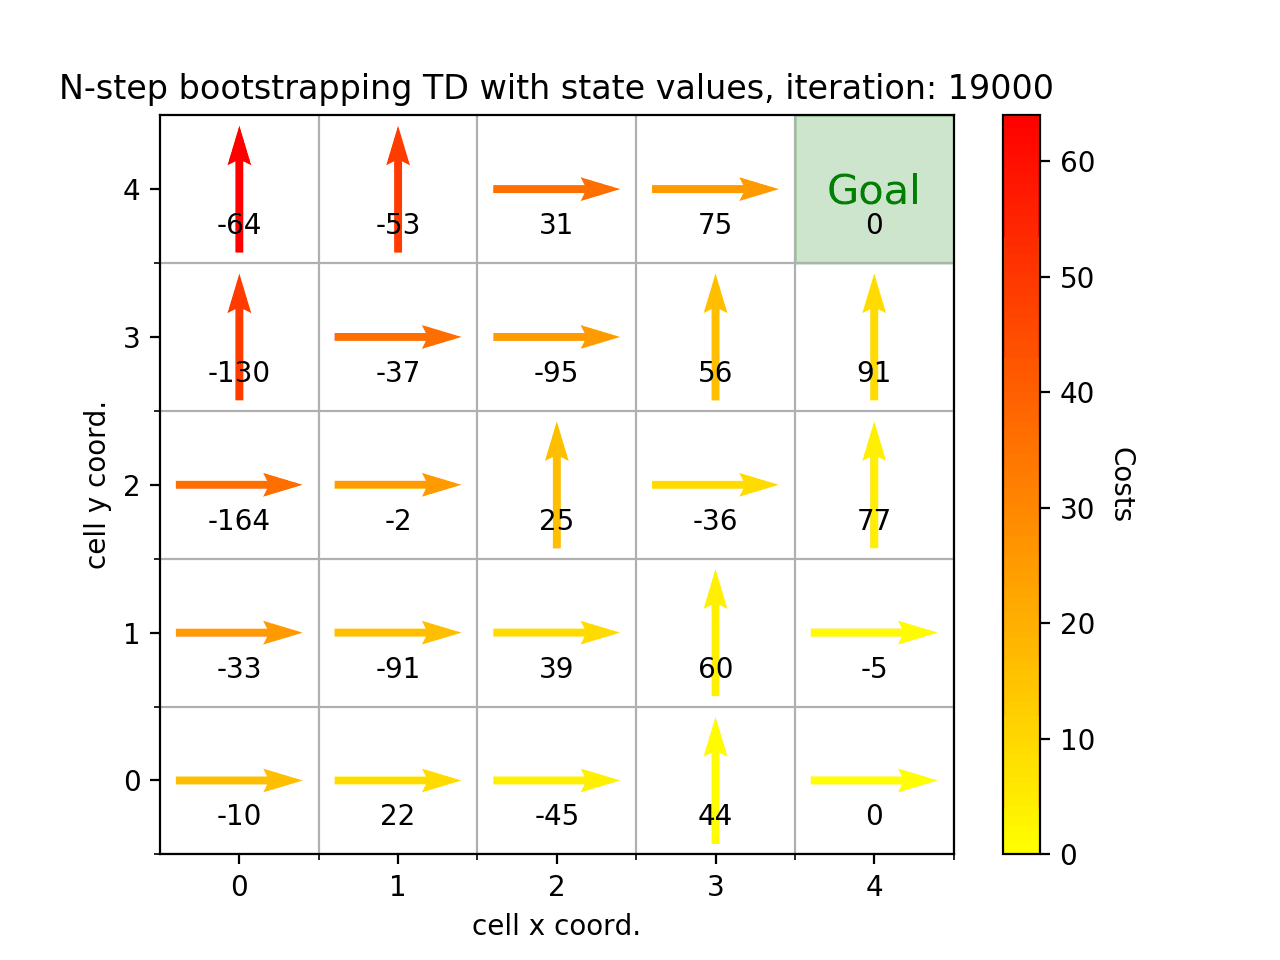
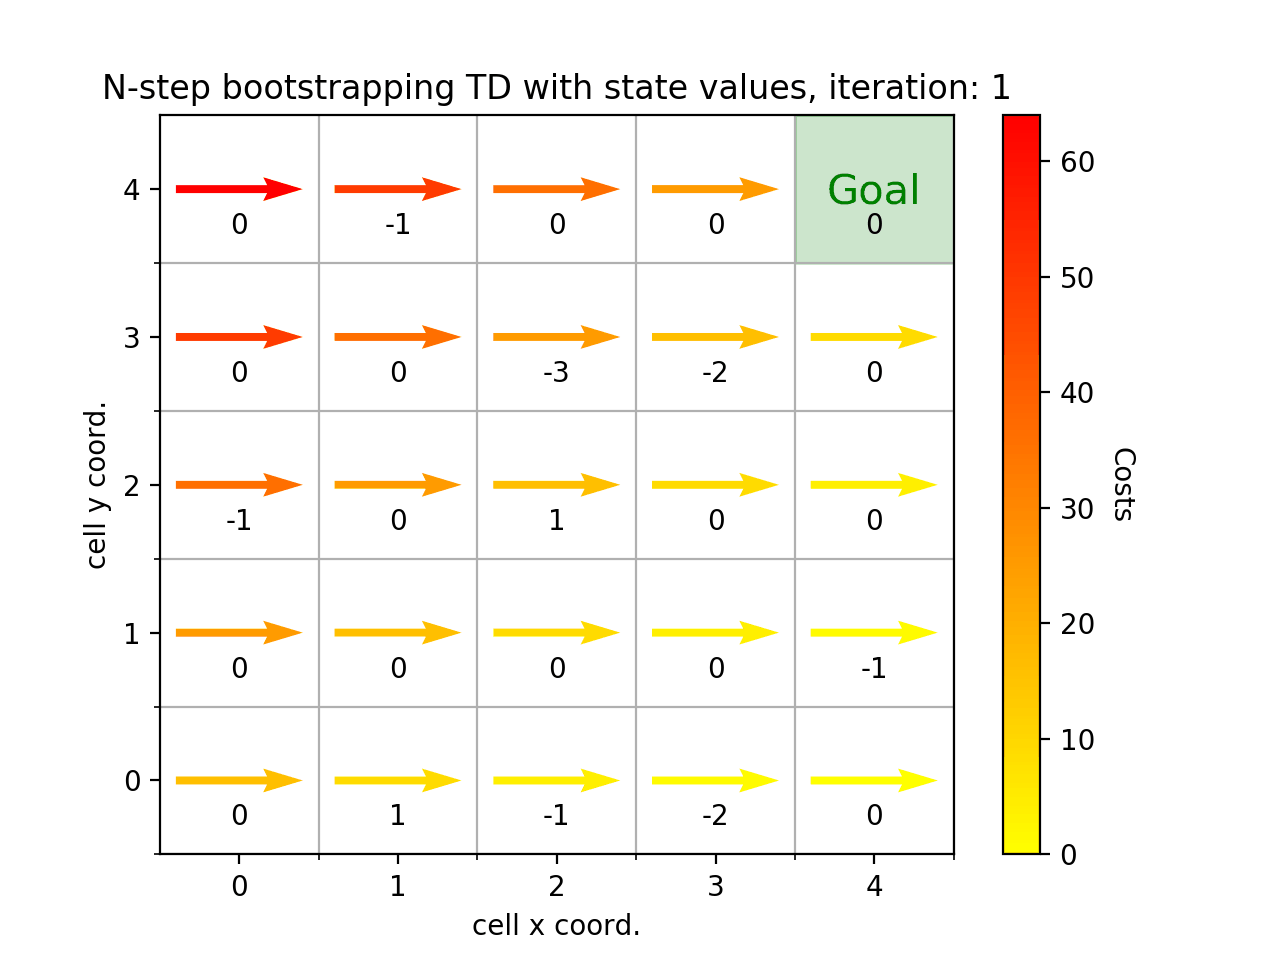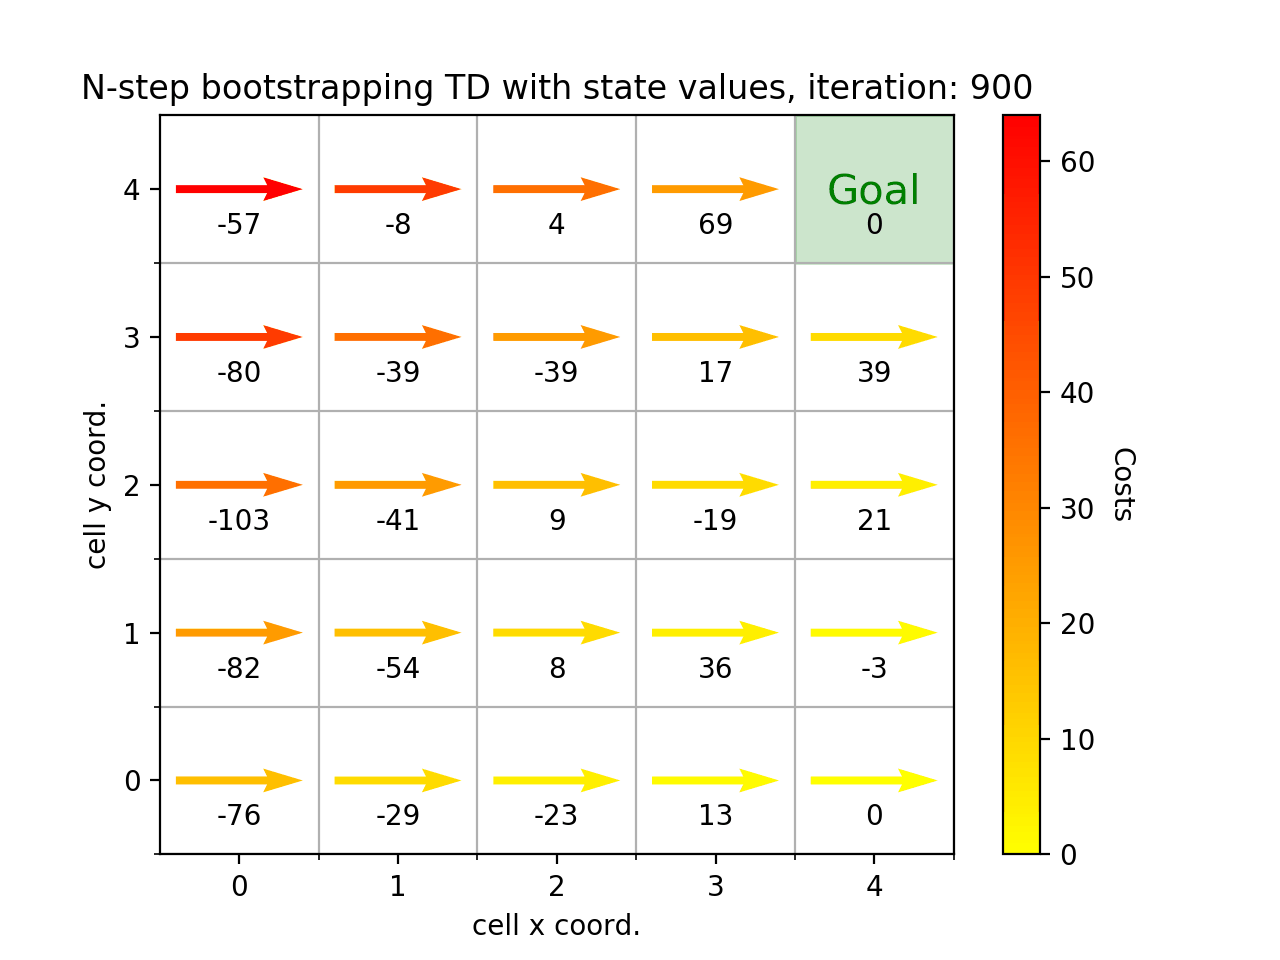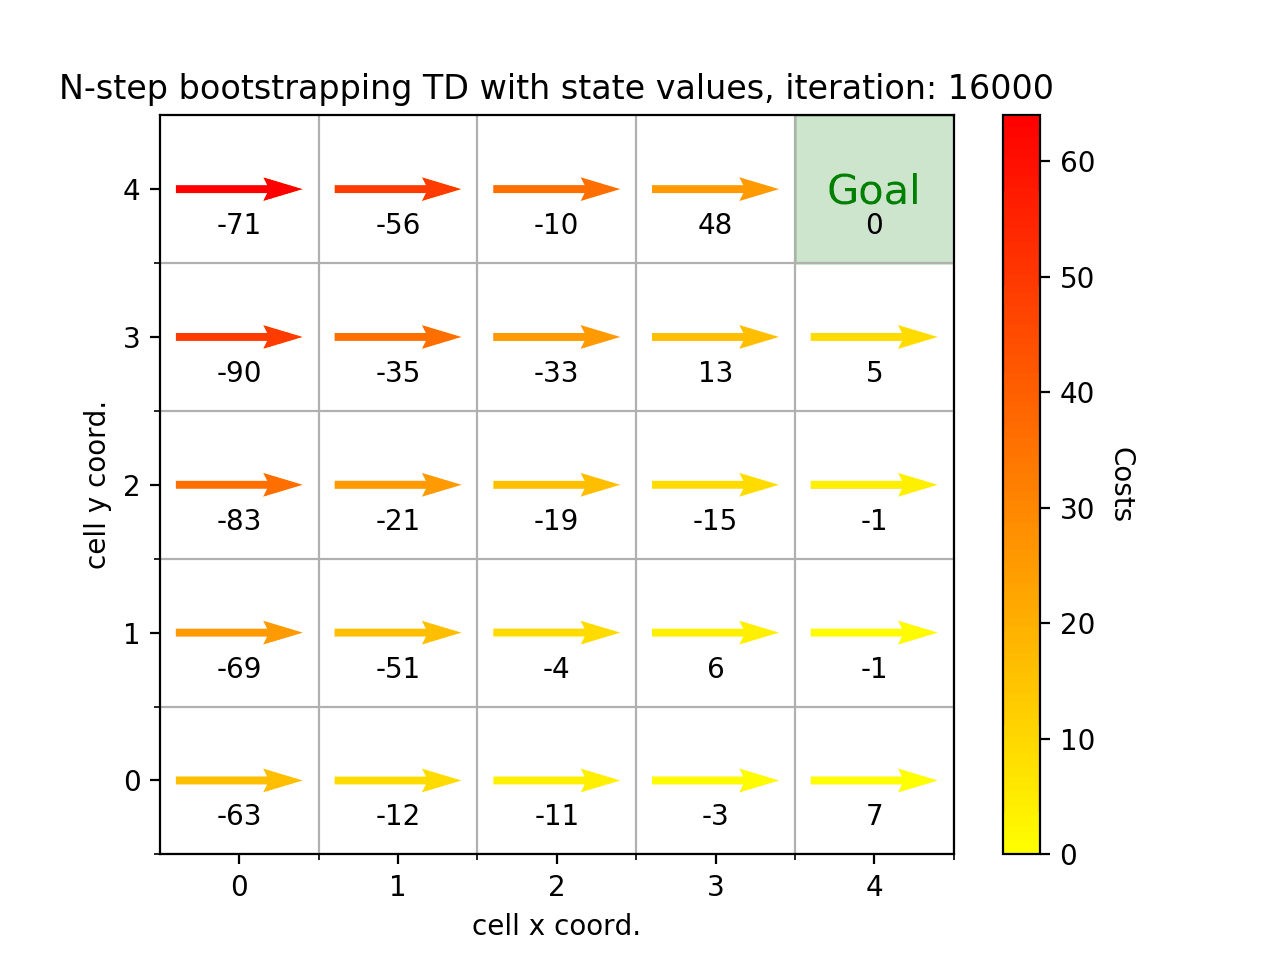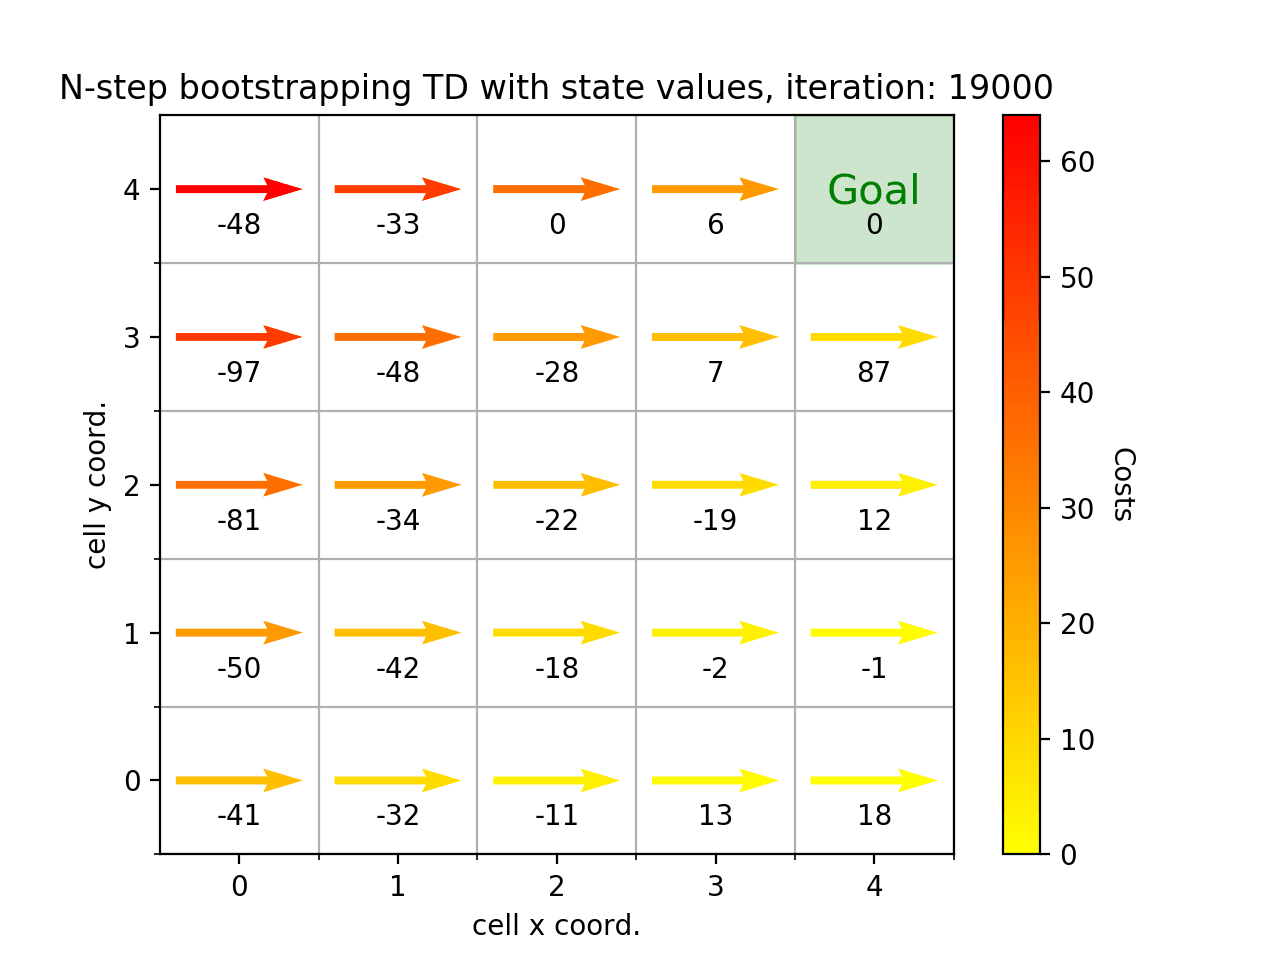
n-Step Bootstrapping TD algorithms on my gridworld problem.